Bump vendored EvalScope and add K3-ready DPV4 configs.
Keep K3 suite selection and report-schema scoring in bash, merge K3/vision dataset_args into dpv4 yamls, and pin EvalScope at 735d920ee911 with local patches.

Co-authored-by: Cursor <cursoragent@cursor.com>
This commit is contained in:
 sora
parent
d85e9986c8
commit
13274243a0
@ -16,6 +16,7 @@ import argparse
|
||||
import json
|
||||
import statistics
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
@ -322,15 +323,78 @@ def parse_log_duration(log_file: Path):
|
||||
return (last_dt - first_dt).total_seconds() / 3600.0
|
||||
|
||||
|
||||
def _metric_name(metric: dict) -> Optional[str]:
|
||||
"""Return a metric's display/key name across report schema v1 and v2."""
|
||||
if not isinstance(metric, dict):
|
||||
return None
|
||||
if metric.get('name'):
|
||||
return str(metric['name'])
|
||||
identity = metric.get('identity') or {}
|
||||
if isinstance(identity, dict) and identity.get('name'):
|
||||
return str(identity['name'])
|
||||
if metric.get('legacy_name'):
|
||||
return str(metric['legacy_name'])
|
||||
return None
|
||||
|
||||
|
||||
def _identity_key(identity: Optional[dict]) -> Optional[tuple]:
|
||||
if not isinstance(identity, dict) or not identity.get('name'):
|
||||
return None
|
||||
dims = identity.get('dimensions') or {}
|
||||
if not isinstance(dims, dict):
|
||||
dims = {}
|
||||
return (
|
||||
str(identity.get('name')),
|
||||
str(identity.get('aggregation') or 'mean'),
|
||||
tuple(sorted((str(k), str(v)) for k, v in dims.items())),
|
||||
)
|
||||
|
||||
|
||||
def extract_score(report_data: dict) -> float:
|
||||
"""Extract the top-level score from a report JSON."""
|
||||
"""Extract the primary score from a report JSON.
|
||||
|
||||
Supports:
|
||||
- legacy reports with top-level ``score`` / metrics named ``mean_acc``
|
||||
- EvalScope report schema v2 with ``primary_metric_identity`` +
|
||||
``metrics[].identity`` / ``metrics[].score``
|
||||
"""
|
||||
score = report_data.get('score')
|
||||
if score is not None:
|
||||
return float(score)
|
||||
metrics = report_data.get('metrics', [])
|
||||
|
||||
metrics = report_data.get('metrics') or []
|
||||
if not metrics:
|
||||
return 0.0
|
||||
|
||||
# Schema v2: prefer the explicit primary metric identity when present.
|
||||
primary_identity = report_data.get('primary_metric_identity')
|
||||
primary_key = _identity_key(primary_identity)
|
||||
if primary_key is not None:
|
||||
for m in metrics:
|
||||
if _identity_key(m.get('identity')) == primary_key:
|
||||
return float(m.get('score', m.get('macro_score', 0.0)))
|
||||
|
||||
# Legacy / fallback preferred names.
|
||||
preferred = {
|
||||
'mean_acc',
|
||||
'accuracy',
|
||||
'acc',
|
||||
'main_problem_pass_rate',
|
||||
'pass_rate',
|
||||
'normalized_score',
|
||||
'f1',
|
||||
}
|
||||
for m in metrics:
|
||||
if m.get('name') == 'mean_acc':
|
||||
name = _metric_name(m)
|
||||
if name in preferred:
|
||||
return float(m.get('score', m.get('macro_score', 0.0)))
|
||||
|
||||
# Last resort: first metric with a numeric score.
|
||||
for m in metrics:
|
||||
if m.get('score') is not None:
|
||||
return float(m.get('score'))
|
||||
if m.get('macro_score') is not None:
|
||||
return float(m.get('macro_score'))
|
||||
return 0.0
|
||||
|
||||
|
||||
@ -343,6 +407,9 @@ def collect_benchmark(output_dir: Path, benchmark: str, model_name: str):
|
||||
scores = []
|
||||
summary0 = None
|
||||
n_samples_unique = 0
|
||||
req_success = 0
|
||||
req_failed = 0
|
||||
req_client = 0
|
||||
for report in reports:
|
||||
try:
|
||||
data = json.loads(report.read_text(encoding='utf-8'))
|
||||
@ -351,6 +418,10 @@ def collect_benchmark(output_dir: Path, benchmark: str, model_name: str):
|
||||
perf_metrics = data.get('perf_metrics') or {}
|
||||
summary0 = perf_metrics.get('summary', {})
|
||||
n_samples_unique = summary0.get('n_samples', data.get('num', 0))
|
||||
req = ((data.get('perf_metrics') or {}).get('summary') or {}).get('request') or {}
|
||||
req_success += int(req.get('success_attempts') or 0)
|
||||
req_failed += int(req.get('failed_attempts') or 0)
|
||||
req_client += int(req.get('client_errors') or 0)
|
||||
except Exception:
|
||||
continue
|
||||
|
||||
@ -579,12 +650,19 @@ def collect_benchmark(output_dir: Path, benchmark: str, model_name: str):
|
||||
else:
|
||||
duration_hours = max(duration_hours, compute_wall_estimate)
|
||||
|
||||
vendor_http = req_success + req_failed
|
||||
request_success_rate = (req_success / vendor_http) if vendor_http > 0 else np.nan
|
||||
|
||||
return {
|
||||
'分类': BENCHMARK_DOMAIN.get(benchmark, '其他'),
|
||||
'Benchmark': BENCHMARK_NAME_ALIAS.get(benchmark, benchmark),
|
||||
'得分': round(avg_score, 4),
|
||||
'实测时间(h)': round(duration_hours, 4) if not np.isnan(duration_hours) else np.nan,
|
||||
'总样本数': n_samples_unique,
|
||||
'请求成功率': round(request_success_rate, 4) if not np.isnan(request_success_rate) else np.nan,
|
||||
'HTTP成功': req_success if vendor_http or req_client else np.nan,
|
||||
'HTTP失败': req_failed if vendor_http or req_client else np.nan,
|
||||
'client_errors': req_client if vendor_http or req_client else np.nan,
|
||||
'延迟_mean(s)': round(latency_mean, 5) if not np.isnan(latency_mean) else np.nan,
|
||||
'输出TPS': round(avg_output_tps, 2) if not np.isnan(avg_output_tps) else np.nan,
|
||||
'请求QPS': round(avg_req_ps, 4) if not np.isnan(avg_req_ps) else np.nan,
|
||||
|
||||
43
bash/run.py
43
bash/run.py
@ -127,7 +127,30 @@ ALL_SINGLE_RUN = [
|
||||
'openai_mrcr', 'longbench_v2',
|
||||
]
|
||||
ALL_AGENT = ['tau2_bench', 'general_fc']
|
||||
K3_SINGLE = ["gpqa_diamond", "hle", "terminal_bench_v2", "browsecomp", "mcp_atlas", "officeqa", "deepsearchqa", "jobbench", "automation_bench"]
|
||||
# Kimi-K3 可直接跑且备注为空的集 + HLE-Full(dataset id 为 hle)。
|
||||
# tau3 子集 banking_knowledge 在 config/kimi-k3.yaml 里配置。
|
||||
K3_SINGLE = [
|
||||
# Coding
|
||||
'deep_swe',
|
||||
'terminal_bench_v2_1',
|
||||
'scicode',
|
||||
# Agentic
|
||||
'browsecomp',
|
||||
'deepsearchqa',
|
||||
'job_bench',
|
||||
'officeqa',
|
||||
'tau3_bench',
|
||||
'researchrubrics',
|
||||
# Reasoning
|
||||
'gpqa_diamond',
|
||||
'aa_lcr',
|
||||
'hle',
|
||||
# Vision
|
||||
'mmmu_pro',
|
||||
'charxiv',
|
||||
'math_vision',
|
||||
'omni_doc_bench',
|
||||
]
|
||||
|
||||
# ============================================================
|
||||
# Fingerprint / model-identity benchmarks
|
||||
@ -558,6 +581,22 @@ def build_task_config(
|
||||
else:
|
||||
work_dir = Path(output_dir) / dataset_name / f'seed_{seed}'
|
||||
work_dir.mkdir(parents=True, exist_ok=True)
|
||||
# 升级后的 EvalScope:只要设置了 use_cache,就会校验 evaluation identity。
|
||||
# 空目录(无 task_config.yaml)会被当成 previous=unknown 直接报错;
|
||||
# 仅有 task_config、无 predictions 的失败/改配残留也会因 fingerprint 变化秒挂。
|
||||
# 仅在已有完整缓存快照(config + 至少一个 prediction)时才启用 resume。
|
||||
cache_snapshot = work_dir / 'configs' / 'task_config.yaml'
|
||||
pred_dir = work_dir / 'predictions'
|
||||
has_predictions = pred_dir.is_dir() and any(pred_dir.rglob('*'))
|
||||
if cache_snapshot.is_file() and has_predictions:
|
||||
use_cache = str(work_dir)
|
||||
else:
|
||||
if cache_snapshot.is_file() and not has_predictions:
|
||||
print(
|
||||
f' [cache] skip resume for {dataset_name}: '
|
||||
'stale/incomplete cache (task_config without predictions)'
|
||||
)
|
||||
use_cache = None
|
||||
work_dir = str(work_dir)
|
||||
|
||||
generation_config = configure_thinking(
|
||||
@ -599,7 +638,7 @@ def build_task_config(
|
||||
collect_perf=True,
|
||||
no_timestamp=True,
|
||||
work_dir=work_dir,
|
||||
use_cache=work_dir,
|
||||
use_cache=use_cache,
|
||||
datasets=[dataset_name],
|
||||
generation_config=generation_config,
|
||||
dataset_args=dataset_args_dict,
|
||||
|
||||
@ -203,16 +203,16 @@ swe_bench_pro:
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
terminal_bench_v2_1:
|
||||
generation_config:
|
||||
temperature: 0.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 8192
|
||||
dataset_args:
|
||||
extra_params:
|
||||
timeout_multiplier: 2.0
|
||||
max_turns: 500
|
||||
terminal_bench_v2_1:
|
||||
generation_config:
|
||||
temperature: 0.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 8192
|
||||
dataset_args:
|
||||
extra_params:
|
||||
timeout_multiplier: 2.0
|
||||
max_turns: 500
|
||||
aa_lcr:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
@ -269,4 +269,117 @@ toolathlon:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
extra_params:
|
||||
server_host: 127.0.0.1
|
||||
server_port: 8080
|
||||
ws_proxy_port: 8081
|
||||
timeout_seconds: 14400
|
||||
submit_timeout_seconds: 300
|
||||
task_list:
|
||||
- paper-checker
|
||||
skip_container_restart: false
|
||||
override_output_dir: true
|
||||
browsecomp:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
mcp_atlas:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
officeqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
subset_list:
|
||||
- officeqa_pro
|
||||
deepsearchqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
job_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
automation_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
extra_params:
|
||||
toolset: api
|
||||
mmmu_pro:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
max_image_bytes: 5mb
|
||||
extra_params:
|
||||
dataset_format: standard (4 options)
|
||||
charxiv:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
subset_list:
|
||||
- reasoning
|
||||
math_vision:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
baby_vision:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
zerobench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
max_image_bytes: 10mb
|
||||
world_vqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
omni_doc_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
dataset_args:
|
||||
extra_params:
|
||||
match_method: quick_match
|
||||
perception_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
|
||||
@ -299,3 +299,141 @@ toolathlon:
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
extra_params:
|
||||
server_host: 127.0.0.1
|
||||
server_port: 8080
|
||||
ws_proxy_port: 8081
|
||||
timeout_seconds: 14400
|
||||
submit_timeout_seconds: 300
|
||||
task_list:
|
||||
- paper-checker
|
||||
skip_container_restart: false
|
||||
override_output_dir: true
|
||||
terminal_bench_v2_1:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
extra_params:
|
||||
timeout_multiplier: 2.0
|
||||
max_turns: 500
|
||||
browsecomp:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
mcp_atlas:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
officeqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
subset_list:
|
||||
- officeqa_pro
|
||||
deepsearchqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
job_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
automation_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
extra_params:
|
||||
toolset: api
|
||||
mmmu_pro:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
max_image_bytes: 5mb
|
||||
extra_params:
|
||||
dataset_format: standard (4 options)
|
||||
charxiv:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
subset_list:
|
||||
- reasoning
|
||||
math_vision:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
baby_vision:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
zerobench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
max_image_bytes: 10mb
|
||||
world_vqa:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
omni_doc_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
dataset_args:
|
||||
extra_params:
|
||||
match_method: quick_match
|
||||
perception_bench:
|
||||
generation_config:
|
||||
temperature: 1.0
|
||||
top_p: 1.0
|
||||
stream: true
|
||||
max_tokens: 32768
|
||||
max_completion_tokens: 64000
|
||||
|
||||
@ -32,8 +32,10 @@ jobs:
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -e '.[dev,ifeval,ifbench,multi_if,needle_haystack,arena_hard]'
|
||||
pip install litellm==1.95.0
|
||||
pip install git+https://github.com/sierra-research/tau-bench
|
||||
pip install bfcl-eval==2025.10.27.1
|
||||
python -c "import tau_bench"
|
||||
|
||||
- name: Create .env file
|
||||
run: |
|
||||
|
||||
39
evalscope/.github/workflows/code-review.yaml
vendored
Normal file
39
evalscope/.github/workflows/code-review.yaml
vendored
Normal file
@ -0,0 +1,39 @@
|
||||
name: Qoder Auto Code Review
|
||||
|
||||
# Manually triggered: add the "qoder-review" label to a PR. This avoids running
|
||||
# on every commit (the previous `synchronize` trigger) and lets a maintainer
|
||||
# decide when a review is needed. Because the trigger is pull_request_target,
|
||||
# the job is natively associated with the PR head and shows up as a PR check.
|
||||
on:
|
||||
pull_request_target:
|
||||
types: [labeled]
|
||||
|
||||
jobs:
|
||||
qoder-review:
|
||||
# Only run when the label added is exactly "qoder-review". Adding a label
|
||||
# requires write/triage access, so the labeling action is itself the human
|
||||
# gate that authorizes running fork PR code in this trusted context.
|
||||
if: github.event.label.name == 'qoder-review'
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
pull-requests: write
|
||||
id-token: write
|
||||
|
||||
steps:
|
||||
- name: Checkout PR head
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.event.pull_request.head.sha }}
|
||||
# Fork code checkout is opted in; the qoder-review label (settable only
|
||||
# by trusted users) is the gate that makes this safe.
|
||||
allow-unsafe-pr-checkout: true
|
||||
|
||||
- name: Run Qoder Code Review
|
||||
uses: QoderAI/qoder-action@v0
|
||||
with:
|
||||
qoder_personal_access_token: ${{ secrets.QODER_PERSONAL_ACCESS_TOKEN }}
|
||||
prompt: |
|
||||
/review-pr
|
||||
REPO:${{ github.repository }} PR_NUMBER:${{ github.event.pull_request.number }}
|
||||
71
evalscope/.github/workflows/frontend.yml
vendored
Normal file
71
evalscope/.github/workflows/frontend.yml
vendored
Normal file
@ -0,0 +1,71 @@
|
||||
name: Frontend checks
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'evalscope/web/**'
|
||||
- 'evalscope/service/**'
|
||||
- 'evalscope/report/report.py'
|
||||
- 'evalscope/api/agent/trace.py'
|
||||
- 'evalscope/api/metric/**'
|
||||
- 'evalscope/constants.py'
|
||||
- 'scripts/generate_web_api_contracts.py'
|
||||
- 'tests/service/test_api_contracts.py'
|
||||
- 'tests/report/test_report_endpoints.py'
|
||||
- 'requirements/dev.txt'
|
||||
- 'requirements/service.txt'
|
||||
- 'pyproject.toml'
|
||||
- 'DESIGN.md'
|
||||
- '.github/workflows/frontend.yml'
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- 'evalscope/web/**'
|
||||
- 'evalscope/service/**'
|
||||
- 'evalscope/report/report.py'
|
||||
- 'evalscope/api/agent/trace.py'
|
||||
- 'evalscope/api/metric/**'
|
||||
- 'evalscope/constants.py'
|
||||
- 'scripts/generate_web_api_contracts.py'
|
||||
- 'tests/service/test_api_contracts.py'
|
||||
- 'tests/report/test_report_endpoints.py'
|
||||
- 'requirements/dev.txt'
|
||||
- 'requirements/service.txt'
|
||||
- 'pyproject.toml'
|
||||
- 'DESIGN.md'
|
||||
- '.github/workflows/frontend.yml'
|
||||
|
||||
jobs:
|
||||
frontend:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
- uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
cache: pip
|
||||
|
||||
- name: Install Python contract dependencies
|
||||
run: pip install -e '.[dev,service]'
|
||||
|
||||
- uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: 24
|
||||
cache: npm
|
||||
cache-dependency-path: evalscope/web/package-lock.json
|
||||
|
||||
- run: npm ci
|
||||
working-directory: evalscope/web
|
||||
- run: npm run contracts:check
|
||||
working-directory: evalscope/web
|
||||
- run: python -m pytest tests/service/test_api_contracts.py tests/report/test_report_endpoints.py
|
||||
- run: npm run lint
|
||||
working-directory: evalscope/web
|
||||
- run: npm test
|
||||
working-directory: evalscope/web
|
||||
- run: npm run drift
|
||||
working-directory: evalscope/web
|
||||
- run: npm run build
|
||||
working-directory: evalscope/web
|
||||
4
evalscope/.github/workflows/lint.yml
vendored
4
evalscope/.github/workflows/lint.yml
vendored
@ -26,7 +26,7 @@ jobs:
|
||||
- name: Install pre-commit
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install pre-commit
|
||||
pip install 'pre-commit==4.6.0'
|
||||
|
||||
- name: Run pre-commit
|
||||
run: pre-commit run --all-files
|
||||
run: pre-commit run --all-files --show-diff-on-failure
|
||||
|
||||
14
evalscope/.github/workflows/publish.yaml
vendored
14
evalscope/.github/workflows/publish.yaml
vendored
@ -25,13 +25,9 @@ jobs:
|
||||
uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: '22'
|
||||
- name: Build frontend
|
||||
run: make web-build
|
||||
- name: Install wheel
|
||||
run: pip install wheel && pip install -r requirements/framework.txt
|
||||
- name: Build EvalScope
|
||||
run: python setup.py sdist bdist_wheel
|
||||
- name: Install build dependencies
|
||||
run: pip install build twine '.[service]'
|
||||
- name: Build and verify EvalScope
|
||||
run: make package
|
||||
- name: Publish package to PyPI
|
||||
run: |
|
||||
pip install twine
|
||||
twine upload dist/* --skip-existing -u __token__ -p ${{ secrets.PYPI_TOKEN }}
|
||||
run: twine upload dist/* --skip-existing -u __token__ -p ${{ secrets.PYPI_TOKEN }}
|
||||
|
||||
11
evalscope/.gitignore
vendored
11
evalscope/.gitignore
vendored
@ -133,6 +133,7 @@ result.mp4
|
||||
|
||||
# personal info
|
||||
private/
|
||||
outreach/
|
||||
|
||||
# others
|
||||
*.tokenization
|
||||
@ -165,6 +166,9 @@ docs/zh/learn/
|
||||
examples/api_test/
|
||||
.qoder
|
||||
.claude
|
||||
.kiro
|
||||
.pr-review/
|
||||
.scratch_wl/
|
||||
|
||||
# Frontend (evalscope/web)
|
||||
node_modules/
|
||||
@ -172,13 +176,6 @@ evalscope/web/dist/
|
||||
evalscope/web/.vite/
|
||||
ragas_mini_testset_score.json
|
||||
|
||||
# User benchmark outputs and secrets
|
||||
benchmark_outputs/
|
||||
test_scripts/
|
||||
*.secret
|
||||
*.key
|
||||
api_keys.json
|
||||
|
||||
# Docker build artifacts (pre-cloned agent sources)
|
||||
evalscope/agent/external/dockerfiles/hermes-agent-src/
|
||||
evalscope/agent/external/dockerfiles/hermes-install.sh
|
||||
|
||||
@ -1,52 +1,23 @@
|
||||
repos:
|
||||
- repo: https://github.com/pycqa/flake8.git
|
||||
rev: 7.3.0
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.16.4
|
||||
hooks:
|
||||
- id: flake8
|
||||
exclude: |
|
||||
(?x)^(
|
||||
examples/|
|
||||
docs/|
|
||||
tests/|
|
||||
evalscope/utils/utils.py|
|
||||
evalscope/third_party/|
|
||||
evalscope/backend/rag_eval/clip_benchmark/tasks|
|
||||
evalscope/backend/rag_eval/cmteb/tasks|
|
||||
evalscope/metrics/vision/t2v_metrics
|
||||
)
|
||||
- repo: https://github.com/PyCQA/isort.git
|
||||
rev: 7.0.0
|
||||
hooks:
|
||||
- id: isort
|
||||
- repo: https://github.com/google/yapf
|
||||
rev: v0.43.0
|
||||
hooks:
|
||||
- id: yapf
|
||||
exclude: |
|
||||
(?x)^(
|
||||
examples/|
|
||||
docs/|
|
||||
tests/|
|
||||
evalscope/utils/utils.py|
|
||||
evalscope/third_party/|
|
||||
evalscope/backend/rag_eval/clip_benchmark/tasks|
|
||||
evalscope/backend/rag_eval/cmteb/tasks
|
||||
)
|
||||
- id: ruff-check
|
||||
args: [--fix]
|
||||
- id: ruff-format
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks.git
|
||||
rev: v6.0.0
|
||||
hooks:
|
||||
- id: trailing-whitespace
|
||||
exclude: thirdparty/|docs/|examples
|
||||
exclude: evalscope/third_party/|docs/|examples
|
||||
- id: check-yaml
|
||||
exclude: thirdparty/|docs/|examples
|
||||
exclude: evalscope/third_party/|docs/|examples
|
||||
- id: end-of-file-fixer
|
||||
exclude: thirdparty/|docs/|examples|.*\.json
|
||||
exclude: evalscope/third_party/|docs/|examples|.*\.json
|
||||
- id: requirements-txt-fixer
|
||||
exclude: thirdparty/|docs/|examples
|
||||
- id: double-quote-string-fixer
|
||||
exclude: thirdparty/|docs/|examples|.*\.json|cl_bench_adapter.py
|
||||
exclude: evalscope/third_party/|docs/|examples
|
||||
- id: check-merge-conflict
|
||||
exclude: thirdparty/|docs/|examples
|
||||
exclude: evalscope/third_party/|docs/|examples
|
||||
- id: mixed-line-ending
|
||||
exclude: thirdparty/|docs/|examples
|
||||
exclude: evalscope/third_party/|docs/|examples
|
||||
args: ["--fix=lf"]
|
||||
|
||||
@ -14,7 +14,7 @@ Python ≥ 3.10 (3.10 / 3.11 / 3.12). Dependencies: `requirements/framework.txt`
|
||||
## Build, lint, test
|
||||
|
||||
```bash
|
||||
make lint # required before commit (yapf + isort + flake8 + basic pre-commit hooks)
|
||||
make lint # apply Ruff fixes/formatting and run all pre-commit checks
|
||||
pytest tests/cli/test_all.py::TestRun::test_ci_lite -v -s -p no:warnings # CI smoke test
|
||||
pytest tests/perf/test_perf_basic.py::TestPerfBasic::test_multi_parallel_sweep -v -s # perf
|
||||
```
|
||||
@ -25,6 +25,15 @@ Commits failing `make lint` are rejected on `main`.
|
||||
|
||||
Benchmark detail pages (`docs/{zh,en}/benchmarks/<name>.md`) and meta cache (`evalscope/benchmarks/_meta/<name>.json`) are **auto-generated** from each adapter's `BenchmarkMeta.description` + dataset statistics. Do not hand-edit those files.
|
||||
|
||||
Every `BenchmarkMeta.description` must be English Markdown with these sections in this order:
|
||||
|
||||
1. `## Overview`: benchmark purpose and scope.
|
||||
2. `## Task Description`: bullet fields for `Task Type`, `Input`, `Output`, and `Domain` (use a more precise fourth field such as `Modalities` or `Grading` only when `Domain` does not apply).
|
||||
3. `## Key Features`: dataset scale/source, evaluated capabilities, and version-specific behavior.
|
||||
4. `## Evaluation Notes`: metrics, scoring procedure, runtime/dependency requirements, and compatibility limits.
|
||||
|
||||
Do not replace these required headings with benchmark-specific headings. Add extra sections only when the four required sections are insufficient.
|
||||
|
||||
When you add a benchmark or change its `BenchmarkMeta.description`, run:
|
||||
|
||||
```bash
|
||||
@ -54,9 +63,10 @@ run_task(TaskConfig(model='Qwen/Qwen2.5-0.5B-Instruct', datasets=['gsm8k'], limi
|
||||
## Code style (enforced)
|
||||
|
||||
- **Line width 120**, 4-space indent, LF endings, trailing newline at EOF.
|
||||
- **Quotes** governed by `double-quote-string-fixer` hook — follow existing file style; do not mix.
|
||||
- **Quotes**: single quotes, enforced by the Ruff formatter.
|
||||
- **Linting**: Ruff's `E`, `F`, and `W` rules for maintained source files.
|
||||
- **Imports**: Ruff's `I` rules, with `evalscope` detected as first-party and standard import sections.
|
||||
- **f-strings** for formatting (no `%` or `.format()` unless necessary).
|
||||
- **Imports**: isort with `first_party = evalscope`, groups `STDLIB / THIRDPARTY / LOCALFOLDER`, `multi_line_output=3`.
|
||||
- **Type hints required** on every function signature.
|
||||
- **English only** for comments and docstrings.
|
||||
- **Public APIs need docstrings**; internal helpers only when intent is non-obvious.
|
||||
@ -71,13 +81,14 @@ run_task(TaskConfig(model='Qwen/Qwen2.5-0.5B-Instruct', datasets=['gsm8k'], limi
|
||||
| Handler function | `handle_` prefix |
|
||||
| Benchmark adapter file | `<name>_adapter.py` |
|
||||
|
||||
**flake8 ignore list** (`setup.cfg`): `F401, F403, F405, F821, W503, E251, W504, F824, F541, E501, E226, E121-E129, E131, E741`. Do not expand — new ignores must be justified in the PR.
|
||||
**Ruff ignore list** (`pyproject.toml`): `E501, F401`. Do not expand — new ignores must be justified in the PR.
|
||||
|
||||
## Design rules
|
||||
|
||||
- **Early returns** over nested conditionals.
|
||||
- **Minimal changes**: only touch code related to the current task; no drive-by cleanup.
|
||||
- **Pydantic-first**: cross-module data contracts use Pydantic models. Use `TaskConfig` / `Arguments` for configuration — never raw dicts at module boundaries.
|
||||
- **Web API responses**: successful JSON responses consumed by the dashboard use models from `evalscope/service/api_models/` and `json_response()`. Regenerate frontend contracts with `cd evalscope/web && npm run contracts:generate`; never hand-edit generated artifacts or add parallel response schemas.
|
||||
- **Reuse existing patterns**: new benchmarks / models / metrics go through existing registries and adapter base classes — no parallel mechanisms.
|
||||
- **DRY** but don't over-abstract just to remove minor duplication.
|
||||
|
||||
@ -100,10 +111,11 @@ Don't try to learn the architecture from this file — read these and grep:
|
||||
| Model layer | `evalscope/api/model/model.py`, `evalscope/models/model_apis.py` |
|
||||
| CLI dispatch | `evalscope/cli/` |
|
||||
| Cache schema | `evalscope/api/evaluator/cache.py` |
|
||||
| Web API response contracts | `evalscope/service/api_models/`, `evalscope/service/responses.py`, `evalscope/web/src/api/generated/` |
|
||||
|
||||
**Registry decorators**: `@register_benchmark`, `@register_model_api`, `@register_metric`, `@register_aggregation`, `@register_filter`, `@register_evaluator`.
|
||||
|
||||
**Adapter base classes** (extend, don't reinvent): `DefaultDataAdapter`, `MultiChoiceAdapter`, `VisionLanguageAdapter`, `Text2ImageAdapter`, `ImageEditAdapter`, `NERAdapter`, `AgentAdapter`. Optional capabilities via mixins: `LLMJudgeMixin`, `SandboxMixin`.
|
||||
**Adapter base classes** (extend, don't reinvent): `DefaultDataAdapter`, `MultiChoiceAdapter`, `VisionLanguageAdapter`, `Text2ImageAdapter`, `ImageEditAdapter`, `NERAdapter`, `AgentAdapter`. Optional capabilities via mixins: `LLMJudgeMixin`, `CodeExecutionSandboxMixin`.
|
||||
|
||||
**Non-native backends** live under `evalscope/backend/` (OpenCompass, VLMEvalKit, RAGEval) and are dispatched from `run.py` with their own BackendManager.
|
||||
|
||||
@ -111,9 +123,33 @@ Don't try to learn the architecture from this file — read these and grep:
|
||||
|
||||
1. Create `evalscope/benchmarks/<name>/<name>_adapter.py`.
|
||||
2. Extend `DefaultDataAdapter`, override `record_to_sample()` (and optionally `sample_to_fewshot()`, `extract_answer()`).
|
||||
3. Decorate with `@register_benchmark(BenchmarkMeta(name=..., ...))`.
|
||||
4. Auto-discovered by globbing `evalscope/benchmarks/*/**/*_adapter.py`.
|
||||
5. Add a smoke test.
|
||||
3. Reuse the standard dataset flow (`load_subset()` and existing `DataLoader` implementations) for shuffle, limit, repeats, filtering, conversion, and indexing. Override the full `load()` flow only when the standard loaders cannot represent the source format, and keep custom loading limited to benchmark-specific parsing or validation.
|
||||
4. Use `download_dataset_file()` or `download_dataset_snapshot()` for benchmark media and raw files; do not duplicate hub resolution, cache, path-safety, or download state inside an adapter.
|
||||
5. Decorate with `@register_benchmark(BenchmarkMeta(name=..., ...))`.
|
||||
6. Auto-discovered by globbing `evalscope/benchmarks/*/**/*_adapter.py`.
|
||||
7. Add a smoke test.
|
||||
|
||||
### Evaluation versioning
|
||||
|
||||
`BenchmarkMeta.evaluation_version` is the published version of a benchmark's evaluation semantics. New benchmarks
|
||||
must declare their initial version explicitly. Raise the minor version when data, sample conversion, default prompt,
|
||||
choice/target mapping, default scoring/judge, or aggregation semantics change; raise the major version for a rename
|
||||
or task-definition replacement. Documentation, tests, and pure refactors do not change it.
|
||||
|
||||
## Adding a judge-scored benchmark
|
||||
|
||||
An adapter must **never** call `self.llm_judge.judge()` or parse a judge reply itself — that debt is fenced off by `tests/api/judge/test_gates.py`, which scans every file under `evalscope/benchmarks/` (helpers included, so moving a parser into `utils.py` does not evade it). Score through the JSON output contract in `evalscope/api/judge/` instead:
|
||||
|
||||
1. Pick a `scoring_policy` (`JUDGE_ONLY` or `JUDGE_DEFAULT`). Judge scoring always goes through the contract; there is no opt-in flag and no legacy path.
|
||||
2. **Single verdict per sample:** implement `judge_definition(context)` and return `JudgeDefinition.labels(...)` for a label mapping or `JudgeDefinition.numeric(...)` for a 0-1 rating. A generic `prompt_template` must state grading criteria only: `OutputContract.instruction()` appends the reply format. An adapter that preserves an official fixed output template may keep that format instruction instead, provided its `OutputContract` schema matches the official template.
|
||||
3. **Custom shape (multiple cases, ratings, rubrics):** `judge_definition(context)` declares a Pydantic `schema_model`, wraps it in `OutputContract`, and returns `JudgeDefinition.workflow(...)`:
|
||||
- `cases` contains one `JudgeCase(case_id, output_contract, metadata)` per thing to judge.
|
||||
- `request(case, placement, completed, context)` renders messages and appends `case.output_contract.instruction()` so the prompt and parser cannot drift. An official fixed output template may be used instead when its required fields and constraints match the case's `OutputContract` schema.
|
||||
- `reduce(verdicts, context)` folds parsed verdicts into `{metric: value}`. Read a verdict's context from `CaseVerdict.metadata`, never by parsing `case_id`.
|
||||
- Optional `expand`, `fallback`, and `finalize` callbacks handle staged cases, rule fallbacks, and score finalization. They may be nested functions or private adapter helpers, but are passed only through the returned definition.
|
||||
4. **Rule short-circuit:** if deterministic scoring settles the sample before judge I/O, return `JudgeDefinition.skip(score, reason='...')`. The non-empty reason is persisted in `Score.metadata` as `judge_skipped=True` and `judge_skip_reason`; the web review panel displays it as rule-based scoring.
|
||||
5. The executor owns request execution, position swap, repeats, multi-judge aggregation and fail-closed exclusion. Transport retries belong to the model implementation; a reply that fails the contract is not automatically retried and excludes the sample from the metric — never scored 0 or full credit — so a metric's `num` can be below the sample count.
|
||||
6. Add a scripted-judge test in `tests/api/judge/test_migrated_adapters.py` covering: a valid verdict, a parse failure (prose / malformed), and a transport `[ERROR]` — each must exclude, not silently score. A judge double must carry the surface the definition reads (`score_type`, `score_mapping`, `build_prompt`), and be injected through the `llm_judge` setter rather than a private attribute.
|
||||
|
||||
## Conventions & gotchas
|
||||
|
||||
@ -122,7 +158,7 @@ Don't try to learn the architecture from this file — read these and grep:
|
||||
- `repeats`: duplicates items for k-metrics. `generation_config.n` is deprecated and mapped.
|
||||
- Use `generation_config` for runtime params. `TaskConfig.timeout` / `stream` are deprecated — forwarded with a warning.
|
||||
- `dataset_args` merges into `BenchmarkMeta._update()` (supports `local_path`, `filters` OrderedDict prepended).
|
||||
- Models are memoized by `(name, config, base_url, api_key, args)`.
|
||||
- Models are memoized by `(name, eval_type, config, base_url, api_key, args)`.
|
||||
- Use `@thread_safe` for model creation, `run_in_threads_with_progress` for concurrent eval.
|
||||
- Outputs land in `outputs/<timestamp>/{logs,predictions,reviews,reports,configs}/` (see `OutputsStructure`). `use_cache` resumes runs; `rerun_review` recomputes scores only.
|
||||
- `evalscope app` CLI command is **deprecated** (see `evalscope/cli/start_app.py`) — use `evalscope service` for the Web dashboard.
|
||||
@ -131,6 +167,6 @@ Don't try to learn the architecture from this file — read these and grep:
|
||||
|
||||
```bash
|
||||
make dev # once
|
||||
make lint # before every commit
|
||||
make lint # apply fixes and run all checks before every commit
|
||||
pytest tests/cli/test_all.py::TestRun::test_ci_lite -v -s -p no:warnings
|
||||
```
|
||||
|
||||
@ -99,6 +99,20 @@ The dev server runs at `http://localhost:5173` and automatically proxies `/api/v
|
||||
|
||||
**Tech stack:** React 19 · TypeScript · Vite · Tailwind CSS 4 · React Router · Plotly.js
|
||||
|
||||
#### Web API response contracts
|
||||
|
||||
Backend Pydantic models in `evalscope/service/api_models/` are the single source of truth for successful JSON responses consumed by the dashboard. Route handlers validate those payloads with `json_response()` before serialization; the frontend uses generated TypeScript types rather than hand-written response schemas.
|
||||
|
||||
After changing a Web API response model, regenerate and commit both generated artifacts:
|
||||
|
||||
```bash
|
||||
cd evalscope/web
|
||||
npm run contracts:generate
|
||||
npm run contracts:check
|
||||
```
|
||||
|
||||
Do not edit `src/api/generated/contracts.ts` or `contracts.schema.json` by hand. `make web-contracts-check` performs the same drift check from the repository root and is part of the release build. Error responses and non-JSON responses such as HTML reports and media files remain outside this generated response contract.
|
||||
|
||||
### Full-Stack Development
|
||||
|
||||
For the best development experience, run both servers simultaneously:
|
||||
@ -306,18 +320,21 @@ evalscope service
|
||||
|
||||
This project uses **pre-commit** with the following hooks:
|
||||
|
||||
- **flake8** — Python style checker
|
||||
- **isort** — Import sorting
|
||||
- **yapf** — Code formatting
|
||||
- Trailing whitespace, YAML checks, line ending fixes
|
||||
- **Ruff check** — Python linting (`E`, `F`, and `W`) and import sorting (`I`)
|
||||
- **Ruff format** — Python code formatting with 120-character lines and single quotes
|
||||
- Trailing whitespace, YAML checks, and line ending fixes
|
||||
|
||||
Ruff's lint hook runs before its formatter so that any automatic fixes are formatted consistently. Pre-commit is installed by `make dev` with the version pinned in `requirements/dev.txt`.
|
||||
|
||||
```bash
|
||||
# Run all checks
|
||||
# Apply safe fixes, format maintained Python files, and run all repository checks
|
||||
make lint
|
||||
# or
|
||||
pre-commit run --all-files
|
||||
```
|
||||
|
||||
If pre-commit modifies files, review and stage those changes, then run `make lint` again. The configured Ruff scope and exclusions are defined in `pyproject.toml`.
|
||||
|
||||
### Testing
|
||||
|
||||
```bash
|
||||
@ -342,9 +359,9 @@ pytest tests/benchmark/test_xxx.py
|
||||
git commit -m "feat: add MyBenchmark adapter"
|
||||
```
|
||||
|
||||
3. **Run quality checks** before pushing:
|
||||
3. **Run quality checks before pushing:**
|
||||
```bash
|
||||
pre-commit run --all-files
|
||||
make lint
|
||||
pytest tests/
|
||||
```
|
||||
|
||||
|
||||
@ -4,7 +4,7 @@ colors:
|
||||
# Brand & Accent — IDENTICAL across both themes. Violet is the brand constant.
|
||||
accent: "#816DF8"
|
||||
accent-dark: "#5B3FD6"
|
||||
accent-dim: "rgba(129,109,248,0.12)"
|
||||
accent-dim: "rgba(129, 109, 248, 0.12)"
|
||||
purple: "#a78bfa"
|
||||
|
||||
# Surface ladder (sunken → elevated) — DARK
|
||||
@ -12,7 +12,7 @@ colors:
|
||||
bg-deep: "#09091a"
|
||||
bg-card: "#12122b"
|
||||
bg-card2: "#16163a"
|
||||
surface-glass: "rgba(18,18,43,0.7)"
|
||||
surface-glass: "rgba(18, 18, 43, 0.7)"
|
||||
|
||||
# Text (3-step ladder) — DARK
|
||||
text: "#e2e8f0"
|
||||
@ -21,9 +21,9 @@ colors:
|
||||
on-filled: "#ffffff"
|
||||
|
||||
# Hairline borders — DARK (translucent violet, the near-black bg lets even 10% read)
|
||||
border: "rgba(129,109,248,0.10)"
|
||||
border-md: "rgba(129,109,248,0.18)"
|
||||
border-strong: "rgba(129,109,248,0.28)"
|
||||
border: "rgba(129, 109, 248, 0.10)"
|
||||
border-md: "rgba(129, 109, 248, 0.18)"
|
||||
border-strong: "rgba(129, 109, 248, 0.28)"
|
||||
|
||||
# Semantic states
|
||||
success: "#10b981"
|
||||
@ -42,26 +42,26 @@ colors:
|
||||
# ────────────────────────────────────────────────────────────────
|
||||
|
||||
# Surface ladder — warm-cream, sunken → elevated
|
||||
bg-light: "#faf9f5" # warm cream canvas — was cool #f5f6fa
|
||||
bg-deep-light: "#f0ebe1" # input wells, one step below canvas — was cool #e8eaf2
|
||||
bg-card-light: "#ffffff" # pure white — strongest possible contrast against cream canvas
|
||||
bg-card2-light: "#f5f0e7" # hover / elevated — warm cream-soft, was cool #eef0f7
|
||||
surface-glass-light: "rgba(250,249,245,0.80)" # warm-tinted glass — was pure white
|
||||
bg-light: "#faf9f5" # warm cream canvas — was cool #f5f6fa
|
||||
bg-deep-light: "#f0ebe1" # input wells, one step below canvas — was cool #e8eaf2
|
||||
bg-card-light: "#ffffff" # pure white — strongest possible contrast against cream canvas
|
||||
bg-card2-light: "#f5f0e7" # hover / elevated — warm cream-soft, was cool #eef0f7
|
||||
surface-glass-light: "rgba(250, 249, 245, 0.80)" # warm-tinted glass — was pure white
|
||||
|
||||
# Accent (unchanged from dark — violet is the brand constant)
|
||||
accent-light: "#6c57e8"
|
||||
accent-dim-light: "rgba(108,87,232,0.14)" # slightly stronger on white card
|
||||
accent-dim-light: "rgba(108, 87, 232, 0.14)" # slightly stronger on white card
|
||||
|
||||
# Text — warm-ink ladder
|
||||
text-light: "#141413" # warm near-black — was cool #1a1f2e
|
||||
text-muted-light: "#6c6a64" # warm grey — was cool #5a6378
|
||||
text-dim-light: "#8e8b82" # warm grey — was cool #7c8497
|
||||
text-light: "#141413" # warm near-black — was cool #1a1f2e
|
||||
text-muted-light: "#6c6a64" # warm grey — was cool #5a6378
|
||||
text-dim-light: "#8e8b82" # warm grey — was cool #7c8497
|
||||
|
||||
# Hairlines — SOLID warm hex, not translucent violet. Three concrete tones.
|
||||
# Critical: translucent violet at 0.20 alpha composites to near-invisible
|
||||
# on white cards. Solid warm-grey gives every card a definite boundary.
|
||||
border-light: "#e6dfd8" # standard hairline — was rgba(violet,0.20)
|
||||
border-md-light: "#d6cdbe" # emphasized — was rgba(violet,0.30)
|
||||
border-light: "#e6dfd8" # standard hairline — was rgba(violet,0.20)
|
||||
border-md-light: "#d6cdbe" # emphasized — was rgba(violet,0.30)
|
||||
border-strong-light: "#c1b6a3" # hover / focus boundary — was rgba(violet,0.40)
|
||||
|
||||
# Compare slot accents (per-model tagging in compare view)
|
||||
@ -115,7 +115,7 @@ typography:
|
||||
lineHeight: 1.4
|
||||
table-xs:
|
||||
fontFamily: System Sans
|
||||
fontSize: 10px
|
||||
fontSize: 12px
|
||||
fontWeight: 600
|
||||
letterSpacing: 0.05em
|
||||
textTransform: uppercase
|
||||
@ -155,11 +155,11 @@ fontFamily:
|
||||
mono: 'ui-monospace, SFMono-Regular, "SF Mono", Menlo, Consolas, "Liberation Mono", "DejaVu Sans Mono", "Courier New", monospace'
|
||||
rounded:
|
||||
none: 0px
|
||||
xs: 4px
|
||||
sm: 8px
|
||||
md: 12px
|
||||
lg: 16px
|
||||
xl: 20px
|
||||
xs: "4px"
|
||||
sm: "8px"
|
||||
md: "12px"
|
||||
lg: "16px"
|
||||
xl: "20px"
|
||||
full: 9999px
|
||||
spacing:
|
||||
xs: 4px
|
||||
@ -173,31 +173,27 @@ spacing:
|
||||
5xl: 64px
|
||||
shadows:
|
||||
# Dark theme — single deep drop (works on near-black surfaces).
|
||||
sm: "0 2px 8px rgba(0,0,0,0.4)"
|
||||
md: "0 4px 20px rgba(0,0,0,0.55)"
|
||||
lg: "0 8px 40px rgba(0,0,0,0.6)"
|
||||
glow: "0 0 20px rgba(129,109,248,0.25)"
|
||||
glow-soft: "0 0 12px rgba(129,109,248,0.2)"
|
||||
sm: "0 2px 8px rgba(0, 0, 0, 0.4)"
|
||||
md: "0 4px 20px rgba(0, 0, 0, 0.55)"
|
||||
lg: "0 8px 40px rgba(0, 0, 0, 0.6)"
|
||||
glow: "0 0 20px rgba(129, 109, 248, 0.25)"
|
||||
glow-soft: "0 0 12px rgba(129, 109, 248, 0.20)"
|
||||
# Light theme — two-stop stacks tinted with warm-ink (matches text colour),
|
||||
# not slate. Slate-tinted drops on cream read as a cool-grey smudge and break
|
||||
# the warm canvas. Warm-ink stays consistent with the rest of the palette.
|
||||
sm-light: "0 1px 2px rgba(20,20,19,0.04), 0 4px 12px rgba(20,20,19,0.06)"
|
||||
md-light: "0 4px 16px rgba(20,20,19,0.07), 0 12px 32px rgba(20,20,19,0.05)"
|
||||
lg-light: "0 12px 24px rgba(20,20,19,0.09), 0 24px 48px rgba(20,20,19,0.07)"
|
||||
glow-light: "0 0 20px rgba(108,87,232,0.22)"
|
||||
glow-soft-light: "0 0 12px rgba(108,87,232,0.18)"
|
||||
sm-light: "0 1px 2px rgba(20, 20, 19, 0.04), 0 4px 12px rgba(20, 20, 19, 0.06)"
|
||||
md-light: "0 4px 16px rgba(20, 20, 19, 0.07), 0 12px 32px rgba(20, 20, 19, 0.05)"
|
||||
lg-light: "0 12px 24px rgba(20, 20, 19, 0.09), 0 24px 48px rgba(20, 20, 19, 0.07)"
|
||||
glow-light: "0 0 20px rgba(108, 87, 232, 0.22)"
|
||||
glow-soft-light: "0 0 12px rgba(108, 87, 232, 0.18)"
|
||||
gradients:
|
||||
brand: "linear-gradient(135deg, #816DF8 0%, #a78bfa 100%)"
|
||||
accent: "linear-gradient(135deg, #0F9C7E 0%, #06b6d4 100%)"
|
||||
surface: "linear-gradient(135deg, rgba(129,109,248,0.08) 0%, rgba(167,139,250,0.05) 100%)"
|
||||
kpi-0: "linear-gradient(135deg, #6366f1, #8b5cf6)"
|
||||
kpi-1: "linear-gradient(135deg, #10b981, #06b6d4)"
|
||||
kpi-2: "linear-gradient(135deg, #f59e0b, #f97316)"
|
||||
kpi-3: "linear-gradient(135deg, #ec4899, #8b5cf6)"
|
||||
nav-hairline: "linear-gradient(90deg, transparent 0%, #816DF8 50%, transparent 100%)"
|
||||
transition:
|
||||
fast: "150ms cubic-bezier(0.4, 0, 0.2, 1)"
|
||||
base: "180ms ease"
|
||||
base: "250ms cubic-bezier(0.4, 0, 0.2, 1)"
|
||||
slow: "400ms cubic-bezier(0.4, 0, 0.2, 1)"
|
||||
breakpoints:
|
||||
sm: 640px
|
||||
@ -216,7 +212,9 @@ score-formula:
|
||||
|
||||
# Design System: EvalScope Console
|
||||
|
||||
## Overview
|
||||
## Principles {#principles}
|
||||
|
||||
> **Addressable section — `principles`.** The design philosophy, brand posture, and dual-theme parity rules that govern every downstream decision. See also the normative *Do's and Don'ts* under [Decision Records](#decisions).
|
||||
|
||||
EvalScope's web dashboard is a developer-platform brand for **LLM evaluation and benchmarking** — the page is an instrument panel for engineers running evals, written for people who already know the syntax. It earns that posture through **two equally weighted themes** rather than one canonical mode with a translated companion. Both themes share the same vocabulary — same type, same spacing, same radii, same components — but each carries its own surface philosophy. They are two voices of one brand, not one design re-tinted.
|
||||
|
||||
@ -226,26 +224,30 @@ EvalScope's web dashboard is a developer-platform brand for **LLM evaluation and
|
||||
|
||||
The brand constant across both themes is the single violet `{colors.accent}` (`#816DF8` dark / `#6c57e8` light) used for primary CTAs, active nav states, focus rings, and the wordmark accent — plus the dynamic HSL score gradient (`hsl(score × 120, 70%, 45%)`) that maps a 0-1 metric to red → yellow → green. Both signals work over either canvas. Everything else — surface ladder, hairline material, shadow tint, on-canvas text colour — is theme-specific by design, because dark and light surfaces need *different* materials to produce the same hierarchy.
|
||||
|
||||
Type is the second decisive voice and is **theme-agnostic**. The brand uses cross-platform system font stacks (no web font is loaded) — `system-ui, -apple-system, "Segoe UI", Roboto, ...` for narrative and `ui-monospace, SFMono-Regular, Menlo, Consolas, "Liberation Mono", ...` for technical labels. Each OS resolves to its own native UI face. Headlines are sentence-case with `tracking-tight` on display numbers; **all-caps + `tracking-wider`** is reserved for tiny section eyebrows (12 px / 10 px), never headlines. Weight ceiling is **700**; the working set is 400 / 500 / 600 / 700.
|
||||
Type is the second decisive voice and is **theme-agnostic**. The brand uses cross-platform system font stacks (no web font is loaded) — `system-ui, -apple-system, "Segoe UI", Roboto, ...` for narrative and `ui-monospace, SFMono-Regular, Menlo, Consolas, "Liberation Mono", ...` for technical labels. Each OS resolves to its own native UI face. Headlines are sentence-case with `tracking-tight` on display numbers; **all-caps + `tracking-wider`** is reserved for 12 px section eyebrows and table labels, never headlines. Weight ceiling is **700**; the working set is 400 / 500 / 600 / 700.
|
||||
|
||||
**Key Characteristics:**
|
||||
|
||||
- **Dual-theme parity, not dual-theme translation.** Dark uses translucent violet hairlines on near-black; light uses solid warm-grey hairlines on cream. They produce the same hierarchy through opposite material choices. Theme is persisted to `localStorage` and applied via `data-theme` on `<html>` before first paint to avoid a flash.
|
||||
- A single violet primary CTA `{colors.accent}` carries every conversion target on both themes, paired with a transparent **ghost** secondary. The brand uses a `{rounded.sm}` 8-px button shape for primary/secondary in the *console* (no marketing pills — this is an in-product surface).
|
||||
- The primary CTA **glows on hover** with violet at 20-25 % alpha on both themes. That violet glow is the brand's signature interaction — identical animation, identical colour, identical timing across themes.
|
||||
- Every card section title, form label, and table header sets in `{typography.label-xs}` — 12 px (10 px for tables), `font-semibold`, **UPPERCASE**, `tracking-wider`, muted color. Body and titles stay sentence-case. The contrast between these two voices does most of the hierarchy work.
|
||||
- Every card section title, form label, and table header is at least 12 px, `font-semibold`, **UPPERCASE**, `tracking-wider`, and uses the AA-safe muted color. Body and titles stay sentence-case. The contrast between these two voices does most of the hierarchy work.
|
||||
- A dynamic HSL **score chip** (`hsl(score × 120, 70%, 45%)`) is the second-most-recognizable component after the brand violet — it is how the product communicates pass/fail. Identical formula on both themes; the chip's saturation works over cream and over near-black.
|
||||
- **Light theme uses solid hex hairlines, not translucent violet.** This is the most important light-theme rule, and the one most often broken on first attempt: a violet alpha overlay disappears into a near-white page, so light surfaces require concrete warm-grey edges (`#e6dfd8` / `#d6cdbe` / `#c1b6a3`) to keep their boundaries.
|
||||
- A complete domain token set exists for **chat bubbles** (5 semantic roles: user / bot / tool / reasoning / system), **compare slots** (3 per-model accent colors), and **KPI gradients** (4 named gradient pairs) — these are first-class brand tokens, not ad-hoc colors.
|
||||
- A complete domain token set exists for **chat bubbles** (5 semantic roles: user / bot / tool / reasoning / system) and **compare slots** (3 per-model accent colors) — these are first-class brand tokens, not ad-hoc colors.
|
||||
- A glassmorphic sticky top-nav (52 px, 12 px backdrop-blur, 1-px violet-to-transparent gradient hairline along the top edge) is the only "marketing-y" flourish the product allows itself. Dark uses translucent indigo glass; light uses translucent cream glass.
|
||||
|
||||
## Colors
|
||||
## Design Tokens {#tokens}
|
||||
|
||||
> **Addressable section — `tokens`.** The executable token reference: color, typography, layout, elevation, and shape scales. Runtime CSS custom properties in `evalscope/web/src/index.css` are the source of truth. `npm run design:tokens` synchronizes the matching frontmatter values, while the drift check fails CI when the generated documentation is stale.
|
||||
|
||||
### Colors
|
||||
|
||||
> **Note on dual theme.** Every color token below has a *dark* (default) and *light* value. Hex pairs are listed as `dark / light`. Components reference tokens by name — never by raw hex — so theme switching is free.
|
||||
>
|
||||
> **Light values use SOLID hex for hairlines, not translucent violet.** This is the structural difference from earlier light-theme generations and the single most-broken light-theme rule. See `{colors.border-light}` below and *Elevation & Depth* for the reason.
|
||||
|
||||
### Brand & Accent
|
||||
#### Brand & Accent
|
||||
|
||||
The accent family is **identical in spirit on both themes** — a single violet handles every conversion target. Slightly different hex values per theme (the dark violet is brighter to read on near-black; the light violet is a half-step deeper to hold weight against white cards) but the same brand voltage.
|
||||
|
||||
@ -255,7 +257,7 @@ The accent family is **identical in spirit on both themes** — a single violet
|
||||
- **Violet Mist** (`{colors.accent-dim}` — `rgba(129,109,248,0.12)` / `rgba(108,87,232,0.14)`): The low-alpha violet used as pill background and focus-ring fill. Light theme runs slightly stronger (0.14 vs 0.12) because white cards need a touch more saturation to read the mist.
|
||||
- **Violet Glow** (`{shadows.glow}` — `0 0 20px rgba(129,109,248,0.25)` / `0 0 20px rgba(108,87,232,0.22)`): The signature hover halo on primary buttons and active nav. Same effect, same magnitude, on both themes.
|
||||
|
||||
### Surface
|
||||
#### Surface
|
||||
|
||||
Each theme operates with a 4-step surface ladder, sunken-to-elevated. The **ladder structure is shared**; the **material is different** — dark walks an indigo ladder, light walks a warm-cream ladder. The semantic of each step is the same: `bg-deep` is *below* the page, `bg-card` is the working surface, `bg-card2` is the elevated state.
|
||||
|
||||
@ -265,20 +267,20 @@ Each theme operates with a 4-step surface ladder, sunken-to-elevated. The **ladd
|
||||
- **Card Elevated** (`{colors.bg-card2}` — `#16163a` / `#f5f0e7`): Hover state for clickable cards and rows; also the inactive-tab fill in pill-tab containers. Light theme's elevated state is warm-cream-soft — the elevated state is darker on dark theme but lighter-than-card-but-warmer on light theme (the white card with a soft-cream hover reads as "depressed into the cream canvas").
|
||||
- **Glass** (`{colors.surface-glass}` — `rgba(18,18,43,0.7)` / `rgba(250,249,245,0.80)`): Translucent surface for the sticky top-nav, used with a 12-px backdrop-blur. Light theme uses tinted cream glass (matches the canvas), NOT pure white — white glass on cream reads as a foreign sheet floating in space.
|
||||
|
||||
### Text
|
||||
#### Text
|
||||
|
||||
- **Ink** (`{colors.text}` — `#e2e8f0` / `#141413`): All headings, body, table cell values, button labels on non-filled surfaces. Light theme uses warm-near-black (`#141413`, ≈ the same value Claude.com uses) rather than a cool slate (`#1a1f2e`), so the text temperature matches the canvas temperature.
|
||||
- **Muted** (`{colors.text-muted}` — `#8896aa` / `#6c6a64`): Secondary labels, nav-link inactive text, card-header micro-labels, button "ghost" idle text. *This is also the color section-eyebrow uppercase labels are set in.* Light theme uses warm-grey (`#6c6a64`) rather than cool-slate (`#5a6378`) to stay coherent with the warm canvas.
|
||||
- **Dim** (`{colors.text-dim}` — `#7a8195` / `#8e8b82`): Lowest-priority text — placeholder text, timestamps in compact rows, table empty-state. **Contrast tuned to ~3.6 : 1** against `{colors.bg-card}` on both themes — sits just above the WCAG AA Large floor (3 : 1), still **below AA Normal (4.5 : 1)**. ⚠️ Reserve for ≥ 14 px non-essential metadata. Light theme uses a warm-grey at the same luminance step as the dark theme's cool-grey — the perceived hierarchy stays identical.
|
||||
- **On Filled** (`{colors.on-filled}` — `#ffffff` / `#ffffff`): Text on `{colors.accent}` and other saturated fills. Identical on both themes — the violet CTA is dark enough on both that white text holds.
|
||||
|
||||
### Hairlines (the structural difference between themes)
|
||||
#### Hairlines (the structural difference between themes)
|
||||
|
||||
- **Border** (`{colors.border}` — `rgba(129,109,248,0.10)` / `#e6dfd8`): The default 1-px card / input / divider boundary. **Dark uses translucent violet at 10 % alpha** because the near-black bg-to-card luminance step already does most of the boundary work — the violet hairline just tints it. **Light uses a SOLID warm-grey hex** (`#e6dfd8`, Claude-style cream-hairline) because the white-card-on-cream luminance step is gentle enough that a translucent violet overlay disappears into the page. Borders on light theme are concrete materials, not tints.
|
||||
- **Border Emphasized** (`{colors.border-md}` — `rgba(129,109,248,0.18)` / `#d6cdbe`): One step stronger — used on form inputs after focus, on the active-state of hover cards, on the boundary between a card and a nested section.
|
||||
- **Border Strong** (`{colors.border-strong}` — `rgba(129,109,248,0.28)` / `#c1b6a3`): The strongest boundary — used by `{components.card-hover}` on hover lift, and by elevated cards in modal contexts. On both themes this is the "this thing is grabbing attention" hairline.
|
||||
|
||||
### Semantic
|
||||
#### Semantic
|
||||
|
||||
- **Success** (`{colors.success}` — `#10b981` / `#059669`) / **Success Bg** (`rgba(16,185,129,0.08)`) / **Success Border** (`rgba(16,185,129,0.20)`): Confirmed / passed states; success toasts; chat-bot bubble border.
|
||||
- **Warning** (`{colors.warning}` — `#f59e0b` / `#d97706`) / **Warning Bg** (`rgba(245,158,11,0.08)`) / **Warning Border** (`rgba(245,158,11,0.20)`): Pending / caution; tool-call chat bubbles.
|
||||
@ -286,7 +288,7 @@ Each theme operates with a 4-step surface ladder, sunken-to-elevated. The **ladd
|
||||
- **Info** (`{colors.info}` — `#60a5fa` / `#3b82f6`): Latency chart series, informational toasts.
|
||||
- **Pass** (`{colors.pass}` — `rgb(45,104,62)` / `rgb(16,108,55)`) / **Fail** (`{colors.fail}` — `rgb(151,31,44)` / `rgb(180,30,42)`): Deep saturated greens / crimsons for boolean pass/fail badges where the tone needs more weight than the soft semantic family.
|
||||
|
||||
### Score Gradient (Signature)
|
||||
#### Score Gradient (Signature)
|
||||
|
||||
The product's emotional core. A 0-1 score maps to **`hsl(score × 120, 70%, 45%)`**: 0 → red, 0.5 → yellow, 1 → green. Used as both foreground and translucent background on score chips, dataset chips, and group-header best-score callouts. This is computed inline (`scoreColor` / `scoreBg` helpers), never stored as a static palette. **Treat the formula as a brand asset** — do not reskin to a 5-step bucket, do not introduce a 4th hue.
|
||||
|
||||
@ -302,7 +304,7 @@ Foreground uses HSL for predictable hue progression; background uses an RGB-inte
|
||||
|
||||
**Score Ring** (`{components.score-ring}` — SVG circular progress used in `<ReportSummaryStats>` and the "Overall Score" callout in `<DetailsTab>`): the active arc is `stroke={scoreColor(score)}`. Stroke width must be **≥6 px** for the 48 × 48 mini ring and **8 px** for the 72 × 80 summary ring — anything thinner reduces the colored area to the point where the mid-hue olive stops carrying. Background arc uses `var(--border)` for a neutral track.
|
||||
|
||||
### Compare Slots
|
||||
#### Compare Slots
|
||||
|
||||
Three per-model accent colors used to tag side-by-side model comparisons. Each slot has a `dot`, `border`, `bg`, and `bg-header` tint at ~10-30 % alpha:
|
||||
|
||||
@ -312,7 +314,7 @@ Three per-model accent colors used to tag side-by-side model comparisons. Each s
|
||||
|
||||
If a comparison view exceeds 3 models, *do not invent a 4th brand color* — collapse into a numbered legend instead.
|
||||
|
||||
### Chat Bubble Roles
|
||||
#### Chat Bubble Roles
|
||||
|
||||
Five semantic roles, each with a complete 7-token set (`bg`, `bg-hl`, `border`, `border-hl`, `icon-bg`, `icon-border`, `color`):
|
||||
|
||||
@ -324,20 +326,15 @@ Five semantic roles, each with a complete 7-token set (`bg`, `bg-hl`, `border`,
|
||||
|
||||
Bubble containers are `{rounded.md}` with the role's tint background and border; hover/highlight states use the `*-hl` variants.
|
||||
|
||||
### KPI Gradients
|
||||
#### KPI Icon Tile
|
||||
|
||||
Four named linear gradients for the four hero KPI tiles on the dashboard:
|
||||
The four hero KPI tiles on the dashboard share one hue: the 40 × 40 `{rounded.md}` icon tile is filled with `{colors.accent-dim}` and its glyph inked in `{colors.accent}`, on both themes.
|
||||
|
||||
- **Indigo→Violet** (`{gradients.kpi-0}` — `linear-gradient(135deg, #6366f1, #8b5cf6)`)
|
||||
- **Emerald→Teal** (`{gradients.kpi-1}` — `linear-gradient(135deg, #10b981, #06b6d4)`)
|
||||
- **Amber→Orange** (`{gradients.kpi-2}` — `linear-gradient(135deg, #f59e0b, #f97316)`)
|
||||
- **Pink→Violet** (`{gradients.kpi-3}` — `linear-gradient(135deg, #ec4899, #8b5cf6)`)
|
||||
**Do not introduce a per-KPI hue.** The four counters are the same kind of quantity, so distinct hues would assert a distinction that does not exist, and would put the loudest colour in the app on its least specific numbers. A hue is reserved for values that carry a meaning, such as `{chart.*}` for perf-metric series or the score scale.
|
||||
|
||||
Always applied to the 40 × 40 `{rounded.md}` icon tile inside a `{components.kpi-card}`. **Same gradient values on both themes** — they're saturated enough to work over either canvas.
|
||||
#### Chart Palette (Perf Metrics)
|
||||
|
||||
### Chart Palette (Perf Metrics)
|
||||
|
||||
Four hue tokens used to mark perf-metric series (latency / TTFT / TPOT / token-usage) across the KPI strip, the chart series legends, and the percentile-table accent headers in `<PerfMetricsPanel>`. **The two themes use different RGB values for the same hue** — unlike the KPI gradients, these aren't shared across themes:
|
||||
Four hue tokens used to mark perf-metric series (latency / TTFT / TPOT / token-usage) across the KPI strip, the chart series legends, and the percentile-table accent headers in `<PerfMetricsPanel>`. **The two themes use different RGB values for the same hue:**
|
||||
|
||||
- **Latency** (`{chart.latency}` — `#60a5fa` dark / `#2563eb` light)
|
||||
- **TTFT** (`{chart.ttft}` — `#34d399` dark / `#047857` light)
|
||||
@ -348,15 +345,15 @@ Four hue tokens used to mark perf-metric series (latency / TTFT / TPOT / token-u
|
||||
|
||||
**KPI strip surface**: the strip in `<PerfMetricsPanel>` uses `{colors.bg-card}` (matching the outer card), not `{colors.bg-deep}`. On light theme, `{colors.bg-deep}` is even warmer than the cards and pushes the chart hues into the warm-on-warm range — losing the contrast that makes the colored numbers carry. Visual separation comes from the border + dividers, not bg differentiation.
|
||||
|
||||
### Brand Gradients (Decorative)
|
||||
#### Brand Gradients (Decorative)
|
||||
|
||||
- **Brand** (`{gradients.brand}` — `linear-gradient(135deg, #816DF8 → #a78bfa)`): For `gradient-text` and large brand moments.
|
||||
- **Accent** (`{gradients.accent}` — `linear-gradient(135deg, #0F9C7E → #06b6d4)`): For the optional emerald-to-cyan accent text.
|
||||
- **Surface** (`{gradients.surface}` — `linear-gradient(135deg, rgba(129,109,248,0.08) → rgba(167,139,250,0.05))`): The subtle violet wash layered behind KPI cards via `::before`.
|
||||
|
||||
## Typography
|
||||
### Typography
|
||||
|
||||
### Font Family
|
||||
#### Font Family
|
||||
|
||||
Two cross-platform **system font stacks** carry the entire system — each OS resolves to its own native UI face. No `@font-face` is loaded; this is deliberate. Each stack starts with the modern CSS `system-ui` / `ui-monospace` generic family and falls back to named faces for older browsers and per-OS targets:
|
||||
|
||||
@ -365,23 +362,23 @@ Two cross-platform **system font stacks** carry the entire system — each OS re
|
||||
|
||||
Antialiasing is forced (`-webkit-font-smoothing: antialiased`). No web font is loaded — the brand reads as "native developer tool, not marketing site" precisely because of this. The trade-off is per-OS rendering variance; if pixel-identical screenshots across platforms are required, see *Note on Font Substitutes* below.
|
||||
|
||||
### Hierarchy
|
||||
#### Hierarchy
|
||||
|
||||
| Token | Size | Weight | Tracking | Use |
|
||||
|---|---|---|---|---|
|
||||
| `{typography.display-xl}` | 24px | 700 | tight | KPI value, hero number (dashboard `{components.kpi-card}`). |
|
||||
| `{typography.display-xl}` | 24px | 700 | tight | Hero number where a single figure is the whole message. |
|
||||
| `{typography.title-md}` | 16px | 700 | normal | Card-title model name, group-header titles, brand wordmark. |
|
||||
| `{typography.body-sm}` | 14px | 400 / 500 | normal | Default body text, button-md label, table-cell text, paragraph copy. |
|
||||
| `{typography.label-xs}` | 12px | 600 | wider | **UPPERCASE** card-section header, form label, badge text — the brand's signature eyebrow. |
|
||||
| `{typography.body-xs}` | 12px | 400 / 500 | normal | Empty-state hint, pill / badge body, mobile-nav link. |
|
||||
| `{typography.table-xs}` | 10px | 600 | wider | **UPPERCASE** table-header micro-text — whispers, doesn't shout. |
|
||||
| `{typography.table-xs}` | 12px | 600 | wider | **UPPERCASE** table-header text; never smaller because headers are essential. |
|
||||
| `{typography.caption-mono}` | 12px | 400 (mono) | normal | Timestamps, score values, dataset names in chips. |
|
||||
| `{typography.code}` | 13–14px | 400 (mono) | normal | Log viewer, JSON viewer, terminal-style output. |
|
||||
| `{typography.button-sm}` | 12px | 500 | normal | `{components.button}` `size="sm"`. |
|
||||
| `{typography.button-md}` | 14px | 500 | normal | `{components.button}` `size="md"` (default). |
|
||||
| `{typography.button-lg}` | 16px | 500 | normal | `{components.button}` `size="lg"` — for hero callouts only. |
|
||||
|
||||
### Principles
|
||||
#### Principles
|
||||
|
||||
- **UPPERCASE + `tracking-wider` is the eyebrow voice — never the headline voice.** It marks "this introduces a region." Card titles, model names, and KPI labels stay sentence-case (or lower-case for the brand wordmark's lowercase "v").
|
||||
- **`tracking-tight` is reserved for the display tier** — KPI numbers and the brand wordmark only. It tells the reader "this is set big on purpose."
|
||||
@ -390,16 +387,16 @@ Antialiasing is forced (`-webkit-font-smoothing: antialiased`). No web font is l
|
||||
- **Line-heights inherit Tailwind defaults** (1.5 for body, 1.25 for headings). Don't override globally; rely on padding for vertical rhythm in tight stacks (cards, chips).
|
||||
- **No web font.** The system stack is the system. Loading Inter or Geist on top would break the "native console" feel.
|
||||
|
||||
### Note on Font Substitutes
|
||||
#### Note on Font Substitutes
|
||||
|
||||
EvalScope uses the OS-native stack, so there are no proprietary faces to substitute. If a future skin needs to enforce a *single* face across all OSes for screenshot consistency:
|
||||
|
||||
- **Sans substitute** — *Inter* (400 / 500 / 600 / 700) is the closest stylistic match to the SF-on-macOS rendering; preserves the geometric / neutral character.
|
||||
- **Mono substitute** — *JetBrains Mono* (400) at 12–14 px matches the technical voice well; *IBM Plex Mono* is a close second.
|
||||
|
||||
## Layout
|
||||
### Layout
|
||||
|
||||
### Spacing System
|
||||
#### Spacing System
|
||||
|
||||
- **Base unit**: 4 px (Tailwind's default scale).
|
||||
- **Tokens** (Tailwind-aligned):
|
||||
@ -409,7 +406,7 @@ EvalScope uses the OS-native stack, so there are no proprietary faces to substit
|
||||
- **Inline gap**: `{spacing.md}` (12 px) for component rows inside a card, `{spacing.xl}` (20 px) for inter-section gaps between major page blocks.
|
||||
- **Pill / chip gap**: `{spacing.sm}` (6-8 px) — tight, scan-friendly. Pills are meant to wrap.
|
||||
|
||||
### Grid & Container
|
||||
#### Grid & Container
|
||||
|
||||
- **Max width**: `1600px` (`max-w-[1600px]`). Centered (`mx-auto`). Wide enough for 4-up KPI strip + side-by-side comparison; narrow enough that line-length never sprawls.
|
||||
- **Column patterns**:
|
||||
@ -419,7 +416,7 @@ EvalScope uses the OS-native stack, so there are no proprietary faces to substit
|
||||
- **Form pairs**: `grid-cols-1 md:grid-cols-2` for label-value pairs.
|
||||
- **Gutters**: 16 px horizontal at all sizes.
|
||||
|
||||
### Whitespace Philosophy
|
||||
#### Whitespace Philosophy
|
||||
|
||||
Whitespace separates the *bands* — not the components inside a band. Section spacing is generous (`flex flex-col gap-5` → 20 px between major blocks); card interiors are tight (`gap-2` / `gap-3` between rows inside a card). The page reads as engineered — *large gaps + tight interior, never the other way around*. The dark page lets cards float visually without needing margin to assert themselves; the hairline border does the bordering work.
|
||||
|
||||
@ -428,9 +425,9 @@ The brand's voice is **information-rich but uncluttered** — a typical dashboar
|
||||
2. UPPERCASE eyebrows visually section the layout without horizontal rules.
|
||||
3. Score chips compress a percentage + benchmark name + color signal into 6 characters of mono.
|
||||
|
||||
### Responsive Strategy
|
||||
#### Responsive Strategy
|
||||
|
||||
#### Breakpoints (Tailwind defaults)
|
||||
##### Breakpoints (Tailwind defaults)
|
||||
|
||||
| Name | Width | Key Changes |
|
||||
|---|---|---|
|
||||
@ -440,11 +437,13 @@ The brand's voice is **information-rich but uncluttered** — a typical dashboar
|
||||
| Desktop | 1024–1279px | Full pill-style nav with icon + label; KPI strip goes 4-up. |
|
||||
| Wide | ≥ 1280px | Container holds at `max-w-[1600px]`; bands stretch but content centers. |
|
||||
|
||||
#### Touch Targets
|
||||
##### Touch Targets
|
||||
|
||||
The top-nav icon-only buttons (tablet) are 32 × 32 — *under the 44 × 44 WCAG floor*. This is a known compromise for the developer-tool density; on actual touch devices, hit areas are extended via padding. Primary buttons reach ~36 px tall in `md` size and ~44 px in `lg` — meet the floor at `lg`.
|
||||
**Normative rule (executable, enforced — see [Component Contracts](#component-contracts)).** Every primary `Pointer_Target` — navigation, mobile menu, compare-selection, and disclosure controls — MUST expose a hit area of **≥ 44 × 44 CSS px on coarse pointers**. This is a hard floor asserted by the E2E/axe suite at the 390 px viewport, **not** a documented known-failure or accepted compromise.
|
||||
|
||||
#### Collapsing Strategy
|
||||
The *visual* chrome may be smaller than the *hit area*, and only the hit area is governed by the rule. The top-nav icon-only buttons (tablet) render a 32 × 32 visual box, but on coarse pointers their tappable region is expanded to ≥ 44 × 44 via symmetric padding / an `::before` hit-area overlay — the icon stays 32 × 32, the target does not shrink below the floor. Primary buttons reach ~36 px tall in `md` and ~44 px in `lg`; where an `md` button is a primary `Pointer_Target` on touch, it is promoted to the 44 px hit area by the same rule.
|
||||
|
||||
##### Collapsing Strategy
|
||||
|
||||
- **Nav**: Desktop = pill-row with icon + label; tablet = icon-only pills; mobile = logo + hamburger toggling a stacked drop-down (`max-height` animated, 300 ms).
|
||||
- **KPI strip**: 4-up → 2-up below `lg`. Each tile keeps its `{rounded.md}` 12-px shape and 20-px padding.
|
||||
@ -452,13 +451,13 @@ The top-nav icon-only buttons (tablet) are 32 × 32 — *under the 44 × 44 WCAG
|
||||
- **Forms**: Two-column label/value at `md+`, single column below.
|
||||
- **Table**: Horizontal scroll wrapper preserves all columns rather than dropping them. The card-shell border keeps the scroll area framed.
|
||||
|
||||
#### Image / Icon Behavior
|
||||
##### Image / Icon Behavior
|
||||
|
||||
- **Iconography**: `lucide-react`, almost always 14–18 px, color inherits `currentColor`. The only non-Lucide mark is the brand SVG in the top-nav (a hand-drawn triangle with an amber check, rendered with `currentColor` so it follows theme).
|
||||
- **No marketing imagery**: This is a console — no hero photo, no customer-logo strip, no illustrated empty-states. Empty states use a single Lucide icon in a 64 × 64 `{rounded.lg}` deep-well tile.
|
||||
- **Charts**: Plotly-based, theme-aware — chart series colors are `{colors.chart-*}` tokens (latency / TTFT / TPOT / token).
|
||||
|
||||
## Elevation & Depth
|
||||
### Elevation & Depth
|
||||
|
||||
| Level | Treatment | Use |
|
||||
|---|---|---|
|
||||
@ -473,16 +472,16 @@ The top-nav icon-only buttons (tablet) are 32 × 32 — *under the 44 × 44 WCAG
|
||||
|
||||
**Brand rule (hairlines)**: light theme borders are **SOLID HEX**, not translucent violet at any alpha. The earlier light-theme generation used `rgba(108,87,232,0.20-0.40)` and the violet alpha composited to within a few luminance steps of the white card — borders effectively dissolved, especially on outline buttons (`Go to Index`, `Find msg id`) and on input rings (`Score Threshold` field). The current system uses three concrete warm-grey hex values (`#e6dfd8` / `#d6cdbe` / `#c1b6a3`) — each step is a definite material, not a tint. The dark theme keeps translucent violet at 10-28 % because the indigo-bg-to-card luminance delta is already doing most of the boundary work; light theme has no such luminance assist and must rely on the hairline alone.
|
||||
|
||||
### Decorative Depth
|
||||
#### Decorative Depth
|
||||
|
||||
- **Backdrop-blur**: 12 px on `{colors.surface-glass}` for the sticky top-nav. This is the only blur effect in the system.
|
||||
- **Hairline gradient line**: The top of the nav draws a 1-px `transparent → {colors.accent} → transparent` line at 40 % opacity. The closest the design comes to "decoration."
|
||||
- **Card lift**: Hover lifts L1/L2 cards `-2px` (`{components.card-hover}`) or `-3px` (`{components.kpi-card}`), simultaneously upgrading their shadow ladder one step.
|
||||
- **Card lift**: Hover lifts L1/L2 cards `-2px` (`{components.card-hover}`), simultaneously upgrading their shadow ladder one step.
|
||||
- **Gradient text**: `.gradient-text` and `.gradient-text-accent` utilities apply `{gradients.brand}` / `{gradients.accent}` to text via `background-clip: text`. Use sparingly — reserved for hero brand moments, never for body or table cells.
|
||||
|
||||
## Shapes
|
||||
### Shapes
|
||||
|
||||
### Border Radius Scale
|
||||
#### Border Radius Scale
|
||||
|
||||
| Token | Value | Use |
|
||||
|---|---|---|
|
||||
@ -496,14 +495,16 @@ The top-nav icon-only buttons (tablet) are 32 × 32 — *under the 44 × 44 WCAG
|
||||
|
||||
**No pill (100-px) shape.** Unlike Vercel's marketing pill, EvalScope is an in-product surface; all CTAs use `{rounded.sm}` 8 px. Pills (`{rounded.full}`) are exclusively for *data* — badges, chips, score indicators.
|
||||
|
||||
### "Photography" — Iconography Geometry
|
||||
#### "Photography" — Iconography Geometry
|
||||
|
||||
- **Brand mark**: Hand-drawn SVG triangle with an amber check; rendered inline at 28 × 25 px with `currentColor` so it follows theme.
|
||||
- **Lucide icons**: 14 px in dense lists, 16 px in nav, 18 px in form controls, 28 px in empty-state hero tiles. Stroke width 1.5–2.
|
||||
- **KPI icon tile**: 40 × 40, `{rounded.md}`, filled with one of `{gradients.kpi-0..3}`, white icon centered.
|
||||
- **KPI icon tile**: 40 × 40, `{rounded.md}`, filled with `{colors.accent-dim}`, `{colors.accent}` icon centered.
|
||||
- **Chart**: Plotly canvas, no rounded corners; sits inside a `{rounded.md}` card frame.
|
||||
|
||||
## Components
|
||||
## Components {#components}
|
||||
|
||||
> **Addressable section — `components`.** The component contracts built from the tokens above: buttons, cards, inputs, tabs, navigation, tables, badges, and the signature composite surfaces. Each entry references tokens by name so a re-skin propagates automatically.
|
||||
|
||||
### Buttons
|
||||
|
||||
@ -533,8 +534,9 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
**`{components.card-hover}`** — utility applied to clickable cards.
|
||||
- Adds `-2 px translateY` on hover, upgrades shadow to `{shadows.lg}` (L4), strengthens border to `{colors.border-strong}`. All transitions in `{tokens.transition}`.
|
||||
|
||||
**`{components.kpi-card}`** — the dashboard hero metric tile.
|
||||
- Same chrome as `{components.card}` but layered with `{gradients.surface}` (subtle violet wash, 5-8 % alpha) via `::before`. Hosts a 40 × 40 `{rounded.md}` icon tile filled with `{gradients.kpi-0..3}`. Hover lifts `-3 px` and ramps to L4 shadow. Stagger-animated on first paint (60 ms steps).
|
||||
**`{components.kpi-strip}`** — the counter strip that opens a page.
|
||||
- One joined surface, not a row of free-floating tiles: the counters are the same kind of quantity, so separating them into individually lifting cards would assert a distinction that does not exist. Chrome is `{components.card}` (`{colors.bg-card}` fill, 1-px `{colors.border}`, `{rounded.md}`, `{shadows.sm}`) wrapping hairline-divided cells; the strip clips its corners so the dividers never break the outline. A cell is 20-px padded (`{spacing.xl}`) in the `hero` density and holds an optional 32 × 32 `{rounded.sm}` icon tile filled `{colors.accent-dim}` / inked `{colors.accent}`, a `{typography.title-md}` value and a `{typography.body-xs}` label. Interactive cells are buttons and tint to `{colors.bg-card2}` on hover — the strip itself never lifts or transforms.
|
||||
- Two denser variants share the same contract: `dense` (in-panel metric overview — 2/3/4-up grid of gap-px cells, 18-px value, 10-px label, optional per-cell accent colour) and `inline` (identity/config row — flexible cells with a 140-px floor that wrap, `{typography.body-sm-strong}` value over a `{typography.table-xs}` uppercase label, no icons).
|
||||
|
||||
**`{components.card-glass}`** — the glassmorphic surface used by the top-nav.
|
||||
- `{colors.surface-glass}` background + 12-px backdrop-blur. Always combined with a 1-px hairline border. Reserve for sticky-positioned surfaces — diffuse blur is performance-sensitive.
|
||||
@ -576,7 +578,7 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
|
||||
**`{components.table}`** — sortable data table.
|
||||
- Wrapped in `{components.card}` chrome (`{rounded.md}` border + bg) with `overflow-x-auto`.
|
||||
- **Header cells**: `{typography.table-xs}` — 10 px, semibold, UPPERCASE, `tracking-wider`, `{colors.text-dim}`. They *whisper*. Sortable headers show a triple-state chevron (`ChevronsUpDown` idle, `ChevronUp/Down` active) and lift to `{colors.text}` on hover; active sort column turns `{colors.accent}`.
|
||||
- **Header cells**: `{typography.table-xs}` — 12 px, semibold, UPPERCASE, `tracking-wider`, `{colors.text-muted}`. Headers are essential interpretation text and therefore meet the 12 px/AA floor. Sortable headers show a triple-state chevron (`ChevronsUpDown` idle, `ChevronUp/Down` active) and lift to `{colors.text}` on hover; active sort column turns `{colors.accent}`.
|
||||
- **Row dividers**: 1-px `{colors.border}`. Clickable rows hover-fill `{colors.bg-card2}`.
|
||||
- **Empty state**: Centered, dimmed "No data" cell — no illustration.
|
||||
|
||||
@ -594,7 +596,7 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
|
||||
### Signature Components
|
||||
|
||||
**`{components.kpi-card}`** — see *Cards & Containers* above.
|
||||
**`{components.kpi-strip}`** — see *Cards & Containers* above.
|
||||
|
||||
**`{components.eval-run-card}`** — a full-width borderless button-styled card row.
|
||||
- Two rows of content: bold model name + colored score pill on the right; second row has a mono timestamp + a wrap of `{components.score-chip}` entries (one per benchmark). Hover only changes border tint (no lift).
|
||||
@ -615,12 +617,161 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
**`{components.score-badge}`** — the bold percentage pill at the top of an eval row.
|
||||
- `{rounded.full}`, 10/2 padding, `{typography.body-sm}` bold + `tabular-nums`, HSL-computed fg/bg. Distinct from `{components.score-chip}` by size and weight.
|
||||
|
||||
### Component Contracts (Responsive & State) {#component-contracts}
|
||||
|
||||
> **Addressable sub-section — `component-contracts`.** Every responsive component below carries two contracts, and both are **normative and executable** — not descriptive prose:
|
||||
>
|
||||
> - a **Responsive contract** — the layout, wrapping, and visibility behavior at each of the five breakpoints (**Mobile < 640 px · Small 640–767 px · Tablet 768–1023 px · Desktop 1024–1279 px · Wide ≥ 1280 px**, per [Responsive Strategy](#tokens)'s breakpoint table), and
|
||||
> - a **State contract** — the presentation requirement for every visible state (**default · hover · focus · active · disabled · error**). A state a component cannot enter is listed as *n/a* with the reason, so the enumeration stays complete.
|
||||
|
||||
#### Normative contract rules (executable, not aspirational)
|
||||
|
||||
These thresholds are **enforceable rules, not logged known-failures**. The E2E/axe suite (task 19.2) asserts them at the 390 px viewport and in both themes; a violation fails CI. Each component contract below inherits them.
|
||||
|
||||
- **R-TOUCH — Touch-target floor 44 × 44 CSS px.** On coarse pointers, every primary `Pointer_Target` in navigation, the mobile menu, compare-selection, and disclosure controls MUST expose a hit area **≥ 44 × 44 CSS px**, independent of the visual icon/box size (padding or an `::before` overlay carries the extra area).
|
||||
- **R-CONTRAST — AA contrast floor.** Essential text MUST meet **AA_Contrast in both themes**: **≥ 4.5 : 1** for normal text and **≥ 3 : 1** for large text (≥ 24 px, or ≥ 18.66 px bold). `dim`/`muted` tokens applied to essential content are promoted to clear this floor; non-text focus indicators MUST reach **≥ 3 : 1** against the adjacent background.
|
||||
- **R-WRAP — No lossy truncation of essential metadata.** Responsive text containers use `break-words` + `min-w-0` and MUST NOT apply `truncate`/ellipsis/overflow-hidden to essential metadata; at 390 px every field label and value stays visible and wraps at word (then character) boundaries with no page-level horizontal scroll.
|
||||
- **R-FOCUS — Visible focus in both themes.** Every interactive component's **focus** state renders a visible focus indicator (`{colors.accent}` ring + `{colors.accent-dim}` fill) meeting R-CONTRAST's ≥ 3 : 1 non-text floor on both themes. Individual state contracts reference this rule rather than restating it.
|
||||
|
||||
#### `{components.top-nav}` / `{components.nav-link}` / `{components.icon-button}` — navigation
|
||||
|
||||
- **Responsive contract:**
|
||||
- **Mobile < 640:** logo + hamburger only; nav items collapse into a stacked drop-down (animated `max-height`, 300 ms); GitHub link + locale toggle live inside the drawer. Drawer toggle and every drawer item satisfy R-TOUCH.
|
||||
- **Small 640–767:** hamburger drawer retained; GitHub icon and locale toggle surface directly in the bar.
|
||||
- **Tablet 768–1023:** icon-only pill buttons (32 × 32 visual) with `title` tooltips; text labels hidden; hit area ≥ 44 × 44 per R-TOUCH.
|
||||
- **Desktop 1024–1279:** full pill links with icon + label; active = solid `{colors.accent}` + glow.
|
||||
- **Wide ≥ 1280:** identical to Desktop; container caps at `max-w-[1600px]`, bar content centers.
|
||||
- **State contract:**
|
||||
- **default:** `{colors.text-muted}` label on transparent fill.
|
||||
- **hover:** label lifts to `{colors.text}`, fill → `{colors.bg-card2}`.
|
||||
- **focus:** per R-FOCUS.
|
||||
- **active (current route):** `{colors.accent}` fill, `{colors.on-filled}` label, `{shadows.glow}` halo.
|
||||
- **disabled:** *n/a* — nav destinations are always actionable.
|
||||
- **error:** *n/a* — navigation carries no validation state.
|
||||
|
||||
#### `{components.button}` — buttons (primary / ghost / outline)
|
||||
|
||||
- **Responsive contract:** intrinsic width, wraps within its container per R-WRAP; size is chosen by usage, not breakpoint (`sm` ~28 px, `md` ~36 px, `lg` ~44 px). A primary `Pointer_Target` button on coarse pointers is promoted to the 44 px hit area (R-TOUCH) regardless of visual size. Toolbar button rows wrap to a new line below `md` rather than horizontally scrolling.
|
||||
- **State contract:**
|
||||
- **default:** variant fill/border per *Buttons* above; label meets R-CONTRAST (`{colors.on-filled}` on primary, `{colors.text}` on ghost/outline).
|
||||
- **hover:** primary adds `{shadows.glow}` + `bg → {colors.accent-dark}`; ghost → `{colors.bg-card}`; outline swaps border + text to `{colors.accent}`.
|
||||
- **focus:** per R-FOCUS.
|
||||
- **active (press):** scales to 0.98; ghost → `{colors.bg-card2}`.
|
||||
- **disabled:** `opacity: 0.5` + `cursor: not-allowed`; no hover/glow; still announced to AT.
|
||||
- **error:** *n/a* — buttons carry no intrinsic error state (submit errors surface on fields).
|
||||
|
||||
#### `{components.card}` / `{components.card-hover}` / `{components.row-card}` — cards & rows
|
||||
|
||||
- **Responsive contract:** full-width within its band at every breakpoint; interior text follows R-WRAP (no truncation). Card interior padding is fixed 20 px at all breakpoints (page breathing comes from the 1600 px container, not padding expansion).
|
||||
- **State contract:**
|
||||
- **default:** `{colors.bg-card}`, 1-px `{colors.border}`, `{shadows.sm}` (L2).
|
||||
- **hover (clickable only):** `{components.card-hover}` lifts −2 px, shadow → `{shadows.lg}` (L4), border → `{colors.border-strong}`; `{components.row-card}` only tints border → `{colors.border-md}` (no transform, kept calm for dense lists).
|
||||
- **focus (clickable only):** per R-FOCUS.
|
||||
- **active (clickable only):** border holds at `{colors.border-strong}`; no additional transform.
|
||||
- **disabled:** *n/a* — non-interactive cards have no disabled state; a disabled clickable card falls back to the button disabled contract.
|
||||
- **error:** *n/a* — error is expressed by the content inside (e.g. `{components.empty-state}` load-error), not the card shell.
|
||||
|
||||
#### KPI strip / `{components.kpi-strip}` — page-opening counters
|
||||
|
||||
- **Responsive contract:**
|
||||
- **Mobile < 640 & Small 640–767:** 2-up grid (`grid-cols-2`).
|
||||
- **Tablet 768–1023:** 2-up grid retained; cells full-width of their column.
|
||||
- **Desktop 1024–1279 & Wide ≥ 1280:** 4-up grid (`lg:grid-cols-4`). Each cell keeps 20-px padding at every breakpoint; the value uses `tabular-nums` and truncates with the full text carried in `title` rather than reflowing the strip.
|
||||
- **State contract:**
|
||||
- **default:** `{components.card}` chrome around hairline-divided cells; optional 32 × 32 accent icon tile per cell.
|
||||
- **hover:** interactive cells tint to `{colors.bg-card2}`; the strip does not lift or transform.
|
||||
- **focus:** per R-FOCUS when the cell is interactive; *n/a* for display-only cells.
|
||||
- **active:** *n/a* unless linked, then follows the clickable-card active contract.
|
||||
- **disabled:** *n/a*.
|
||||
- **error:** *n/a* — a metric with no value renders the missing-value placeholder inside the cell (see [Metric Display Contract](#metrics)), not a cell error state.
|
||||
|
||||
#### `{components.tabs}` — pill-container tabs
|
||||
|
||||
- **Responsive contract:** segmented pill row at `md+`; below `md` the row wraps (or scrolls its own container, never the page) per R-WRAP so every tab label stays legible. Tab labels never truncate.
|
||||
- **State contract:**
|
||||
- **default (inactive):** `{colors.bg-card}` fill, `{colors.text-muted}` label; `tabindex=-1` under roving-tabindex.
|
||||
- **hover:** fill → `{colors.bg-card2}`.
|
||||
- **focus:** the single active tab holds `tabindex=0`; arrow keys move focus with wrap-around; per R-FOCUS.
|
||||
- **active (selected):** `{colors.accent}` fill + `{colors.on-filled}` text + soft glow `0 0 12 px rgba(129,109,248,0.2)`; exactly one tab has `aria-selected=true` and one visible `tabpanel`.
|
||||
- **disabled:** disabled tab renders at `opacity: 0.5`, `aria-disabled=true`, skipped by roving navigation.
|
||||
- **error (orphan item):** a tab with no matching `tabpanel` reference is **not rendered** and an error is surfaced.
|
||||
|
||||
#### `{components.table}` — sortable data table
|
||||
|
||||
- **Responsive contract:**
|
||||
- **Mobile < 640 & Small 640–767:** the Evaluation-History surface presents the **card layout** (field-per-line, R-WRAP, no truncation); a raw table, where shown, is wrapped in `overflow-x-auto` so all columns are preserved (horizontal scroll inside the card shell, never at the page level).
|
||||
- **Tablet 768–1023:** table with `overflow-x-auto`; all columns retained rather than dropped.
|
||||
- **Desktop 1024–1279 & Wide ≥ 1280:** full table with the fixed, ordered columns `model · dataset · time · samples · score · status`. Header text uses `{typography.table-xs}` at 12 px and is never shrunk below the floor.
|
||||
- **State contract:**
|
||||
- **default:** header `{typography.table-xs}` UPPERCASE `{colors.text-muted}`; 1-px `{colors.border}` row dividers.
|
||||
- **hover:** sortable header lifts to `{colors.text}`; clickable row fills `{colors.bg-card2}`.
|
||||
- **focus:** sortable header / row focusable, per R-FOCUS.
|
||||
- **active (sorted column):** header turns `{colors.accent}` with a `ChevronUp/Down` direction indicator.
|
||||
- **disabled:** *n/a* — columns are always sortable/among the fixed set.
|
||||
- **error / empty:** centered dimmed "No data" cell (or the `{components.empty-state}` surface when the whole view is empty).
|
||||
|
||||
#### `{components.input}` / `{components.select}` / `Field_Primitive` — inputs & forms
|
||||
|
||||
- **Responsive contract:** label/value pairs are two-column at `md+` (`grid-cols-1 md:grid-cols-2`) and single-column below `md`; label and helper text follow R-WRAP. Inputs are full-width of their column at every breakpoint.
|
||||
- **State contract:**
|
||||
- **default:** `{colors.bg-deep}` well, 1-px `{colors.border}`, `{colors.text}` value, `{colors.text-dim}` placeholder; a non-empty programmatically-associated label (`{colors.text-muted}`, UPPERCASE `{typography.label-xs}`).
|
||||
- **hover:** border → `{colors.border-md}`.
|
||||
- **focus:** border → `{colors.accent}` + 1-px `{colors.accent-dim}` ring (soft halo); per R-FOCUS.
|
||||
- **active:** same as focus while editing.
|
||||
- **disabled:** `opacity: 0.5`, `cursor: not-allowed`, `aria-disabled`; still exposes its accessible name.
|
||||
- **error:** border + ring swap to the danger family, `aria-invalid=true`, `aria-describedby` points at a 12 px `{colors.danger}` helper line; the message is announced via a polite live region within 1 s and receives focus first among invalid fields on submit.
|
||||
|
||||
#### `{components.empty-state}` — actionable empty states
|
||||
|
||||
- **Responsive contract:** vertically-centered stack, full-width of its band at every breakpoint; the 64 × 64 icon tile and the two message lines wrap per R-WRAP and never truncate. Recovery-action buttons stack below `md` and sit inline at `md+`.
|
||||
- **State contract:**
|
||||
- **default:** icon tile (`{colors.accent}` welcome / `{colors.text-dim}` empty) + title + hint; renders within 300 ms of a completed zero-record load, with reason-specific text for `no-data` / `load-error` / `no-match`.
|
||||
- **hover / focus / active:** carried by the 1–3 embedded recovery-action buttons per the `{components.button}` contract (each a `Pointer_Target` ≥ 44 × 44 on touch, R-TOUCH); every action has a non-empty `navigateTo`.
|
||||
- **disabled:** *n/a* — recovery actions are always actionable.
|
||||
- **error:** the `load-error` reason **is** this component's error presentation (distinct copy + retry action); it does not render a blank region.
|
||||
|
||||
#### `{components.eval-run-card}` — eval timeline run row
|
||||
|
||||
- **Responsive contract:** single full-width column at every breakpoint (the timeline is already a vertical list). At 390 px all metadata fields (model, dataset, time, samples, score, status, per-benchmark score chips) stay visible and wrap per R-WRAP — no ellipsis, no horizontal scroll. The score-chip row wraps onto multiple lines rather than clipping.
|
||||
- **State contract:**
|
||||
- **default:** `{colors.bg-card}`, 1-px `{colors.border}`; bold model name + score badge; mono timestamp + wrapped `{components.score-chip}` set.
|
||||
- **hover:** border tint → `{colors.border-md}` only (no lift, calm for dense lists).
|
||||
- **focus:** per R-FOCUS (the row is a button).
|
||||
- **active (press):** border holds at `{colors.border-md}`; navigates to detail.
|
||||
- **disabled:** *n/a*.
|
||||
- **error:** *n/a* — a run with missing values shows placeholders/`N/A` per the metric contract, not a card error state.
|
||||
|
||||
#### `{components.score-chip}` / `{components.badge}` / `{components.filter-chip}` — chips & pills
|
||||
|
||||
- **Responsive contract:** chips are meant to **wrap** — a chip row flows onto multiple lines with an 8-px gap at every breakpoint and never truncates or horizontally scrolls (R-WRAP). Chip content (`"benchmark-name 87.3"`) is `tabular-nums` mono and stays whole.
|
||||
- **State contract:**
|
||||
- **default:** `{components.score-chip}` outline (transparent bg + 1-px `scoreColor` border + `scoreColor` text); `{components.badge}` uses an 8–10 % alpha bg + saturated fg. Both meet R-CONTRAST for the essential value.
|
||||
- **hover:** `{components.filter-chip}` reveals its dismiss control; score/badge pills are static.
|
||||
- **focus:** `{components.filter-chip}` dismiss control and any interactive chip follow R-FOCUS and R-TOUCH (≥ 44 × 44 hit area on touch).
|
||||
- **active:** dismiss removes the chip; static chips have no active state.
|
||||
- **disabled:** *n/a*.
|
||||
- **error:** *n/a*.
|
||||
|
||||
#### `ex-compare-column` / `{components.card}` (compare) — compare-view model column
|
||||
|
||||
- **Responsive contract:**
|
||||
- **Mobile < 640 & Small 640–767:** columns stack vertically (one model per full-width block); display label and metric rows wrap per R-WRAP.
|
||||
- **Tablet 768–1023:** 2 columns side-by-side.
|
||||
- **Desktop 1024–1279 & Wide ≥ 1280:** 2–3 columns side-by-side; beyond 3 models the view collapses into a numbered legend rather than inventing a 4th slot color.
|
||||
- **State contract:**
|
||||
- **default:** header carries the model+dataset display label and one of the `{compare.0..2}` slot accents (`dot` / `border` / `bg-header`).
|
||||
- **hover:** column header/row tint strengthens via the slot's `bg-hl` where interactive.
|
||||
- **focus:** compare-selection controls follow R-FOCUS and R-TOUCH.
|
||||
- **active (selected for compare):** slot accent applied; selection persists across sort/filter and is reflected in the sticky selection tray count.
|
||||
- **disabled (incompatible):** score-comparison selection is unbounded; prediction comparison accepts up to `MAX_COMPARE_SLOTS = 3` runs. An incompatible run shows its incompatibility reason and retains existing selection.
|
||||
- **error:** incompatibility reason text is the error presentation; it does not drop the selection.
|
||||
|
||||
### Examples (illustrative)
|
||||
|
||||
> These `ex-*` surfaces mirror the brand-native primitives for downstream consumers (kits, mockups, Stitch generation). Each references existing components so a re-skin re-skins all surfaces consistently.
|
||||
|
||||
**`ex-metric-tile`** — Dashboard KPI tile. Re-uses `{components.kpi-card}` with gradient icon tile + tabular value + uppercase label.
|
||||
- Properties: `backgroundColor`, `iconGradient`, `rounded`, `padding`, `valueTypography`, `labelTypography`.
|
||||
**`ex-metric-tile`** — Dashboard KPI cell. Re-uses one cell of `{components.kpi-strip}` with accent icon tile + tabular value + label.
|
||||
- Properties: `backgroundColor`, `iconTint`, `rounded`, `padding`, `valueTypography`, `labelTypography`.
|
||||
|
||||
**`ex-eval-run-row`** — A row in the eval timeline. Re-uses `{components.eval-run-card}` chrome.
|
||||
- Properties: `backgroundColor`, `borderColor`, `rounded`, `padding`, `scoreColor`, `chipColor`.
|
||||
@ -649,9 +800,55 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
**`ex-compare-column`** — A model column in the compare view, using one of the three `{compare.0..2}` slot colors.
|
||||
- Properties: `dotColor`, `borderColor`, `headerBackground`.
|
||||
|
||||
## Do's and Don'ts
|
||||
## Metric Display Contract {#metrics}
|
||||
|
||||
### Do
|
||||
> **Addressable section — `metrics`.** How raw metric values become on-screen text. Display form is decided by a metric's `MetricDisplaySpec` metadata — never by inspecting the numeric magnitude — so the same value renders consistently across list, detail, compare, and export surfaces. The contract below is implemented by `src/domain/metric/MetricDisplaySpec.ts` and `src/domain/metric/metricFormat.ts`.
|
||||
|
||||
### Display Rules
|
||||
|
||||
- **Spec-driven, not value-driven.** `resolveSpec(key, registry)` returns the metric's spec (or `DEFAULT_METRIC_SPEC` with `isFallback = true`). The spec's `kind` — not the value — selects the presentation. A raw value greater than `1` never triggers percentage formatting.
|
||||
- **Bounded ratio → percentage.** A `bounded-ratio` metric (domain `0–1`) renders as a percentage to `percentPrecision` decimals using round-half-up, and preserves a 4-decimal raw value alongside it. `bounded` metrics (domain `0–100`) display on their native scale.
|
||||
- **Unbounded / native → raw with unit.** Unbounded or native-unit metrics keep their unit and render at `rawPrecision`; they are never converted to a percentage.
|
||||
- **Missing vs. legitimate zero.** A missing value renders `MISSING_PLACEHOLDER` and sets `isMissing = true`; a real `0` renders as a formatted zero. The two are always distinguishable.
|
||||
- **Undefined spec fallback.** When no spec is registered for a key, the value renders as a 4-decimal raw number with `isSpecUndefined = true`, and the implementation-level metric name is hidden behind a localized `labelKey`.
|
||||
- **Rounding.** All decimal rounding uses `roundHalfUp(value, precision)` so `.5` cases round up deterministically across every surface.
|
||||
|
||||
### Threshold Semantics
|
||||
|
||||
- **Prediction threshold is a view-only filter.** A per-view threshold only annotates or filters rows (`Below filter` / `Above filter`); it never participates in pass/fail and never affects other views.
|
||||
- **Native outcome is independent.** A benchmark's native `outcome` (pass/fail) is derived and displayed independently of any prediction threshold.
|
||||
|
||||
## Decision Records {#decisions}
|
||||
|
||||
> **Addressable section — `decisions`.** The load-bearing decisions behind this system, captured so future changes understand what is intentional versus incidental. Each decision is normative; the *Do's and Don'ts* that follow are the enforceable expression of these decisions.
|
||||
|
||||
### D1 — Dual-theme parity, not translation
|
||||
|
||||
Dark and light are two equally weighted voices of one brand, not one canonical mode re-tinted. They share vocabulary (type, spacing, radii, components) but use *opposite materials* to produce the same hierarchy: dark uses translucent-violet hairlines on near-black; light uses solid warm-grey hairlines on cream. Every new color token must define both a dark and a light value in the same commit.
|
||||
|
||||
### D2 — Solid-hex hairlines on the light theme
|
||||
|
||||
Light-theme borders are solid warm-grey hex (`#e6dfd8` / `#d6cdbe` / `#c1b6a3`), never translucent violet. Violet at any plausible alpha composites to near-invisible against a white card on cream. This is the single most-broken light-theme rule; see [Design Tokens → Hairlines](#tokens).
|
||||
|
||||
### D3 — Dynamic HSL score gradient is a brand asset
|
||||
|
||||
Scores map to `hsl(score × 120, 70%, 45%)` (red → yellow → green), computed inline and never stored as a static palette. Per-theme legibility is tuned only through CSS vars (`--score-fg-s`, `--score-fg-l`, `--score-bg-a-mul`); the formula itself is not re-skinned into buckets and gains no fourth hue.
|
||||
|
||||
### D4 — System font stack, no web font
|
||||
|
||||
The brand loads no `@font-face`; cross-platform `system-ui` / `ui-monospace` stacks resolve to each OS's native face. This is deliberate — it reads as "native developer tool," and the trade-off is per-OS rendering variance.
|
||||
|
||||
### D5 — Token single source of truth and drift governance
|
||||
|
||||
Token values live once in `evalscope/web/src/index.css`. Run `npm run design:tokens` after changing shared runtime tokens; `scripts/drift/tokenDrift.ts` verifies that this document's frontmatter was generated from the current CSS values.
|
||||
|
||||
### D6 — Additive, reversible migration
|
||||
|
||||
Refactors preserve raw values, keep chart data-table fallbacks, and retain old components until visual-regression parity is proven. Web API response contracts are not duplicated during migration: backend Pydantic models are the single source of truth, and the frontend consumes generated TypeScript types.
|
||||
|
||||
### Do's and Don'ts
|
||||
|
||||
#### Do
|
||||
|
||||
- Reserve `{colors.accent}` (`#816DF8`) for primary CTAs, active states, focus rings, and the wordmark accent. Brand violet IS the conversion target — keep it under ~10 % of any screen.
|
||||
- Use `{rounded.sm}` 8 px for buttons / inputs / tabs, `{rounded.md}` 12 px for cards, `{rounded.full}` only for badges / chips / score pills. Each shape signals its category.
|
||||
@ -664,19 +861,19 @@ Disabled = `opacity: 0.5` + `cursor: not-allowed`. Transitions use `{tokens.tran
|
||||
- Animate page transitions with `fadeInUp` (12 px translate + opacity, 400 ms ease-out) and stagger children at 60 ms. The motion is subtle — don't lengthen it.
|
||||
- Persist the `data-theme` to `localStorage` and apply it pre-paint in `index.html` to avoid FOUC. Tokens are theme-agnostic by name; values flip.
|
||||
|
||||
### Don't
|
||||
#### Don't
|
||||
|
||||
- Don't introduce a 6th brand hue or a 4th compare-slot color. The palette is closed at violet + emerald + amber + red + slate (plus the dynamic HSL score). New accents flatten the voice.
|
||||
- Don't render headlines in all-caps. UPPERCASE is the eyebrow voice (12 px / 10 px micro-labels) — never the title voice. Card titles and model names stay sentence-case.
|
||||
- Don't render headlines in all-caps. UPPERCASE is the 12 px eyebrow/table-label voice — never the title voice. Card titles and model names stay sentence-case.
|
||||
- Don't promote the sans to `font-extrabold` / `font-black`. The display weight ceiling is **700**.
|
||||
- Don't use `{colors.text-dim}` for essential UI text on either theme — its ~3.6 : 1 contrast against `{colors.bg-card}` clears AA Large (3 : 1) but is below WCAG AA Normal (4.5 : 1). Reserve for ≥ 14 px non-essential metadata (timestamps, "empty" labels, scrollbar thumb). Every code-side use must carry the inline note `// text-dim allowed: non-essential ≥14px metadata (DESIGN.md §Text)` so reviewers can audit it.
|
||||
- Don't use `{colors.text-dim}` for essential UI text on either theme — its ~3.6 : 1 contrast against `{colors.bg-card}` clears AA Large (3 : 1) but is below WCAG AA Normal (4.5 : 1). Reserve textual use for ≥ 14 px non-essential metadata (timestamps and empty labels). Placeholder text, decorative icons, separators, disabled controls, and scrollbar thumbs are exempt because they are not essential readable content. Add the inline note `// text-dim allowed: non-essential ≥14px metadata (DESIGN.md §Text)` when a textual use is not self-evidently a placeholder or empty-state annotation; do not scatter the note onto every decorative icon.
|
||||
- Don't reuse a dark-theme shadow value verbatim on light. The light palette stacks two **warm-ink-tinted** drops (`rgba(20,20,19,0.04)` + `rgba(20,20,19,0.06)`) — a single `rgba(0,0,0,0.07)` drop on cream reads as a page smudge, not as a lifted card. Do not slate-tint the light shadows either (`rgba(15,23,42,*)`) — slate on cream reads as a cool-grey smear that fights the warm canvas. See *Elevation & Depth*.
|
||||
- **Don't use translucent violet for light-theme hairlines.** This is the most-broken light-theme rule. The light `{colors.border-light}` is a SOLID warm-grey hex (`#e6dfd8`) — translucent violet at *any* plausible alpha (0.10 / 0.20 / 0.30 / 0.40) composites to near-invisible against a white card on cream and leaves every card boundary undefined. Outline buttons and input rings will vanish. The dark theme uses translucent violet because the near-black bg-to-card luminance delta carries the boundary; the light theme has no such delta and must use a concrete material.
|
||||
- Don't introduce a cool-grey or pure-white surface to the light theme. The light palette is warm-cream by design (`#faf9f5` canvas, `#f0ebe1` deep, `#f5f0e7` elevated, `#ffffff` cards). A cool-grey `#f5f6fa` or `#eef0f7` band breaks the warm-coherent rhythm and reverts the system to "any other AI dashboard."
|
||||
- Don't drop a single heavy 8-px-blur drop-shadow on a card. The dark theme requires *deeper* multi-stop shadows (`rgba(0,0,0,0.55)` at 20-40 px) — soft drops disappear on near-black.
|
||||
- Don't apply `{gradients.brand}` to body text or table cells. Gradient-text is for hero / wordmark moments only.
|
||||
- Don't bypass `{components.button}` to write custom `bg-[var(--accent)]` buttons inline. The button variants encode the glow, the scale-press, and the disabled state — re-deriving them by hand drifts the brand.
|
||||
- Don't use inline `style={{ background: 'var(--xxx)' }}` when a Tailwind class or the `formStyles` helper would do. Inline styles bypass the token abstraction and break theme switching for the hover state.
|
||||
- Standalone actions and conversion CTAs use `{components.button}` variants; do not re-derive their glow, press, focus, or disabled behavior with a one-off `bg-[var(--accent)]`. Component-internal controls with a distinct semantic contract (tabs, segmented selectors, list rows, score chips) may compose token classes directly, but their states belong in that component's contract and tests.
|
||||
- Prefer token-backed Tailwind classes or `formStyles` for static surfaces. Inline styles are reserved for values that are genuinely computed at runtime (for example score colors, chart series colors, progress widths, and measured geometry); they must still resolve through documented tokens/formulas where applicable.
|
||||
- Don't pair `{rounded.full}` pill shapes with `{rounded.md}` cards as siblings inside the same control group — pills are for *data*, sm/md radii are for *interactive containers*. Mixing them on the same row breaks the shape grammar.
|
||||
- Don't ignore `prefers-color-scheme` on first visit. If the user has never toggled, fall back to the OS preference before defaulting to dark.
|
||||
- Don't widen `{spacing.xl}` (20 px) section gaps past `{spacing.2xl}` (24 px). The product is information-dense by design; extra whitespace makes the dashboard feel half-empty rather than airy.
|
||||
|
||||
@ -4,16 +4,23 @@ include README.md
|
||||
recursive-include evalscope *
|
||||
|
||||
# Exclude cache/compiled artifacts
|
||||
global-exclude *.py[cod] __pycache__ *.so *.dylib
|
||||
global-exclude *.py[cod] __pycache__ *.so *.dylib .DS_Store
|
||||
|
||||
# Exclude large data files
|
||||
global-exclude *.h5 *.hdf5 *.parquet *.bin *.safetensors *.gguf *.pth *.pt
|
||||
|
||||
# Exclude frontend dev files (only dist/ is needed at runtime)
|
||||
prune evalscope/web/coverage
|
||||
prune evalscope/web/node_modules
|
||||
prune evalscope/web/public
|
||||
prune evalscope/web/scripts
|
||||
prune evalscope/web/src
|
||||
exclude evalscope/web/.gitignore
|
||||
exclude evalscope/web/README.md
|
||||
exclude evalscope/web/index.html
|
||||
exclude evalscope/web/package.json
|
||||
exclude evalscope/web/package-lock.json
|
||||
exclude evalscope/web/tsconfig*.json
|
||||
exclude evalscope/web/vite.config.ts
|
||||
exclude evalscope/web/vitest.config.ts
|
||||
exclude evalscope/web/eslint.config.js
|
||||
|
||||
@ -1,6 +1,9 @@
|
||||
# default rule
|
||||
default: install
|
||||
|
||||
PYTHON ?= python
|
||||
DIST_DIR ?= $(CURDIR)/dist
|
||||
|
||||
# ============================================================================
|
||||
# Documentation Generation
|
||||
# ============================================================================
|
||||
@ -108,10 +111,40 @@ web-install:
|
||||
web-build:
|
||||
cd evalscope/web && npm install && npm run build
|
||||
|
||||
.PHONY: web-contracts-check
|
||||
web-contracts-check:
|
||||
cd evalscope/web && npm run contracts:check
|
||||
|
||||
.PHONY: web-release-build
|
||||
web-release-build:
|
||||
cd evalscope/web && npm ci
|
||||
$(MAKE) web-contracts-check
|
||||
cd evalscope/web && npm run build
|
||||
|
||||
.PHONY: web-dev
|
||||
web-dev:
|
||||
cd evalscope/web && npm install && npm run dev
|
||||
|
||||
# ============================================================================
|
||||
# Release Package
|
||||
# ============================================================================
|
||||
|
||||
.PHONY: package
|
||||
package:
|
||||
$(MAKE) web-release-build
|
||||
$(MAKE) package-build
|
||||
$(MAKE) package-check
|
||||
|
||||
# Run outside the repository so a local build/ directory cannot shadow the Python build package.
|
||||
.PHONY: package-build
|
||||
package-build:
|
||||
cd "$(CURDIR)/.." && $(PYTHON) -m build "$(CURDIR)" --outdir "$(DIST_DIR)"
|
||||
|
||||
.PHONY: package-check
|
||||
package-check:
|
||||
$(PYTHON) scripts/release/verify_package.py --dist-dir "$(DIST_DIR)"
|
||||
$(PYTHON) -m twine check "$(DIST_DIR)"/*
|
||||
|
||||
# ============================================================================
|
||||
# Development
|
||||
# ============================================================================
|
||||
@ -123,7 +156,6 @@ lint:
|
||||
.PHONY: dev
|
||||
dev:
|
||||
pip install -e '.[dev,perf,docs]'
|
||||
pip install pre-commit
|
||||
|
||||
.PHONY: install
|
||||
install:
|
||||
|
||||
@ -1,176 +1,394 @@
|
||||
# EvalScope 评测仓库
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="docs/en/_static/images/evalscope_logo.png"/>
|
||||
<br>
|
||||
<p>
|
||||
|
||||
## 0. Benchmarks
|
||||
<p align="center">
|
||||
<a href="README_zh.md">中文</a>   |   English  
|
||||
</p>
|
||||
|
||||
### 常用 benchmark 分类
|
||||
<p align="center">
|
||||
<img src="https://img.shields.io/badge/python-%E2%89%A53.10-5be.svg">
|
||||
<a href="https://badge.fury.io/py/evalscope"><img src="https://badge.fury.io/py/evalscope.svg" alt="PyPI version" height="18"></a>
|
||||
<a href="https://pypi.org/project/evalscope"><img alt="PyPI - Downloads" src="https://static.pepy.tech/badge/evalscope"></a>
|
||||
<a href="https://github.com/modelscope/evalscope/pulls"><img src="https://img.shields.io/badge/PR-welcome-55EB99.svg"></a>
|
||||
<a href="https://github.com/modelscope/evalscope"><img alt="GitHub stars" src="https://img.shields.io/github/stars/modelscope/evalscope?style=flat&logo=github"></a>
|
||||
<a href='https://evalscope.readthedocs.io/en/latest/?badge=latest'><img src='https://readthedocs.org/projects/evalscope/badge/?version=latest' alt='Documentation Status' /></a>
|
||||
<p>
|
||||
|
||||
```python
|
||||
benchmark_categories = {
|
||||
"代码与工程": [
|
||||
"terminal_bench_v2",
|
||||
"live_code_bench",
|
||||
"swe_bench_multilingual_agentic",
|
||||
"swe_bench_pro",
|
||||
"swe_bench_verified",
|
||||
"bigcodebench",
|
||||
"humaneval",
|
||||
],
|
||||
"推理与数学": [
|
||||
"gpqa_diamond",
|
||||
"hle",
|
||||
"aime24",
|
||||
"aime25",
|
||||
"aime26",
|
||||
"hmmt26",
|
||||
"imo_answerbench",
|
||||
"super_gpqa",
|
||||
"gsm8k",
|
||||
"competition_math",
|
||||
],
|
||||
"智能体与工具": [
|
||||
"browsecomp",
|
||||
"mcp_atlas",
|
||||
"tau2_bench",
|
||||
],
|
||||
"知识与语言理解": [
|
||||
"mmlu_pro",
|
||||
"simple_qa",
|
||||
"arc",
|
||||
"bbh",
|
||||
"cmmlu",
|
||||
"drop",
|
||||
"hellaswag",
|
||||
"mmlu",
|
||||
"trivia_qa",
|
||||
"winogrande",
|
||||
],
|
||||
"长上下文": [
|
||||
"longbench_v2",
|
||||
"openai_mrcr",
|
||||
],
|
||||
}
|
||||
```
|
||||
<p align="center">
|
||||
<a href="https://evalscope.readthedocs.io/zh-cn/latest/"> 📖 中文文档</a>   |   <a href="https://evalscope.readthedocs.io/en/latest/"> 📖 English Documentation</a>
|
||||
<p>
|
||||
|
||||
### 分组运行
|
||||
|
||||
```python
|
||||
group_1 = [
|
||||
'terminal_bench_v2',
|
||||
'gpqa_diamond',
|
||||
'hle',
|
||||
'aime24',
|
||||
'aime25',
|
||||
'mmlu_pro',
|
||||
'simple_qa',
|
||||
'arc',
|
||||
'bbh',
|
||||
'browsecomp',
|
||||
]
|
||||
> ⭐ If you like this project, please click the "Star" button in the upper right corner to support us. Your support is our motivation to move forward!
|
||||
|
||||
group_2 = [
|
||||
'live_code_bench',
|
||||
'swe_bench_pro',
|
||||
'aime26',
|
||||
'hmmt26',
|
||||
'imo_answerbench',
|
||||
'super_gpqa',
|
||||
'drop',
|
||||
'hellaswag',
|
||||
'mmlu',
|
||||
'openai_mrcr',
|
||||
'mcp_atlas',
|
||||
]
|
||||
## 📝 Introduction
|
||||
|
||||
group_3 = [
|
||||
'swe_bench_multilingual_agentic',
|
||||
'swe_bench_verified',
|
||||
'bigcodebench',
|
||||
'humaneval',
|
||||
'gsm8k',
|
||||
'competition_math',
|
||||
'cmmlu',
|
||||
'trivia_qa',
|
||||
'winogrande',
|
||||
'longbench_v2',
|
||||
'tau2_bench',
|
||||
]
|
||||
```
|
||||
|
||||
## 1. 安装
|
||||
EvalScope is a one-stop LLM evaluation framework built by the [ModelScope Community](https://modelscope.cn/). Just one command to start — it supports model capability evaluation, inference performance stress testing, and result visualization.
|
||||
|
||||
```bash
|
||||
conda create -n evalscope python==3.12 -y
|
||||
git clone https://github.com/modelscope/evalscope
|
||||
pip install -e .
|
||||
pip install 'evalscope[terminal_bench,swe_bench,openai_mrcr]' \
|
||||
'git+https://github.com/sierra-research/tau2-bench@v0.2.0'
|
||||
pip install 'evalscope[sandbox]'
|
||||
pip install 'swebench==4.1.0'
|
||||
pip install evalscope
|
||||
evalscope eval --model your-model-name --api-url $OPENAI_API_BASE_URL --api-key $OPENAI_API_KEY --eval-type openai_api --datasets gsm8k --limit 5
|
||||
```
|
||||
|
||||
## 2. 运行命令
|
||||
## ✨ Key Features
|
||||
|
||||
- **📚 Comprehensive Evaluation Benchmarks**: Built-in multiple industry-recognized evaluation benchmarks including MMLU, C-Eval, GSM8K, and more.
|
||||
- **🧩 Multi-modal and Multi-domain Support**: Supports evaluation of various model types including Large Language Models (LLM), Vision Language Models (VLM), Embedding, Reranker, AIGC, and more.
|
||||
- **🚀 Multi-backend Integration**: Seamlessly integrates multiple evaluation backends including OpenCompass, VLMEvalKit, RAGEval to meet different evaluation needs.
|
||||
- **🤖 Agent Evaluation Mode**: Drives benchmarks (e.g. GSM8K, AIME, SWE-bench Agentic) inside a controlled multi-turn AgentLoop with pluggable strategies, tools and Docker sandbox; full per-sample Agent Trace is recorded and visualizable.
|
||||
- **⚡ Inference Performance Testing**: Provides powerful model service stress testing tools, supporting multiple performance metrics such as TTFT, TPOT.
|
||||
- **📊 Interactive Reports**: Provides a Web Dashboard for multi-dimensional model comparison, report overview and detailed inspection.
|
||||
- **⚔️ Arena Mode**: Supports multi-model battles (Pairwise Battle), intuitively ranking and evaluating models.
|
||||
- **🔧 Highly Extensible**: Developers can easily add custom datasets, models and evaluation metrics.
|
||||
|
||||
## 📊 Visualization Preview
|
||||
|
||||
EvalScope provides an interactive Web Dashboard for multi-dimensional model comparison and in-depth analysis.
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td style="text-align: center;">
|
||||
<img src="https://sail-moe.oss-cn-hangzhou.aliyuncs.com/yunlin/images/evalscope/dashboard/dashboard_overview.png" alt="Dashboard" style="width: 100%;" />
|
||||
<p>Dashboard Overview</p>
|
||||
</td>
|
||||
<td style="text-align: center;">
|
||||
<img src="https://sail-moe.oss-cn-hangzhou.aliyuncs.com/yunlin/images/evalscope/dashboard/compare_score_tab.png" alt="Model Compare" style="width: 100%;" />
|
||||
<p>Model Comparison</p>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style="text-align: center;">
|
||||
<img src="https://sail-moe.oss-cn-hangzhou.aliyuncs.com/yunlin/images/evalscope/dashboard/report_overview_tab.png" alt="Report Overview" style="width: 100%;" />
|
||||
<p>Report Overview</p>
|
||||
</td>
|
||||
<td style="text-align: center;">
|
||||
<img src="https://sail-moe.oss-cn-hangzhou.aliyuncs.com/yunlin/images/evalscope/dashboard/report_predictions_tab.png" alt="Report Predictions" style="width: 90%;" />
|
||||
<p>Prediction Details</p>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
For details, please refer to [📖 Visualizing Evaluation Results](https://evalscope.readthedocs.io/en/latest/get_started/visualization.html).
|
||||
|
||||
## 🎉 What's New
|
||||
|
||||
- 🔥 **[2026.08.24] v1.11.0** Introduced published evaluation versions for reproducible benchmark results; improved report semantics and incomplete-run handling; strengthened multimodal media loading and task-config validation.
|
||||
- 🔥 **[2026.08.13]** Improved evaluation reports with unified metric semantics and more reliable Agent Trace step grouping and tool-call/result linking.
|
||||
- 🔥 **[2026.08.10]** Added **AutomationBench**, **JobBench**, **MiniWoB**, **OmniDocBench-v1.6**, **PerceptionBench**, **ScreenSpot-Pro**, **PLawBench**, **PMC-VQA**, **HiPhO**, **LogicVista**, and **CC-OCR-V2** benchmarks.
|
||||
- 🔥 **[2026.07.21]** Added **Claw-Eval**, **ResearchRubrics**, **Toolathlon** (agent), **TVBench** (video), **WideSearch**, and **PerspectiveGap** benchmarks.
|
||||
- 🔥 **[2026.07.03]** Added **CharXiv** & **BabyVision** (chart understanding, visual cognition) and **ERQA** & **WorldVQA** (entity-recognition QA with LLM-judge + CoT) multimodal benchmarks.
|
||||
- 🔥 **[2026.06.23]** Major agent & code evaluation expansion: added **BigCodeBench**, **SWE-bench Multilingual**, **BrowseComp**, **MCP-Atlas**, **GDPval** benchmarks; added **OpenCode** / **OpenHands** runners; refactored adapter architecture with `AudioLanguageAdapter`, unified `FunctionCallAdapter`, and public `run_agent_loop` API.
|
||||
- 🔥 **[2026.06.16]** Added full-reference **image quality metrics** (SSIM, PSNR, etc.), long-context benchmarks (**LoCoMo QA**, **LongMemEval**), **Caption** & **Maritime-OCR-Bench** benchmarks; perf module now supports unified `--data-source` and parallelized request generation.
|
||||
- 🔥 **[2026.06.02]** Refactored **RAG evaluation** module: upgraded to MTEB 2.x and RAGAS 0.4.x, with unified Pydantic-based configs. See the [RAGEval guide](https://evalscope.readthedocs.io/en/latest/user_guides/backend/rageval_backend/index.html).
|
||||
- 🔥 **[2026.05.27]** Added **Trie agentic trace replay** for perf benchmarking: three new dataset plugins (`trie_agentic_coding` / `trie_code_qa` / `trie_office_work`) replay real multi-turn agent traces with per-turn token caps and tool-call latency simulation. Also introduced a `--duration` wall-clock budget for all benchmark modes and a `Turn` dataclass for per-turn overrides.
|
||||
- 🔥 **[2026.05.27]** Added **Vendor Verifier benchmarks** (`k2_verifier`, `kimi_verifier`, `minimax_verifier`) for validating whether third-party API deployments faithfully reproduce official model behavior, with a shared `FunctionCallAdapter` base class.
|
||||
- 🔥 **[2026.05.26]** Added the [GAIA](https://evalscope.readthedocs.io/en/latest/third_party/gaia.html) agent benchmark (multi-turn ReAct + `bash` in a Docker sandbox, official rule-based scorer) and generic [MCP server](https://evalscope.readthedocs.io/en/latest/user_guides/agent/native.html#mcp-server-tools) support — any `NativeAgentConfig`-driven benchmark can now plug in stdio / HTTP / SSE MCP servers (`fetch`, web search, GitHub, ...) without per-benchmark wiring.
|
||||
- 🔥 **[2026.05.22]** Introduced the **External Agent Bridge** mode: evaluate off-the-shelf agent CLIs such as Anthropic's [Claude Code](https://github.com/anthropics/claude-code) and OpenAI's [Codex](https://github.com/openai/codex) directly through EvalScope. The bridge transparently forwards each CLI's LLM traffic (Anthropic Messages / OpenAI Chat / OpenAI Responses, including SSE streaming) to your evaluation model, while recording the full trajectory as an `agent_trace`. Bring-your-own-runner via `@register_runner`. See the [External Agent Bridge guide](https://evalscope.readthedocs.io/en/latest/user_guides/agent/bridge.html).
|
||||
- 🔥 **[2026.05.19]** Added support for [SWE-bench_Pro](https://evalscope.readthedocs.io/en/latest/third_party/swe_bench_pro.html) and [τ³-bench](https://evalscope.readthedocs.io/en/latest/third_party/tau3_bench.html): SWE-bench_Pro is a more challenging multilingual long-horizon software-engineering benchmark from Scale AI (recommended over the original SWE-bench for less data contamination and broader language coverage; per-instance Docker images are pulled directly from DockerHub, no local image build required); τ³-bench is the v1.0.0 release of the tau-bench family, extending τ²-bench with a new `banking_knowledge` retrieval domain (RAG), 75+ task fixes across existing domains, and pluggable retrieval pipelines (BM25 / embeddings / rerankers / sandbox shell).
|
||||
|
||||
<details><summary>More historical updates</summary>
|
||||
|
||||
- 🔥 **[2026.05.15]** Introduced **Agent Evaluation Mode**: any benchmark based on `DefaultDataAdapter` (GSM8K, AIME, IFEval, etc.) can now be driven through a multi-turn AgentLoop with pluggable strategies (`function_calling` / `react` / `swe_bench_*`), tools (`bash` / `python_exec` / `submit`) and `local` / `docker` environments. Per-sample `agent_trace` is recorded and rendered step-by-step in the dashboard's Predictions tab. See the [Agent Evaluation guide](https://evalscope.readthedocs.io/en/latest/user_guides/agent/native.html) for details.
|
||||
- 🔥 **[2026.05.08]** Partnered with [LightSeek](https://lightseek.org/) to launch [TokenSpeed](https://lightseek.org/blog/lightseek-tokenspeed.html), a speed-of-light LLM inference engine for agentic workloads. EvalScope provides the SWE-smith benchmarking pipeline — using real coding-agent traces to measure per-GPU throughput (TPM) and per-user latency (TPS) — serving as the official benchmark tool for TokenSpeed performance evaluation. Refer to the [SWE-smith usage guide](https://evalscope.readthedocs.io/en/latest/user_guides/stress_test/multi_turn.html#swe-smith) to get started.
|
||||
|
||||
- 🔥 **[2026.05.07]** Replaced the Gradio-based WebUI with a new React + Vite web interface for better performance and user experience.
|
||||
- 🔥 **[2026.04.23]** Added support for recording performance (perf) metrics during evaluation tasks, enabling simultaneous tracking of model accuracy and inference efficiency metrics such as TTFT, TPOT, and throughput in a single evaluation run.
|
||||
- 🔥 **[2026.04.17]** Added support for multi-turn conversation performance stress testing, enabling load testing of dialogue-based model services with multi-turn context. Refer to the [usage documentation](https://evalscope.readthedocs.io/en/latest/user_guides/stress_test/examples.html).
|
||||
- 🔥 **[2026.04.10]** Added support for [TIR-Bench](https://arxiv.org/abs/2511.01833) (Thinking-with-Images Reasoning Benchmark), a multimodal benchmark evaluating agentic visual reasoning capabilities of vision-language models.
|
||||
- 🔥 **[2026.03.24]** Added support for Agent Skill. Any agent model that supports Skill/Tool calling can use natural language to drive EvalScope for model evaluation, performance benchmarking, and result visualization.
|
||||
- 🔥 **[2026.03.09]** Added support for evaluation progress tracking and HTML format visualization report generation.
|
||||
- 🔥 **[2026.03.02]** Added support for Anthropic Claude API evaluation. Use `--eval-type anthropic_api` to evaluate models via Anthropic API service.
|
||||
- 🔥 **[2026.02.03]** Comprehensive update to dataset documentation, adding data statistics, data samples, usage instructions and more.
|
||||
- 🔥 **[2026.01.13]** Added support for Embedding and Rerank model service stress testing.
|
||||
- 🔥 **[2025.12.26]** Added support for Terminal-Bench-2.0, which evaluates AI Agent performance on 89 real-world multi-step terminal tasks.
|
||||
- 🔥 **[2025.12.18]** Added support for SLA auto-tuning model API services.
|
||||
- 🔥 **[2025.12.16]** Added support for audio evaluation benchmarks such as Fleurs, LibriSpeech; added support for multilingual code evaluation benchmarks such as MultiplE, MBPP.
|
||||
- 🔥 **[2025.12.02]** Added support for custom multimodal VQA evaluation; added support for visualizing model service stress testing in ClearML.
|
||||
- 🔥 **[2025.11.26]** Added support for OpenAI-MRCR, GSM8K-V, MGSM, MicroVQA, IFBench, SciCode benchmarks.
|
||||
- 🔥 **[2025.11.18]** Added support for custom Function-Call (tool invocation) datasets to test whether models can timely and correctly call tools.
|
||||
- 🔥 **[2025.11.14]** Added support for SWE-bench_Verified, SWE-bench_Lite, SWE-bench_Verified_mini code evaluation benchmarks.
|
||||
- 🔥 **[2025.11.12]** Added `pass@k`, `vote@k`, `pass^k` and other metric aggregation methods; added support for multimodal evaluation benchmarks such as A_OKVQA, CMMU, ScienceQA, V*Bench.
|
||||
- 🔥 **[2025.11.07]** Added support for τ²-bench, an extended and enhanced version of τ-bench that includes a series of code fixes and adds telecom domain troubleshooting scenarios.
|
||||
- 🔥 **[2025.10.30]** Added support for BFCL-v4, enabling evaluation of agent capabilities including web search and long-term memory.
|
||||
- 🔥 **[2025.10.27]** Added support for LogiQA, HaluEval, MathQA, MRI-QA, PIQA, QASC, CommonsenseQA and other evaluation benchmarks. Thanks to @[penguinwang96825](https://github.com/penguinwang96825) for the code implementation.
|
||||
- 🔥 **[2025.10.26]** Added support for Conll-2003, CrossNER, Copious, GeniaNER, HarveyNER, MIT-Movie-Trivia, MIT-Restaurant, OntoNotes5, WNUT2017 and other Named Entity Recognition evaluation benchmarks. Thanks to @[penguinwang96825](https://github.com/penguinwang96825) for the code implementation.
|
||||
- 🔥 **[2025.10.21]** Optimized sandbox environment usage in code evaluation, supporting both local and remote operation modes.
|
||||
- 🔥 **[2025.10.20]** Added support for evaluation benchmarks including PolyMath, SimpleVQA, MathVerse, MathVision, AA-LCR; optimized evalscope perf performance to align with vLLM Bench.
|
||||
- 🔥 **[2025.10.14]** Added support for OCRBench, OCRBench-v2, DocVQA, InfoVQA, ChartQA, and BLINK multimodal image-text evaluation benchmarks.
|
||||
- 🔥 **[2025.09.22]** Code evaluation benchmarks (HumanEval, LiveCodeBench) now support running in a sandbox environment.
|
||||
- 🔥 **[2025.09.19]** Added support for multimodal image-text evaluation benchmarks including RealWorldQA, AI2D, MMStar, MMBench, and OmniBench, as well as pure text evaluation benchmarks such as Multi-IF, HealthBench, and AMC.
|
||||
- 🔥 **[2025.09.05]** Added support for vision-language multimodal model evaluation tasks, such as MathVista and MMMU.
|
||||
- 🔥 **[2025.09.04]** Added support for image editing task evaluation, including the [GEdit-Bench](https://modelscope.cn/datasets/stepfun-ai/GEdit-Bench) benchmark.
|
||||
- 🔥 **[2025.08.22]** Version 1.0 Refactoring. Break changes, please [refer to](https://evalscope.readthedocs.io/en/latest/get_started/basic_usage.html#switching-to-version-v1-0).
|
||||
- 🔥 **[2025.07.18]** The model stress testing now supports randomly generating image-text data for multimodal model evaluation.
|
||||
- 🔥 **[2025.07.16]** Support for [τ-bench](https://github.com/sierra-research/tau-bench) has been added.
|
||||
- 🔥 **[2025.07.14]** Support for "Humanity's Last Exam" ([Humanity's-Last-Exam](https://modelscope.cn/datasets/cais/hle)).
|
||||
- 🔥 **[2025.07.03]** Refactored Arena Mode.
|
||||
- 🔥 **[2025.06.28]** Optimized custom dataset evaluation; enhanced LLM judge usage.
|
||||
- 🔥 **[2025.06.19]** Added support for the [BFCL-v3](https://modelscope.cn/datasets/AI-ModelScope/bfcl_v3) benchmark.
|
||||
- 🔥 **[2025.06.02]** Added support for the Needle-in-a-Haystack test.
|
||||
- 🔥 **[2025.05.29]** Added support for two long document evaluation benchmarks: DocMath and FRAMES.
|
||||
- 🔥 **[2025.05.16]** Model service performance stress testing now supports setting various levels of concurrency.
|
||||
- 🔥 **[2025.05.13]** Added support for the ToolBench-Static dataset, DROP and Winogrande benchmarks.
|
||||
- 🔥 **[2025.04.29]** Added Qwen3 Evaluation Best Practices.
|
||||
- 🔥 **[2025.04.27]** Support for text-to-image evaluation.
|
||||
- 🔥 **[2025.04.10]** Model service stress testing tool now supports the `/v1/completions` endpoint.
|
||||
- 🔥 **[2025.04.08]** Support for evaluating embedding model services compatible with the OpenAI API has been added.
|
||||
- 🔥 **[2025.03.27]** Added support for AlpacaEval and ArenaHard evaluation benchmarks.
|
||||
- 🔥 **[2025.03.20]** The model inference service stress testing now supports generating prompts of specified length using random values.
|
||||
- 🔥 **[2025.03.13]** Added support for the LiveCodeBench code evaluation benchmark.
|
||||
- 🔥 **[2025.03.11]** Added support for the SimpleQA and Chinese SimpleQA evaluation benchmarks.
|
||||
- 🔥 **[2025.03.07]** Added support for the QwQ-32B model evaluation.
|
||||
- 🔥 **[2025.03.04]** Added support for the SuperGPQA dataset.
|
||||
- 🔥 **[2025.03.03]** Added support for evaluating the IQ and EQ of models.
|
||||
- 🔥 **[2025.02.27]** Added support for evaluating the reasoning efficiency of models.
|
||||
- 🔥 **[2025.02.25]** Added support for MuSR and ProcessBench benchmarks.
|
||||
- 🔥 **[2025.02.18]** Supports the AIME25 dataset.
|
||||
- 🔥 **[2025.02.13]** Added support for evaluating DeepSeek distilled models.
|
||||
- 🔥 **[2025.01.20]** Support for visualizing evaluation results.
|
||||
- 🔥 **[2025.01.07]** Native backend: Support for model API evaluation.
|
||||
- 🔥🔥 **[2024.12.31]** Support for adding benchmark evaluations.
|
||||
- 🔥 **[2024.12.13]** Model evaluation optimization.
|
||||
- 🔥 **[2024.11.26]** The model inference service performance evaluator has been completely refactored.
|
||||
- 🔥 **[2024.10.31]** The best practice for evaluating Multimodal-RAG has been updated.
|
||||
- 🔥 **[2024.10.23]** Supports multimodal RAG evaluation.
|
||||
- 🔥 **[2024.10.8]** Support for RAG evaluation.
|
||||
- 🔥 **[2024.09.18]** Documentation added blog module.
|
||||
- 🔥 **[2024.09.12]** Support for LongWriter evaluation.
|
||||
- 🔥 **[2024.08.30]** Support for custom dataset evaluations.
|
||||
- 🔥 **[2024.08.20]** Updated the official documentation.
|
||||
- 🔥 **[2024.08.09]** Simplified the installation process.
|
||||
- 🔥 **[2024.07.31]** Important change: The package name `llmuses` has been changed to `evalscope`.
|
||||
- 🔥 **[2024.07.26]** Support for **VLMEvalKit** as a third-party evaluation framework.
|
||||
- 🔥 **[2024.06.29]** Support for **OpenCompass** as a third-party evaluation framework.
|
||||
- 🔥 **[2024.06.13]** EvalScope integrates with SWIFT; Integrated the Agent evaluation dataset ToolBench.
|
||||
|
||||
</details>
|
||||
|
||||
## 🚀 Quick Start
|
||||
|
||||
### Installation
|
||||
|
||||
```shell
|
||||
pip install evalscope
|
||||
```
|
||||
|
||||
> For detailed installation instructions (source install, extra dependencies, etc.), please refer to the [📖 Installation Guide](https://evalscope.readthedocs.io/en/latest/get_started/installation.html).
|
||||
|
||||
### Method 1. Evaluate an Online Model API (Recommended for beginners, no GPU required)
|
||||
|
||||
Supports any OpenAI API-compatible model service. Just set `$OPENAI_API_BASE_URL` and `$OPENAI_API_KEY` and you are ready to go:
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model your-model-name \
|
||||
--api-url $OPENAI_API_BASE_URL \
|
||||
--api-key $OPENAI_API_KEY \
|
||||
--eval-type openai_api \
|
||||
--datasets gsm8k arc \
|
||||
--limit 5
|
||||
```
|
||||
|
||||
### Method 2. Evaluate a Local Model
|
||||
|
||||
Evaluate a local model (auto-downloaded from ModelScope):
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model Qwen/Qwen2.5-0.5B-Instruct \
|
||||
--datasets gsm8k arc \
|
||||
--limit 5
|
||||
```
|
||||
|
||||
### Method 3. Using Python Code
|
||||
|
||||
```python
|
||||
from evalscope import run_task, TaskConfig
|
||||
|
||||
datasets = [
|
||||
'live_code_bench',
|
||||
'swe_bench_pro',
|
||||
'aime26',
|
||||
'hmmt26',
|
||||
'imo_answerbench',
|
||||
'super_gpqa',
|
||||
'drop',
|
||||
'hellaswag',
|
||||
'mmlu',
|
||||
'openai_mrcr',
|
||||
'mcp_atlas',
|
||||
]
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
collect_perf=True,
|
||||
work_dir='/data1/sora/benchmarks/temp/output',
|
||||
use_cache='/data1/sora/benchmarks/temp/output',
|
||||
no_timestamp=True,
|
||||
limit=1,
|
||||
model='',
|
||||
api_url='http://localhost:30000/v1',
|
||||
model='your-model-name',
|
||||
api_url='https://your-openai-compatible-endpoint/v1',
|
||||
api_key='your_api_key',
|
||||
eval_type='openai_api',
|
||||
datasets=datasets,
|
||||
dataset_dir='/data1/sora/benchmarks/bash/datasets',
|
||||
generation_config={
|
||||
'temperature': 0.0,
|
||||
'stream': True,
|
||||
'max_tokens': 4096,
|
||||
},
|
||||
eval_batch_size=1,
|
||||
judge_model_args={
|
||||
"model_id": "deepseek-v4-flash",
|
||||
"api_url": "https://api.deepseek.com/v1",
|
||||
"api_key": "<YOUR_DEEPSEEK_API_KEY>",
|
||||
"eval_type": "openai_api",
|
||||
"generation_config": {
|
||||
"temperature": 0.0,
|
||||
"max_tokens": 1024 * 10,
|
||||
},
|
||||
}
|
||||
datasets=['gsm8k', 'arc'],
|
||||
limit=5
|
||||
)
|
||||
|
||||
run_task(task_cfg)
|
||||
```
|
||||
|
||||
## 3. 评测结果
|
||||
<details><summary><b>💡 Tip:</b> <code>run_task</code> also supports dictionaries, YAML or JSON files as configuration.</summary>
|
||||
|
||||
P800 模型能力评测结果。
|
||||
**Using Python Dictionary**
|
||||
|
||||
## 4. UI 界面
|
||||
```python
|
||||
from evalscope.run import run_task
|
||||
|
||||
```bash
|
||||
pip install flask sse_starlette
|
||||
cd ./evalscope/web
|
||||
npm install
|
||||
npm run build
|
||||
evalscope service
|
||||
task_cfg = {
|
||||
'model': 'Qwen/Qwen2.5-0.5B-Instruct',
|
||||
'datasets': ['gsm8k', 'arc'],
|
||||
'limit': 5
|
||||
}
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
然后访问 `http://127.0.0.1:9000/dashboard`。
|
||||
**Using YAML File** (`config.yaml`)
|
||||
```yaml
|
||||
model: Qwen/Qwen2.5-0.5B-Instruct
|
||||
datasets:
|
||||
- gsm8k
|
||||
- arc
|
||||
limit: 5
|
||||
```
|
||||
```python
|
||||
from evalscope.run import run_task
|
||||
|
||||
run_task(task_cfg="config.yaml")
|
||||
```
|
||||
</details>
|
||||
|
||||
### Output Results
|
||||
After evaluation completion, you will see a report in the terminal in the following format:
|
||||
```text
|
||||
┌───────────────────────┬───────────┬────────────┬───────────────┬───────┬─────────┐
|
||||
│ Model │ Dataset │ Metric │ Subset │ Num │ Score │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ gsm8k │ Accuracy ↑ │ main │ 5 │ 40% │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ arc │ Accuracy ↑ │ ARC-Easy │ 5 │ 80% │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ arc │ Accuracy ↑ │ ARC-Challenge │ 5 │ 40% │
|
||||
└───────────────────────┴───────────┴────────────┴───────────────┴───────┴─────────┘
|
||||
```
|
||||
|
||||
**Launch the visualization dashboard**:
|
||||
```bash
|
||||
pip install 'evalscope[service]'
|
||||
evalscope service
|
||||
```
|
||||
Visit `http://127.0.0.1:9000` to open the visualization interface.
|
||||
|
||||
## 📈 Advanced Usage
|
||||
|
||||
### Custom Evaluation Parameters
|
||||
|
||||
You can fine-tune model loading, inference, and dataset configuration through command line parameters.
|
||||
|
||||
```shell
|
||||
evalscope eval \
|
||||
--model Qwen/Qwen3-0.6B \
|
||||
--model-args '{"revision": "master", "precision": "torch.float16", "device_map": "auto"}' \
|
||||
--generation-config '{"do_sample":true,"temperature":0.6,"max_tokens":512}' \
|
||||
--dataset-args '{"gsm8k": {"few_shot_num": 0, "few_shot_random": false}}' \
|
||||
--datasets gsm8k \
|
||||
--limit 10
|
||||
```
|
||||
|
||||
- `--model-args`: Model loading parameters such as `revision`, `precision`, etc.
|
||||
- `--generation-config`: Model generation parameters such as `temperature`, `max_tokens`, etc.
|
||||
- `--dataset-args`: Dataset configuration parameters such as `few_shot_num`, etc.
|
||||
|
||||
For details, please refer to [📖 Complete Parameter Guide](https://evalscope.readthedocs.io/en/latest/get_started/parameters.html).
|
||||
|
||||
### ⚔️ Arena Mode
|
||||
|
||||
Arena mode evaluates model performance through pairwise battles between models, providing win rates and rankings, perfect for horizontal comparison of multiple models.
|
||||
|
||||
```text
|
||||
# Example evaluation results
|
||||
Model WinRate (%) CI (%)
|
||||
------------ ------------- ---------------
|
||||
qwen2.5-72b 69.3 (-13.3 / +12.2)
|
||||
qwen2.5-7b 50 (+0.0 / +0.0)
|
||||
qwen2.5-0.5b 4.7 (-2.5 / +4.4)
|
||||
```
|
||||
For details, please refer to [📖 Arena Mode Usage Guide](https://evalscope.readthedocs.io/en/latest/user_guides/arena.html).
|
||||
|
||||
### 🖊️ Custom Dataset Evaluation
|
||||
|
||||
EvalScope allows you to easily add and evaluate your own datasets. For details, please refer to [📖 Custom Dataset Evaluation Guide](https://evalscope.readthedocs.io/en/latest/advanced_guides/custom_dataset/index.html).
|
||||
|
||||
## ⚡ Inference Performance Evaluation Tool
|
||||
|
||||
EvalScope provides a powerful stress testing tool for evaluating the performance of large language model services.
|
||||
|
||||
- **Key Metrics**: Supports throughput (Tokens/s), first token latency (TTFT), token generation latency (TPOT), etc.
|
||||
- **Result Recording**: Supports recording results to `wandb` and `swanlab`.
|
||||
- **Speed Benchmarks**: Can generate speed benchmark results similar to official reports.
|
||||
|
||||
For details, please refer to [📖 Performance Testing Usage Guide](https://evalscope.readthedocs.io/en/latest/user_guides/stress_test/index.html).
|
||||
|
||||
<p align="center">
|
||||
<img src="docs/en/user_guides/stress_test/images/multi_perf.png" style="width: 80%;">
|
||||
</p>
|
||||
|
||||
## 🧪 Other Evaluation Backends
|
||||
EvalScope supports launching evaluation tasks through third-party evaluation frameworks (we call them "backends") to meet diverse evaluation needs.
|
||||
|
||||
- **Native**: EvalScope's default evaluation framework with comprehensive functionality.
|
||||
- **OpenCompass**: Focuses on text-only evaluation. [📖 Usage Guide](https://evalscope.readthedocs.io/en/latest/user_guides/backend/opencompass_backend.html)
|
||||
- **VLMEvalKit**: Focuses on multi-modal evaluation. [📖 Usage Guide](https://evalscope.readthedocs.io/en/latest/user_guides/backend/vlmevalkit_backend.html)
|
||||
- **RAGEval**: Focuses on RAG evaluation, supporting Embedding and Reranker models. [📖 Usage Guide](https://evalscope.readthedocs.io/en/latest/user_guides/backend/rageval_backend/index.html)
|
||||
- **Third-party Evaluation Tools**: Supports evaluation tasks like [ToolBench](https://evalscope.readthedocs.io/en/latest/third_party/toolbench.html).
|
||||
|
||||
<details><summary>🏛️ Overall Architecture</summary>
|
||||
|
||||
<p align="center">
|
||||
<img src="https://sail-moe.oss-cn-hangzhou.aliyuncs.com/yunlin/images/evalscope/doc/EvalScope%E6%9E%B6%E6%9E%84%E5%9B%BE.png" style="width: 70%;">
|
||||
<br>EvalScope Overall Architecture.
|
||||
</p>
|
||||
|
||||
1. **Input Layer**
|
||||
- **Model Sources**: API models (OpenAI API), Local models (ModelScope)
|
||||
- **Datasets**: Standard evaluation benchmarks (MMLU/GSM8k etc.), Custom data (MCQ/QA)
|
||||
|
||||
2. **Core Functions**
|
||||
- **Multi-backend Evaluation**: Native backend, OpenCompass, MTEB, VLMEvalKit, RAGAS
|
||||
- **Performance Monitoring**: Supports multiple model service APIs and data formats, tracking TTFT/TPOT and other metrics
|
||||
- **Tool Extensions**: Integrates Tool-Bench, Needle-in-a-Haystack, etc.
|
||||
|
||||
3. **Output Layer**
|
||||
- **Structured Reports**: Supports JSON, Table, Logs
|
||||
- **Visualization Platform**: Supports Web Dashboard, Wandb, SwanLab
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
## ❤️ Community & Support
|
||||
|
||||
Welcome to join our community to communicate with other developers and get help.
|
||||
|
||||
[Discord Group](https://discord.gg/xc66bMxc4h) | WeChat Group | DingTalk Group
|
||||
:-------------------------:|:-------------------------:|:-------------------------:
|
||||
<img src="docs/asset/discord_qr.png" width="160" height="160"> | <img src="https://raw.githubusercontent.com/modelscope/ms-swift/main/asset/wechat.png" width="160" height="160"> | <img src="docs/asset/dingding.png" width="160" height="160">
|
||||
|
||||
## 👷♂️ Contributing
|
||||
|
||||
We welcome any contributions from the community! If you want to add new evaluation benchmarks, models, or features, please refer to our [Contributing Guide](https://evalscope.readthedocs.io/en/latest/advanced_guides/add_benchmark.html).
|
||||
|
||||
Thanks to all developers who have contributed to EvalScope!
|
||||
|
||||
<a href="https://github.com/modelscope/evalscope/graphs/contributors" target="_blank">
|
||||
<table>
|
||||
<tr>
|
||||
<th colspan="2">
|
||||
<br><img src="https://contrib.rocks/image?repo=modelscope/evalscope"><br><br>
|
||||
</th>
|
||||
</tr>
|
||||
</table>
|
||||
</a>
|
||||
|
||||
## 📚 Citation
|
||||
|
||||
If you use EvalScope in your research, please cite our work:
|
||||
```bibtex
|
||||
@misc{evalscope_2024,
|
||||
title={{EvalScope}: Evaluation Framework for Large Models},
|
||||
author={ModelScope Team},
|
||||
year={2024},
|
||||
url={https://github.com/modelscope/evalscope}
|
||||
}
|
||||
```
|
||||
|
||||
@ -13,6 +13,7 @@
|
||||
<a href="https://badge.fury.io/py/evalscope"><img src="https://badge.fury.io/py/evalscope.svg" alt="PyPI version" height="18"></a>
|
||||
<a href="https://pypi.org/project/evalscope"><img alt="PyPI - Downloads" src="https://static.pepy.tech/badge/evalscope"></a>
|
||||
<a href="https://github.com/modelscope/evalscope/pulls"><img src="https://img.shields.io/badge/PR-welcome-55EB99.svg"></a>
|
||||
<a href="https://github.com/modelscope/evalscope"><img alt="GitHub stars" src="https://img.shields.io/github/stars/modelscope/evalscope?style=flat&logo=github"></a>
|
||||
<a href='https://evalscope.readthedocs.io/zh-cn/latest/?badge=latest'><img src='https://readthedocs.org/projects/evalscope/badge/?version=latest' alt='Documentation Status' /></a>
|
||||
<p>
|
||||
|
||||
@ -39,7 +40,7 @@ evalscope eval --model your-model-name --api-url $OPENAI_API_BASE_URL --api-key
|
||||
- **🚀 多后端集成**: 无缝集成 OpenCompass, VLMEvalKit, RAGEval 等多种评测后端,满足不同评测需求。
|
||||
- **🤖 Agent 评测模式**: 在受控的多轮 AgentLoop 中驱动 GSM8K、AIME、SWE-bench Agentic 等基准;支持可插拔的策略、工具与 Docker 沙箱,每条样本完整记录 Agent Trace 并可在仪表盘中按步骤回放。
|
||||
- **⚡ 推理性能测试**: 提供强大的模型服务压力测试工具,支持 TTFT, TPOT 等多项性能指标。
|
||||
- **📊 交互式报告**: 提供 WebUI 可视化界面,支持多维度模型对比、报告概览和详情查阅。
|
||||
- **📊 交互式报告**: 提供 Web Dashboard,支持多维度模型对比、报告概览和详情查阅。
|
||||
- **⚔️ 竞技场模式**: 支持多模型对战 (Pairwise Battle),直观地对模型进行排名和评估。
|
||||
- **🔧 高度可扩展**: 开发者可以轻松添加自定义数据集、模型和评测指标。
|
||||
|
||||
@ -74,6 +75,10 @@ EvalScope 提供交互式 Web Dashboard,支持多维度模型对比和深入
|
||||
|
||||
## 🎉 内容更新
|
||||
|
||||
- 🔥 **[2026.08.24] v1.11.0** 引入可发布的评测版本标识,保障基准结果可复现;优化评测报告语义与不完整运行处理,并增强多模态媒体加载和任务配置校验。
|
||||
- 🔥 **[2026.08.13]** 评测报告升级:统一指标语义,并改善 Agent Trace 步骤分组与工具调用/结果关联的可靠性。
|
||||
- 🔥 **[2026.08.10]** 新增 **AutomationBench**、**JobBench**、**MiniWoB**、**OmniDocBench-v1.6**、**PerceptionBench**、**ScreenSpot-Pro**、**PLawBench**、**PMC-VQA**、**HiPhO**、**LogicVista** 和 **CC-OCR-V2** 基准。
|
||||
- 🔥 **[2026.07.21]** 新增 **Claw-Eval**、**ResearchRubrics**、**Toolathlon**(Agent)、**TVBench**(视频)、**WideSearch**、**PerspectiveGap** 基准。
|
||||
- 🔥 **[2026.07.03]** 新增 **CharXiv** & **BabyVision**(图表理解、视觉认知)及 **ERQA** & **WorldVQA**(实体识别 QA,支持 LLM judge + CoT)多模态基准。
|
||||
- 🔥 **[2026.06.23]** Agent 与代码评测大幅扩展:新增 **BigCodeBench**、**SWE-bench Multilingual**、**BrowseComp**、**MCP-Atlas**、**GDPval** 基准;新增 **OpenCode** / **OpenHands** runner;适配器架构重构,引入 `AudioLanguageAdapter`、统一 `FunctionCallAdapter`、公开 `run_agent_loop` API。
|
||||
- 🔥 **[2026.06.16]** 新增全参考**图像质量指标**(SSIM、PSNR 等)、长上下文基准(**LoCoMo QA**、**LongMemEval**)、**Caption** & **Maritime-OCR-Bench** 基准;Perf 模块支持统一 `--data-source` 参数及并行化请求生成。
|
||||
@ -83,14 +88,16 @@ EvalScope 提供交互式 Web Dashboard,支持多维度模型对比和深入
|
||||
- 🔥 **[2026.05.26]** 新增 [GAIA](https://evalscope.readthedocs.io/zh-cn/latest/third_party/gaia.html) agent 基准(Docker sandbox 内多轮 ReAct + `bash`,复用官方规则评分器)和通用 [MCP 服务器](https://evalscope.readthedocs.io/zh-cn/latest/user_guides/agent/native.html#mcp-工具接入)接入 —— 任何基于 `NativeAgentConfig` 的 benchmark 都可直接挂载 stdio / HTTP / SSE 的 MCP server(`fetch`、网页搜索、GitHub 等),无需 benchmark 端改动。
|
||||
- 🔥 **[2026.05.22]** 新增 **外部 Agent Bridge** 模式:可直接评测 Anthropic [Claude Code](https://github.com/anthropics/claude-code)、OpenAI [Codex](https://github.com/openai/codex) 等成品 Agent CLI。Bridge 透明转发 CLI 的 LLM 请求(Anthropic Messages / OpenAI Chat / OpenAI Responses,含 SSE 流式响应)到评测模型,同时把完整交互轨迹录制为 `agent_trace`;通过 `@register_runner` 可接入任意第三方 CLI。详见[外部 Agent Bridge 指南](https://evalscope.readthedocs.io/zh-cn/latest/user_guides/agent/bridge.html)。
|
||||
- 🔥 **[2026.05.19]** 新增对 [SWE-bench_Pro](https://evalscope.readthedocs.io/zh-cn/latest/third_party/swe_bench_pro.html) 与 [τ³-bench](https://evalscope.readthedocs.io/zh-cn/latest/third_party/tau3_bench.html) 的支持:SWE-bench_Pro 是 Scale AI 推出的更具挑战性的多语言、长周期软件工程基准,相比原始 SWE-bench 数据污染更少、覆盖语言更广,**推荐替代原始 SWE-bench 使用**,每个实例的 Docker 镜像直接从 DockerHub 拉取,无需本地构建;τ³-bench 是 tau-bench 系列的 v1.0.0 版本,在 τ²-bench 基础上新增 `banking_knowledge` 知识检索领域(RAG)、修复 75+ 项任务,并提供可插拔的检索流水线(BM25 / 稠密嵌入 / 重排序器 / 沙箱 shell)。
|
||||
|
||||
<details><summary>更多历史更新</summary>
|
||||
|
||||
- 🔥 **[2026.05.15]** 新增 **Agent 评测模式**:所有基于 `DefaultDataAdapter` 的基准(GSM8K、AIME、IFEval 等)现在均可通过多轮 AgentLoop 驱动,支持可插拔策略(`function_calling` / `react` / `swe_bench_*`)、工具(`bash` / `python_exec` / `submit`)以及 `local` / `docker` 运行环境,每条样本的 `agent_trace` 会随评测结果落盘,并在仪表盘的预测视图中按步骤回放。详见[Agent 评测指南](https://evalscope.readthedocs.io/zh-cn/latest/user_guides/agent/native.html)。
|
||||
- 🔥 **[2026.05.08]** 与 [LightSeek](https://lightseek.org/) 联合推出 [TokenSpeed](https://lightseek.org/blog/lightseek-tokenspeed.html)——面向 Agentic 工作负载的极速 LLM 推理引擎。EvalScope 提供 SWE-smith 压测流水线,基于真实 Coding Agent 轨迹衡量单 GPU 吞吐(TPM)与单用户延迟(TPS),作为 TokenSpeed 性能评测的官方基准工具。参考 [SWE-smith 使用指南](https://evalscope.readthedocs.io/zh-cn/latest/user_guides/stress_test/multi_turn.html#swe-smith) 快速上手。
|
||||
|
||||
- 🔥 **[2026.05.07]** 全新 Web 界面升级:使用 React + Vite 重构可视化平台,替换原有 Gradio 界面,提供更流畅的交互体验。
|
||||
- 🔥 **[2026.04.23]** 支持在评测任务中记录性能(perf)指标,可在单次评测运行中同时追踪模型准确率与 TTFT、TPOT、吞吐量等推理效率指标。
|
||||
- 🔥 **[2026.04.17]** 支持多轮对话性能压测,可对具备多轮上下文的对话模型服务进行负载测试,参考[使用文档](https://evalscope.readthedocs.io/zh-cn/latest/user_guides/stress_test/examples.html)。
|
||||
|
||||
<details><summary>更多历史更新</summary>
|
||||
|
||||
- 🔥 **[2026.04.10]** 新增支持 [TIR-Bench](https://arxiv.org/abs/2511.01833)(Thinking-with-Images Reasoning Benchmark),一个面向视觉语言模型的多模态推理基准。
|
||||
- 🔥 **[2026.03.24]** 支持 Agent Skill,任何支持 Skill/Tool 调用的 Agent 模型均可通过自然语言直接驱动 EvalScope 完成模型评测、性能压测和结果可视化。
|
||||
- 🔥 **[2026.03.09]** 支持评测进度追踪和自动生成HTML格式可视化报告。
|
||||
@ -247,15 +254,15 @@ run_task(task_cfg="config.yaml")
|
||||
### 输出结果
|
||||
评测完成后,您将在终端看到如下格式的报告:
|
||||
```text
|
||||
+-----------------------+----------------+-----------------+-----------------+---------------+-------+---------+
|
||||
| Model Name | Dataset Name | Metric Name | Category Name | Subset Name | Num | Score |
|
||||
+=======================+================+=================+=================+===============+=======+=========+
|
||||
| Qwen2.5-0.5B-Instruct | gsm8k | AverageAccuracy | default | main | 5 | 0.4 |
|
||||
+-----------------------+----------------+-----------------+-----------------+---------------+-------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | ai2_arc | AverageAccuracy | default | ARC-Easy | 5 | 0.8 |
|
||||
+-----------------------+----------------+-----------------+-----------------+---------------+-------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | ai2_arc | AverageAccuracy | default | ARC-Challenge | 5 | 0.4 |
|
||||
+-----------------------+----------------+-----------------+-----------------+---------------+-------+---------+
|
||||
┌───────────────────────┬───────────┬────────────┬───────────────┬───────┬─────────┐
|
||||
│ Model │ Dataset │ Metric │ Subset │ Num │ Score │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ gsm8k │ Accuracy ↑ │ main │ 5 │ 40% │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ arc │ Accuracy ↑ │ ARC-Easy │ 5 │ 80% │
|
||||
├───────────────────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
|
||||
│ Qwen2.5-0.5B-Instruct │ arc │ Accuracy ↑ │ ARC-Challenge │ 5 │ 40% │
|
||||
└───────────────────────┴───────────┴────────────┴───────────────┴───────┴─────────┘
|
||||
```
|
||||
|
||||
**启动可视化面板**:
|
||||
@ -341,7 +348,7 @@ EvalScope 支持通过第三方评测框架(我们称之为"后端")发起
|
||||
|
||||
2. **核心功能**
|
||||
- **多后端评估**: 原生后端、OpenCompass、MTEB、VLMEvalKit、RAGAS
|
||||
- **性能监控**: 支持多种模型服务 API 和数据格式,追踪 TTFT/TPOP 等指标
|
||||
- **性能监控**: 支持多种模型服务 API 和数据格式,追踪 TTFT/TPOT 等指标
|
||||
- **工具扩展**: 集成 Tool-Bench, Needle-in-a-Haystack 等
|
||||
|
||||
3. **输出层**
|
||||
@ -386,7 +393,3 @@ EvalScope 支持通过第三方评测框架(我们称之为"后端")发起
|
||||
url={https://github.com/modelscope/evalscope}
|
||||
}
|
||||
```
|
||||
|
||||
## ⭐ Star History
|
||||
|
||||
[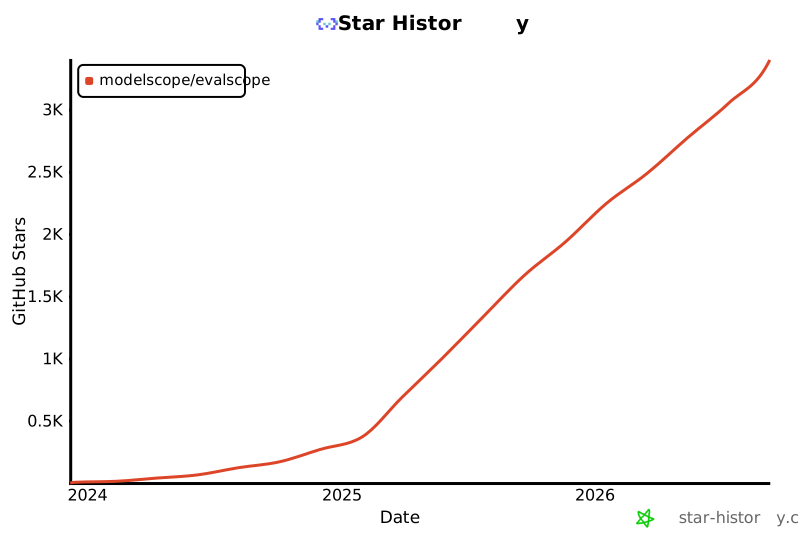](https://star-history.com/#modelscope/evalscope&Date)
|
||||
|
||||
@ -0,0 +1,5 @@
|
||||
{"messages": [{"role": "user", "content": "What animal is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/dog.jpg", "answer": "Dog"}
|
||||
{"messages": [{"role": "user", "content": "What building is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/AMNH.jpg", "answer": "Museum"}
|
||||
{"messages": [{"role": "user", "content": "Which city's skyline is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/tokyo.jpg", "answer": "Tokyo"}
|
||||
{"messages": [{"role": "user", "content": "What is the brand of this car?<image 1>"}], "image_1": "custom_eval/multimodal/images/tesla.jpg", "answer": "Tesla"}
|
||||
{"messages": [{"role": "user", "content": "What is the person in the picture doing?<image 1>"}], "image_1": "custom_eval/multimodal/images/running.jpg", "answer": "Running"}
|
||||
@ -47,7 +47,7 @@ DataAdapter adopts a Pipeline architecture, supporting custom behavior through h
|
||||
calculate_metrics()
|
||||
├── filter_prediction()
|
||||
│ └── extract_answer() [Optional User Implementation]
|
||||
├── match_score() / llm_match_score()
|
||||
├── match_score() / score_with_judge_contracts()
|
||||
└── Returns SampleScore
|
||||
|
||||
4. Result Aggregation Phase
|
||||
@ -61,6 +61,31 @@ DataAdapter adopts a Pipeline architecture, supporting custom behavior through h
|
||||
└── Returns Report
|
||||
```
|
||||
|
||||
### Adding an LLM-Judged Benchmark
|
||||
|
||||
Users enable judging with the typed `judge` configuration described in [Judge Parameters](../get_started/parameters.md#judge-parameters):
|
||||
|
||||
```python
|
||||
TaskConfig(
|
||||
model='MODEL_UNDER_TEST',
|
||||
datasets=['your_benchmark'],
|
||||
judge={
|
||||
'strategy': 'llm',
|
||||
'models': {'model_id': 'JUDGE_MODEL', 'api_url': 'OPENAI_COMPATIBLE_URL', 'api_key': 'API_KEY'},
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
For an adapter author, judge I/O belongs to `evalscope.api.judge`; do not call `self.llm_judge.judge()` or parse a model reply in the adapter.
|
||||
|
||||
1. Declare `scoring_policy`: use `JUDGE_ONLY` when rule scoring is not meaningful, `JUDGE_DEFAULT` when rules remain available but `auto` should judge, and `RULE_DEFAULT` when `auto` should keep rule scoring.
|
||||
2. Implement the single adapter entry point, `judge_definition(context)`. For an ordinary one-verdict task, return `JudgeDefinition.labels(...)` or `JudgeDefinition.numeric(...)` with a Pydantic verdict schema. These helpers append the JSON output instruction and keep the prompt, schema, and metric mapping together.
|
||||
3. For a rubric, multiple claims, or staged task, define a Pydantic verdict schema and `OutputContract`, then return `JudgeDefinition.workflow(cases=..., request=..., reduce=...)`. Pass `expand=...`, `fallback=...`, or `finalize=...` only when the workflow needs them. The callbacks can be nested in `judge_definition()` or private adapter helpers, but they must be owned by the returned definition rather than exposed as adapter hooks. Append `case.output_contract.instruction()` in a custom request unless the official fixed JSON instruction exactly matches that schema. Use `CaseVerdict.metadata` rather than encoding state into `case_id`.
|
||||
4. When a deterministic rule settles a sample without a model call, return `JudgeDefinition.skip(score, reason='...')`. `reason` is required and is persisted as `Score.metadata['judge_skip_reason']` with `Score.metadata['judge_skipped'] = True`; the web review panel labels this as rule-based scoring rather than an LLM verdict.
|
||||
5. Add a scripted-judge test covering a valid JSON verdict, malformed/prose output, and a transport error. Invalid judge replies are excluded from the metric; they are not converted to a zero score and are not automatically retried by the executor.
|
||||
|
||||
The executor owns request dispatch, position swaps, repeats, multi-judge quorum, aggregation, and review diagnostics. The model transport owns its own retry policy through `generation_config`.
|
||||
|
||||
### Core Data Structures
|
||||
|
||||
#### 1. Sample Object
|
||||
@ -108,38 +133,38 @@ class ModelOutput:
|
||||
Represents the scoring result of a single sample:
|
||||
|
||||
```python
|
||||
@dataclass
|
||||
class Score:
|
||||
value: Dict[str, float] # Scores for each metric {"acc": 1.0, "f1": 0.8}
|
||||
extracted_prediction: str # Extracted prediction answer
|
||||
prediction: str # Raw prediction text
|
||||
metadata: Dict = None # Scoring metadata
|
||||
class Score(BaseModel):
|
||||
value: Dict[str, int | float | bool] = Field(default_factory=dict) # E.g. {"accuracy": 1.0}
|
||||
extracted_prediction: Optional[str] = None
|
||||
prediction: Optional[str] = None
|
||||
explanation: Optional[str] = None
|
||||
metadata: Optional[Dict] = Field(default_factory=dict)
|
||||
main_score_name: Optional[str] = None # Selects one value within this sample only
|
||||
```
|
||||
|
||||
#### 5. SampleScore Object
|
||||
Encapsulates the complete scoring information of a single sample:
|
||||
|
||||
```python
|
||||
@dataclass
|
||||
class SampleScore:
|
||||
score: Score # Scoring object
|
||||
sample_id: Optional[str] # Unique identifier for the sample
|
||||
group_id: Optional[str] # Group identifier
|
||||
sample_metadata: Optional[Dict] = None # Sample metadata
|
||||
class SampleScore(BaseModel):
|
||||
score: Score
|
||||
sample_id: Optional[str | int] = None
|
||||
group_id: Optional[str | int] = None
|
||||
sample_metadata: Optional[Dict] = None
|
||||
```
|
||||
|
||||
#### 6. AggScore Object
|
||||
Represents aggregated scoring statistics:
|
||||
|
||||
```python
|
||||
@dataclass
|
||||
class AggScore:
|
||||
metric: str # Metric name
|
||||
value: float # Aggregated value (e.g., average score)
|
||||
subset: str # Subset name
|
||||
num_samples: int # Number of samples
|
||||
agg_method: str # Aggregation method (mean, median, etc.)
|
||||
metadata: Dict = None # Aggregation metadata
|
||||
class AggScore(BaseModel):
|
||||
score: float = 0.0
|
||||
metric_name: str = '' # Canonical measured concept, e.g. "accuracy"
|
||||
aggregation: str = 'identity'
|
||||
dimensions: Dict[str, str | int | float | bool] = Field(default_factory=dict)
|
||||
num: int = 0
|
||||
ids: Optional[List[str | int]] = None
|
||||
metadata: Optional[Dict] = None
|
||||
```
|
||||
|
||||
#### 7. DatasetDict Object
|
||||
@ -325,7 +350,7 @@ Reasoning:
|
||||
few_shot_num=4, # Few-shot example number
|
||||
train_split='train', # Training set split name
|
||||
eval_split='test', # Evaluation set split name
|
||||
metric_list=['acc'], # Evaluation metrics
|
||||
metric_list=['accuracy'], # Canonical evaluation metrics
|
||||
prompt_template=PROMPT_TEMPLATE, # Prompt template
|
||||
)
|
||||
)
|
||||
@ -400,7 +425,7 @@ SUBSET_LIST = [
|
||||
description='MMLU-Pro is a benchmark for evaluating language models on multiple-choice questions across various subjects.',
|
||||
dataset_id='modelscope/MMLU-Pro',
|
||||
subset_list=SUBSET_LIST,
|
||||
metric_list=['acc'],
|
||||
metric_list=['accuracy'],
|
||||
few_shot_num=5,
|
||||
train_split='validation',
|
||||
eval_split='test',
|
||||
@ -468,6 +493,67 @@ class MMLUProAdapter(MultiChoiceAdapter):
|
||||
- General Text Reasoning: Focuses more on guiding the reasoning process
|
||||
- Multiple Choice: Focuses on displaying choices and answer format
|
||||
|
||||
### Metric Semantics and the Primary Metric
|
||||
|
||||
Reports do not guess what a metric means. How a metric is displayed — its name, its optimization
|
||||
direction, its unit, its scale and its precision — comes from a central catalog at
|
||||
`evalscope/metrics/semantics/catalog.py`, and each benchmark states which of its metrics carries
|
||||
the conclusion.
|
||||
|
||||
**Most new benchmarks need no catalog change at all.** Reusing an existing canonical metric name
|
||||
(`accuracy`, `f1`, `exact_match`, `pass_rate`, ...) means the semantics are already declared:
|
||||
|
||||
```python
|
||||
metric_list=['accuracy'],
|
||||
```
|
||||
|
||||
Two cases are worth a line from you:
|
||||
|
||||
1. **Your benchmark reports several metrics or several variants of one metric.** Declare exactly
|
||||
which emitted identity is primary. A selector may constrain the aggregation and any structured
|
||||
dimensions such as `k`, `scope`, or `threshold`:
|
||||
|
||||
```python
|
||||
from evalscope.api.metric.semantics import MetricSelector
|
||||
|
||||
metric_list=['precision', 'recall', 'f1', 'accuracy'],
|
||||
primary_metric=MetricSelector(name='f1', aggregation='mean'),
|
||||
```
|
||||
|
||||
A single non-diagnostic identity is implicitly primary. If several non-diagnostic identities
|
||||
are emitted, omitting the selector makes report generation fail instead of guessing from list
|
||||
order. A selector must match exactly one emitted identity, and its name must be declared in
|
||||
`metric_list`.
|
||||
|
||||
2. **Your benchmark introduces a new canonical metric name.** Add one line to `METRIC_DEFINITIONS`,
|
||||
referencing the baseline that describes it:
|
||||
|
||||
```python
|
||||
# evalscope/metrics/semantics/catalog.py
|
||||
METRIC_DEFINITIONS['my_new_score'] = MetricEntry(baseline='quality.accuracy.ratio')
|
||||
```
|
||||
|
||||
Keep the naming layers separate:
|
||||
|
||||
- `metric_list`, `Score.value`, and custom `AggScore.metric_name` use canonical names such as
|
||||
`accuracy`. A small set of legacy aliases is normalized for compatibility, but new adapters
|
||||
should not introduce more aliases.
|
||||
- `AggScore` stores `metric_name`, `aggregation`, and `dimensions` separately. Do not encode
|
||||
`mean`, `pass@k`, thresholds, or scopes into the metric name.
|
||||
- The catalog is keyed by the canonical metric name. Aggregation-specific meaning belongs in
|
||||
`AGGREGATION_SEMANTICS`; benchmark-specific name collisions belong in
|
||||
`BENCHMARK_METRIC_OVERRIDES`.
|
||||
- `Score.main_score_name` selects one value in a sample, `BenchmarkMeta.primary_metric` declares the
|
||||
report-level primary identity, and `Report.primary_metric_identity` persists that identity.
|
||||
|
||||
After changing `primary_metric`, refresh its generated metadata cache with
|
||||
`make docs-update BENCHMARK="<name>" FORCE=1`; do not edit `_meta/*.json` by hand.
|
||||
|
||||
An undeclared metric degrades to a diagnostic, which displays the stored value without claiming a
|
||||
direction or unit and logs the catalog entry to add. Dynamic variants do not require catalog
|
||||
enumeration: values such as `k`, question type, threshold, and token range belong in structured
|
||||
dimensions and share the canonical metric's semantics.
|
||||
|
||||
## 4. Running Evaluation
|
||||
|
||||
Debug the code to see if it can run normally.
|
||||
@ -505,11 +591,11 @@ Output Example:
|
||||
+-----------------------+-----------+-----------------+------------------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+=======================+===========+=================+==================+=======+=========+=========+
|
||||
| Qwen2.5-0.5B-Instruct | gsm8k | mean_acc | main | 10 | 0.3 | default |
|
||||
| Qwen2.5-0.5B-Instruct | gsm8k | Accuracy ↑ | main | 10 | 30% | default |
|
||||
+-----------------------+-----------+-----------------+------------------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | mmlu_pro | mean_acc | computer science | 10 | 0.1 | default |
|
||||
| Qwen2.5-0.5B-Instruct | mmlu_pro | Accuracy ↑ | computer science | 10 | 10% | default |
|
||||
+-----------------------+-----------+-----------------+------------------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | mmlu_pro | mean_acc | math | 10 | 0.1 | default |
|
||||
| Qwen2.5-0.5B-Instruct | mmlu_pro | Accuracy ↑ | math | 10 | 10% | default |
|
||||
+-----------------------+-----------+-----------------+------------------+-------+---------+---------+
|
||||
```
|
||||
|
||||
@ -525,8 +611,8 @@ make docs
|
||||
```
|
||||
|
||||
## 6. Submitting PR
|
||||
After completing the implementation of these methods and document generation, your benchmark evaluation is ready! You can submit a [PR](https://github.com/modelscope/evalscope/pulls). Before submitting, please run the following command, which will automatically format the code:
|
||||
After completing the implementation and documentation generation, run all repository checks before submitting a [PR](https://github.com/modelscope/evalscope/pulls). This command applies safe Ruff fixes and formatting before validating the remaining hooks:
|
||||
```bash
|
||||
make lint
|
||||
```
|
||||
Ensure there are no formatting issues, and we will merge your contribution as soon as possible, allowing more users to use the benchmark evaluation you contributed. If you don't know how to submit a PR, you can check our [Guide](https://github.com/modelscope/evalscope/blob/main/CONTRIBUTING.md). Give it a try 🚀
|
||||
Once the checks pass, your contribution is ready for review. For the complete development workflow, see the [Contributing Guide](https://github.com/modelscope/evalscope/blob/main/CONTRIBUTING.md). Give it a try 🚀
|
||||
|
||||
@ -46,7 +46,7 @@ task_cfg = {
|
||||
}
|
||||
```
|
||||
```{seealso}
|
||||
[Full Parameter Explanation](../../user_guides/backend/rageval_backend/clip_benchmark.md#configure-evaluation-parameters)
|
||||
[Full Parameter Reference](../../user_guides/backend/rageval_backend/clip_benchmark.md#full-parameter-reference)
|
||||
```
|
||||
|
||||
Where:
|
||||
|
||||
@ -148,7 +148,7 @@ Each task in the `custom_tasks` list corresponds to a `CustomTaskConfig` with th
|
||||
| `eval_splits` | List[str] | `["test"]` | Evaluation splits list |
|
||||
|
||||
```{note}
|
||||
Other evaluation parameters (such as `models`, `limits`, `overwrite_results`, etc.) are consistent with the default configuration. See [MTEB Evaluation Parameter Reference](../../user_guides/backend/rageval_backend/mteb.md#parameter-explanation) for details.
|
||||
Other evaluation parameters (such as `models`, `limits`, `overwrite_results`, etc.) are consistent with the default configuration. See [MTEB Evaluation Parameter Reference](../../user_guides/backend/rageval_backend/mteb.md#full-parameter-reference) for details.
|
||||
```
|
||||
|
||||
## FAQ
|
||||
|
||||
@ -82,7 +82,7 @@ Results:
|
||||
+---------------------+-------------+-----------------+----------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+=====================+=============+=================+==========+=======+=========+=========+
|
||||
| Qwen2-0.5B-Instruct | general_mcq | AverageAccuracy | example | 12 | 0.5833 | default |
|
||||
| Qwen2-0.5B-Instruct | general_mcq | Accuracy ↑ | example | 12 | 58.3% | default |
|
||||
+---------------------+-------------+-----------------+----------+-------+---------+---------+
|
||||
```
|
||||
|
||||
@ -209,45 +209,51 @@ run_task(task_cfg=task_cfg)
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+================+============+===========+==========+=======+=========+=========+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-1-R | example | 12 | 0.694 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 1 · Recall | example | 12 | 69.4% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-1-P | example | 12 | 0.176 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 1 · Precision | example | 12 | 17.6% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-1-F | example | 12 | 0.2276 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 1 · F1 | example | 12 | 22.8% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-2-R | example | 12 | 0.4667 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 2 · Recall | example | 12 | 46.7% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-2-P | example | 12 | 0.0939 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 2 · Precision | example | 12 | 9.4% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-2-F | example | 12 | 0.1226 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · 2 · F1 | example | 12 | 12.3% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-L-R | example | 12 | 0.6528 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · L · Recall | example | 12 | 65.3% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-L-P | example | 12 | 0.1628 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · L · Precision | example | 12 | 16.3% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | Rouge-L-F | example | 12 | 0.2063 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | ROUGE ↑ · L · F1 | example | 12 | 20.6% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | bleu-1 | example | 12 | 0.164 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | BLEU ↑ · 1 | example | 12 | 16.4% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | bleu-2 | example | 12 | 0.0935 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | BLEU ↑ · 2 | example | 12 | 9.4% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | bleu-3 | example | 12 | 0.065 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | BLEU ↑ · 3 | example | 12 | 6.6% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | bleu-4 | example | 12 | 0.0556 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | BLEU ↑ · 4 | example | 12 | 5.6% | default |
|
||||
+----------------+------------+-----------+----------+-------+---------+---------+
|
||||
```
|
||||
</details>
|
||||
|
||||
**Method 2: Evaluation based on LLM**
|
||||
|
||||
LLM-based evaluation can conveniently assess the correctness of model outputs (or other dimensions of metrics, requiring custom prompt settings). Below is an example configuring `judge_model_args` parameters, using the preset `pattern` mode to determine the correctness of model outputs.
|
||||
LLM-based evaluation can conveniently assess the correctness of model outputs (or other dimensions of metrics, requiring custom prompt settings). Below is an example using the preset `pattern` JSON contract to determine correctness.
|
||||
|
||||
For a complete explanation of judge parameters, please refer to [documentation](../../get_started/parameters.md#judge-parameters).
|
||||
|
||||
```{note}
|
||||
The judge replies with a single JSON object. A reply that cannot be read as one is **excluded** from
|
||||
the metric rather than scored 0, so `Num` may be lower than the sample count. A
|
||||
custom `prompt_template` should state the grading criteria only; the reply format is appended
|
||||
automatically.
|
||||
```
|
||||
|
||||
```python
|
||||
import os
|
||||
from evalscope import TaskConfig, run_task
|
||||
from evalscope.constants import JudgeStrategy
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='Qwen/Qwen2.5-0.5B-Instruct',
|
||||
@ -262,22 +268,18 @@ task_cfg = TaskConfig(
|
||||
],
|
||||
}
|
||||
},
|
||||
# judge related parameters
|
||||
judge_model_args={
|
||||
'model_id': 'qwen2.5-72b-instruct',
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': os.getenv('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {
|
||||
'temperature': 0.0,
|
||||
'max_tokens': 4096
|
||||
judge={
|
||||
'strategy': 'llm',
|
||||
'models': {
|
||||
'model_id': 'qwen2.5-72b-instruct',
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': os.getenv('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {'temperature': 0.0, 'max_tokens': 4096},
|
||||
},
|
||||
# Determine if the model output is correct based on reference answers and model output
|
||||
'score_type': 'pattern',
|
||||
'contract': {'score_type': 'pattern'},
|
||||
},
|
||||
# eval concurrency number
|
||||
eval_batch_size=5,
|
||||
# Use LLM for evaluation
|
||||
judge_strategy=JudgeStrategy.LLM,
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
@ -289,7 +291,7 @@ run_task(task_cfg=task_cfg)
|
||||
+----------------+------------+----------------+----------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+================+============+================+==========+=======+=========+=========+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | AverageAccuracy | example | 12 | 0.583 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | Accuracy ↑ | example | 12 | 58.3% | default |
|
||||
+----------------+------------+----------------+----------+-------+---------+---------+
|
||||
```
|
||||
</details>
|
||||
@ -298,13 +300,12 @@ run_task(task_cfg=task_cfg)
|
||||
|
||||
If the dataset lacks reference answers, an LLM judge can be used to evaluate the model's output answers. Without configuring an LLM, no scoring results will be available.
|
||||
|
||||
Below is an example configuring `judge_model_args` parameters, using the preset `numeric` mode to automatically assess model output scores from dimensions such as accuracy, relevance, and usefulness. Higher scores indicate better model output.
|
||||
Below is an example using the preset `numeric` JSON contract to automatically assess model output scores from dimensions such as accuracy, relevance, and usefulness. Higher scores indicate better model output.
|
||||
|
||||
For a complete explanation of judge parameters, please refer to [documentation](../../get_started/parameters.md#judge-parameters).
|
||||
```python
|
||||
import os
|
||||
from evalscope import TaskConfig, run_task
|
||||
from evalscope.constants import JudgeStrategy
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='Qwen/Qwen2.5-0.5B-Instruct',
|
||||
@ -319,22 +320,18 @@ task_cfg = TaskConfig(
|
||||
],
|
||||
}
|
||||
},
|
||||
# judge related parameters
|
||||
judge_model_args={
|
||||
'model_id': 'qwen2.5-72b-instruct',
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': os.getenv('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {
|
||||
'temperature': 0.0,
|
||||
'max_tokens': 4096
|
||||
judge={
|
||||
'strategy': 'llm',
|
||||
'models': {
|
||||
'model_id': 'qwen2.5-72b-instruct',
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': os.getenv('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {'temperature': 0.0, 'max_tokens': 4096},
|
||||
},
|
||||
# Direct scoring
|
||||
'score_type': 'numeric',
|
||||
'contract': {'score_type': 'numeric'},
|
||||
},
|
||||
# eval concurrency number
|
||||
eval_batch_size=5,
|
||||
# Use LLM for evaluation
|
||||
judge_strategy=JudgeStrategy.LLM,
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
@ -346,7 +343,7 @@ run_task(task_cfg=task_cfg)
|
||||
+----------------+------------+----------------+----------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+================+============+================+==========+=======+=========+=========+
|
||||
| Qwen2.5-0.5B-Instruct | general_qa | AverageAccuracy | example | 12 | 0.6375 | default |
|
||||
| Qwen2.5-0.5B-Instruct | General-QA | Accuracy ↑ | example | 12 | 63.8% | default |
|
||||
+----------------+------------+----------------+----------+-------+---------+---------+
|
||||
```
|
||||
|
||||
@ -495,4 +492,4 @@ Example output:
|
||||
+-----------+------------+-------------------------------+----------+-------+---------+---------+
|
||||
| qwen-plus | general_fc | tool_call_f1 | default | 10 | 0.5 | default |
|
||||
+-----------+------------+-------------------------------+----------+-------+---------+---------+
|
||||
```
|
||||
```
|
||||
|
||||
@ -2,22 +2,29 @@
|
||||
|
||||
This framework supports two custom multimodal evaluation methods:
|
||||
|
||||
- **General-VQA Format**: Based on OpenAI message format, supports multi-image/audio input, system prompts, and base64 encoding, suitable for Q&A-based multimodal evaluation tasks.
|
||||
- **General-VMCQ Format**: Similar to MMMU format, question text can contain image placeholders `<image x>`, suitable for multiple-choice multimodal evaluation tasks.
|
||||
- **General-VQA Format**: Suitable for Q&A-based multimodal evaluation tasks. Supports two input styles: **OpenAI Messages Data**, **MMMU-style Data with Media Placeholders**.
|
||||
- **General-VMCQ Format**: Suitable for multiple-choice multimodal evaluation tasks. Uses the [media placeholders][mp-feature] to embed images, videos, and audio in questions and options, similar to MMMU format.
|
||||
|
||||
## General-VQA Format
|
||||
|
||||
### 1. Data Preparation
|
||||
General-VQA supports **two input styles**:
|
||||
|
||||
Prepare data files conforming to OpenAI message format, supporting **JSONL** or **TSV** formats:
|
||||
1. **OpenAI Messages Data** — full structured content with explicit media parts (images, audio, video) in the OpenAI message schema. Supports multi-turn conversations, system prompts, and fine-grained control over each content part.
|
||||
2. **MMMU-style Data with Media Placeholders** — a simpler approach where the user message is a plain-text string containing `<image N>`, `<video N>`, or `<audio N>` placeholders, and media files are supplied via separate indexed columns (see [Media Placeholder Mechanism][mp-feature]).
|
||||
|
||||
**JSONL Format Example** (`example_openai.jsonl`):
|
||||
Both formats support **JSONL** or **TSV** files.
|
||||
|
||||
### OpenAI Messages Data
|
||||
|
||||
In this format, each record contains a `messages` array following the OpenAI chat completion schema. Media (images, audio, video) are embedded directly as structured content parts within user messages.
|
||||
|
||||
**JSONL Example** (`example_openai.jsonl`):
|
||||
```json
|
||||
{"messages": [{"role": "user", "content": [{"type": "text", "text": "What animal is this?"}, {"type": "image_url", "image_url": {"url": "custom_eval/multimodal/images/dog.jpg"}}]}], "answer": "Dog"}
|
||||
{"messages": [{"role": "user", "content": [{"type": "text", "text": "What building is this?"}, {"type": "image_url", "image_url": {"url": "custom_eval/multimodal/images/AMNH.jpg"}}]}], "answer": "Museum"}
|
||||
```
|
||||
|
||||
**TSV Format Example** (`example_openai.tsv`):
|
||||
**TSV Example** (`example_openai.tsv`):
|
||||
```text
|
||||
messages answer
|
||||
[{"role": "user", "content": [{"type": "text", "text": "What animal is this?"}, {"type": "image_url", "image_url": {"url": "custom_eval/multimodal/images/dog.jpg"}}]}] Dog
|
||||
@ -47,7 +54,7 @@ messages answer
|
||||
- Local path: `"url": "custom_eval/multimodal/videos/sample.mp4"`
|
||||
- HTTP URL: `"url": "https://example.com/video.mp4"` (requires model service support)
|
||||
- Base64 encoding: `"url": "data:video/mp4;base64,AAAAIGZ0eX..."`
|
||||
- Video format is inferred from the path, URL, or data URI; supported formats are `"mp4"`, `"mpeg"`, and `"mov"`.
|
||||
- Video format is inferred from the path, URL, or data URI; supported formats are `"mp4"`, `"mpeg"`, `"mov"`, and `"avi"`.
|
||||
|
||||
**Multi-image Input**
|
||||
|
||||
@ -187,6 +194,31 @@ Supports video content input using OpenAI-compatible `video_url` format. The `ur
|
||||
}
|
||||
```
|
||||
|
||||
### MMMU-style Data with Media Placeholders
|
||||
|
||||
In this format, the `messages` field keeps the user message as a **plain-text string** containing placeholders like `<image 1>`, `<video 1>`, or `<audio 1>` and filled in-place via separate indexed columns (`image_1`, `video_1`, `audio_1`, etc.). For each media type, use either indexed columns or its plural list column, not both. See the [Media Placeholder Mechanism][mp-feature] section below for full details on how placeholders are resolved, supported column names, and media types.
|
||||
|
||||
**JSONL Example** (`example_placeholder.jsonl`):
|
||||
```json
|
||||
{"messages": [{"role": "user", "content": "What animal is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/dog.jpg", "answer": "Dog"}
|
||||
{"messages": [{"role": "user", "content": "What building is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/AMNH.jpg", "answer": "Museum"}
|
||||
{"messages": [{"role": "user", "content": "Which city's skyline is this?<image 1>"}], "image_1": "custom_eval/multimodal/images/tokyo.jpg", "answer": "Tokyo"}
|
||||
{"messages": [{"role": "user", "content": "What is the brand of this car?<image 1>"}], "image_1": "custom_eval/multimodal/images/tesla.jpg", "answer": "Tesla"}
|
||||
{"messages": [{"role": "user", "content": "What is the person in the picture doing?<image 1>"}], "image_1": "custom_eval/multimodal/images/running.jpg", "answer": "Running"}
|
||||
```
|
||||
|
||||
**Mixed Media Example**:
|
||||
```json
|
||||
{"messages": [{"role": "user",
|
||||
"content": "<image 1> Watch <video 1> and describe both."}],
|
||||
"answer": "A sunny beach and a wave video.",
|
||||
"image_1": "custom_eval/multimodal/images/beach.jpg",
|
||||
"video_1": "custom_eval/multimodal/videos/wave.mp4"}
|
||||
```
|
||||
|
||||
**Note**: Only user messages (`"role": "user"`) with plain-text `content` are scanned for placeholders. Messages that already have structured content (a list of content parts) or messages with other roles (system, assistant, tool) are left untouched.
|
||||
|
||||
|
||||
### 2. Configure Evaluation Task
|
||||
|
||||
Evaluate using Python API or CLI:
|
||||
@ -232,31 +264,31 @@ Evaluation will output BLEU and Rouge metrics:
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+==============+=============+================+================+=======+=========+=========+
|
||||
| qwen-vl-plus | general_vqa | mean_bleu-1 | example_openai | 5 | 0.0067 | default |
|
||||
| qwen-vl-plus | General-VQA | BLEU ↑ · 1 | example_openai | 5 | 0.7% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_bleu-2 | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | BLEU ↑ · 2 | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_bleu-3 | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | BLEU ↑ · 3 | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_bleu-4 | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | BLEU ↑ · 4 | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-1-R | example_openai | 5 | 0.4 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 1 · Recall | example_openai | 5 | 40% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-1-P | example_openai | 5 | 0.0062 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 1 · Precision | example_openai | 5 | 0.6% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-1-F | example_openai | 5 | 0.0121 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 1 · F1 | example_openai | 5 | 1.2% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-2-R | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 2 · Recall | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-2-P | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 2 · Precision | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-2-F | example_openai | 5 | 0 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · 2 · F1 | example_openai | 5 | 0% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-L-R | example_openai | 5 | 0.4 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · L · Recall | example_openai | 5 | 40% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-L-P | example_openai | 5 | 0.0047 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · L · Precision | example_openai | 5 | 0.5% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
| qwen-vl-plus | general_vqa | mean_Rouge-L-F | example_openai | 5 | 0.0093 | default |
|
||||
| qwen-vl-plus | General-VQA | ROUGE ↑ · L · F1 | example_openai | 5 | 0.9% | default |
|
||||
+--------------+-------------+----------------+----------------+-------+---------+---------+
|
||||
```
|
||||
|
||||
@ -266,7 +298,7 @@ You can specify a judge model through the `judge_model` parameter to generate re
|
||||
|
||||
```python
|
||||
from evalscope.run import run_task
|
||||
from evalscope.constants import EvalType, JudgeStrategy
|
||||
from evalscope.constants import EvalType
|
||||
from os import environ as env
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
@ -282,17 +314,16 @@ task_cfg = TaskConfig(
|
||||
}
|
||||
},
|
||||
limit=5,
|
||||
judge_model_args={
|
||||
'model_id': 'qwen-plus', # Does not need to be a multimodal model
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': env.get('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {
|
||||
'temperature': 0.0,
|
||||
'max_tokens': 4096
|
||||
judge={
|
||||
'strategy': 'llm',
|
||||
'models': {
|
||||
'model_id': 'qwen-plus', # Does not need to be a multimodal model
|
||||
'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
|
||||
'api_key': env.get('DASHSCOPE_API_KEY'),
|
||||
'generation_config': {'temperature': 0.0, 'max_tokens': 4096},
|
||||
},
|
||||
},
|
||||
eval_batch_size=5,
|
||||
judge_strategy=JudgeStrategy.LLM,
|
||||
)
|
||||
result = run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -307,9 +338,8 @@ evalscope eval \
|
||||
--datasets general_vqa \
|
||||
--dataset-args '{"general_vqa": {"local_path": "custom_eval/multimodal/vqa", "subset_list": ["example_openai"]}}' \
|
||||
--limit 5 \
|
||||
--judge-model-args '{"model_id": "qwen-plus", "api_url": "https://dashscope.aliyuncs.com/compatible-mode/v1", "api_key": "$DASHSCOPE_API_KEY", "generation_config": {"temperature": 0.0, "max_tokens": 4096}}' \
|
||||
--judge-worker-num 5 \
|
||||
--judge-strategy llm
|
||||
--eval-batch-size 5 \
|
||||
--judge '{"strategy": "llm", "models": {"model_id": "qwen-plus", "api_url": "https://dashscope.aliyuncs.com/compatible-mode/v1", "api_key": "$DASHSCOPE_API_KEY", "generation_config": {"temperature": 0.0, "max_tokens": 4096}}}'
|
||||
```
|
||||
|
||||
Evaluation will output accuracy metrics:
|
||||
@ -317,7 +347,7 @@ Evaluation will output accuracy metrics:
|
||||
+--------------+-------------+----------+----------------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+==============+=============+==========+================+=======+=========+=========+
|
||||
| qwen-vl-plus | general_vqa | mean_acc | example_openai | 5 | 1 | default |
|
||||
| qwen-vl-plus | general_vqa | Accuracy ↑ | example_openai | 5 | 100% | default |
|
||||
+--------------+-------------+----------+----------------+-------+---------+---------+
|
||||
```
|
||||
|
||||
@ -325,15 +355,7 @@ Evaluation will output accuracy metrics:
|
||||
|
||||
### 1. Data Preparation
|
||||
|
||||
General-VMCQ adopts a structure similar to MMMU: question text can contain image placeholders `<image x>` and video placeholders `<video x>`; `options` is a Python list string, options can be text or media placeholders.
|
||||
|
||||
Media support the following forms (all strings):
|
||||
- Image local or remote path/URL: `"custom_eval/multimodal/images/dog.jpg"` or `"https://.../dog.jpg"`
|
||||
- Image Base64 Data URL: `"data:image/jpeg;base64,/9j/4AAQSk..."`
|
||||
- Video local or remote path/URL: `"custom_eval/multimodal/videos/sample.mp4"` or `"https://.../sample.mp4"`
|
||||
- Video Base64 Data URL: `"data:video/mp4;base64,AAAAIGZ0eX..."`
|
||||
|
||||
Supports up to 100 images (`image_1` to `image_100`) and 100 videos (`video_1` to `video_100`). Missing media placeholders are ignored.
|
||||
General-VMCQ adopts a structure similar to MMMU: question text can contain image placeholders `<image x>`, video placeholders `<video x>`, and audio placeholders `<audio x>`; `options` is a Python list string, options can be text or media placeholders. Media files are supplied via media columns (`image_k`, `images`, `video_k`, `audio_k`, etc.) described in the [Media Placeholder Mechanism][mp-feature] section.
|
||||
|
||||
**JSONL Example** (`example.jsonl`):
|
||||
```json
|
||||
@ -350,12 +372,10 @@ Which image shows a dog? ["<image 1>", "<image 2>", "<image 3>", "<image 4>"] A
|
||||
```
|
||||
|
||||
**Field Descriptions**:
|
||||
- `question`: Question text, can contain `<image x>` or `<video x>` placeholders
|
||||
- `options`: List (JSON array), elements can be text (e.g., `"School"`) or media placeholders (e.g., `"<image 1>"`, `"<video 1>"`), no need to add prefixes like `A.`, `B.`
|
||||
- `question`: Question text, can contain `<image x>`, `<video x>`, or `<audio x>` placeholders
|
||||
- `options`: List (JSON array), elements can be text (e.g., `"School"`) or media placeholders (e.g., `"<image 1>"`, `"<video 1>"`, `"<audio 1>"`), no need to add prefixes like `A.`, `B.`
|
||||
- `answer`: Correct answer letter (e.g., `"A"`, `"B"`)
|
||||
- `image_k`: Image string (local/remote path or base64 Data URL), k ∈ [1, 100]
|
||||
- `video_k`: Video string (local/remote path or base64 Data URL), k ∈ [1, 100]
|
||||
- `video_k_format`: Optional video format hint; supports `"mp4"`, `"mpeg"`, and `"mov"`
|
||||
- Media columns (`image_k`, `images`, `video_k`, `videos`, `video_k_format`, `audio_k`, `audios`, `audio_k_format`): See the [Media Placeholder Mechanism][mp-feature] section for full details.
|
||||
|
||||
### 2. Configure Evaluation Task
|
||||
|
||||
@ -403,10 +423,68 @@ Evaluation will output accuracy metrics:
|
||||
+--------------+--------------+----------+----------+-------+---------+---------+
|
||||
| Model | Dataset | Metric | Subset | Num | Score | Cat.0 |
|
||||
+==============+==============+==========+==========+=======+=========+=========+
|
||||
| qwen-vl-plus | general_vmcq | mean_acc | example | 3 | 1 | default |
|
||||
| qwen-vl-plus | general_vmcq | Accuracy ↑ | example | 3 | 100% | default |
|
||||
+--------------+--------------+----------+----------+-------+---------+---------+
|
||||
```
|
||||
|
||||
## Media Placeholder Mechanism
|
||||
[mp-feature]: #media-placeholder-mechanism
|
||||
|
||||
General-VQA and General-VMCQ share media normalization utilities, but differ in when they validate media columns.
|
||||
|
||||
### How It Works
|
||||
|
||||
Placeholders like `<image 1>`, `<video 1>`, or `<audio 1>` in plain text are replaced with the corresponding media before prompting to an MLLM.
|
||||
|
||||
- **General-VQA** resolves only media referenced by plain-text user messages. Missing referenced media is dropped with a warning; if that would leave a user message empty, its original text is retained. Unreferenced media columns are ignored.
|
||||
- **General-VMCQ** validates every non-empty media column before building its prompt. Unused malformed media columns therefore cause the record to fail.
|
||||
- By default, indexed media columns are capped at 100: `image_k`/`video_k`/`audio_k` for k ∈ [1, 100], e.g., `<image 101>` and `image_101` will be ignored.
|
||||
- For each media type, choose either indexed columns or its plural list column. Do not mix the two representations: General-VQA ignores the list when any referenced indexed column is non-empty, while General-VMCQ ignores it when any indexed column is non-empty. List columns are equivalent to `image_1`, `image_2`, ... and are not capped at 100.
|
||||
- General-VQA converts resolved placeholder content into structured OpenAI-message content. General-VMCQ inserts it into its multiple-choice prompt.
|
||||
|
||||
### Trigger Conditions
|
||||
|
||||
- **General-VQA**: every message that satisfies both conditions: 1. its `"role"` is `"user"`, and 2. its `"content"` field is a plain string (type `str`).
|
||||
- **General-VMCQ**: `question` and `options` field, always triggered.
|
||||
|
||||
To bypass it, you can provide structured content for General-VQA messages, or remove placeholders in General-VMCQ questions/options. A General-VQA example is provided below:
|
||||
|
||||
```json
|
||||
// <image 1> tag will not be replaced, because it's structured into `{"type": "text"}` dict
|
||||
{"answer": "Dog",
|
||||
"messages": [{"role": "user",
|
||||
"content": [{"type": "text",
|
||||
"text": "<image 1> What animal is this?"}]}]}
|
||||
```
|
||||
|
||||
### Media Column Names
|
||||
|
||||
| Column | Description | k range |
|
||||
| ---------------- | -------------------------------------------------------------------------------------------------------- | --------- |
|
||||
| `image_k` | Image path/URL/base64 for placeholder `<image k>` | [1, 100] |
|
||||
| `video_k` | Video path/URL/base64 for placeholder `<video k>` | [1, 100] |
|
||||
| `video_k_format` | Optional video format hint (`"mp4"`, `"mpeg"`, `"mov"`, `"avi"`), automatically guessed if not specified | [1, 100] |
|
||||
| `audio_k` | Audio path/URL/base64 for placeholder `<audio k>` | [1, 100] |
|
||||
| `audio_k_format` | Optional audio format hint (`"wav"`, `"mp3"`), automatically guessed if not specified | [1, 100] |
|
||||
| `images` | Image list equivalent to consecutive `image_1`, `image_2`, ... Do not mix with indexed image columns. | unbounded |
|
||||
| `videos` | Video list equivalent to consecutive `video_1`, `video_2`, ... Do not mix with indexed video columns. | unbounded |
|
||||
| `audios` | Audio list equivalent to consecutive `audio_1`, `audio_2`, ... Do not mix with indexed audio columns. | unbounded |
|
||||
|
||||
### Supported Media Values
|
||||
|
||||
Each media column accepts any of the following:
|
||||
|
||||
- **Local path**: `"custom_eval/multimodal/audio/sample.wav"`
|
||||
- **HTTP/HTTPS URL**: `"https://.../sample.wav"`
|
||||
- **Base64 Data URL**: `"data:audio/wav;base64,UklGRiQ..."`
|
||||
- **Undecoded dict** (for parquet-loaded datasets): `{"path": "..."}` or `{"bytes": b"..."}`
|
||||
- **Hugging Face Dataset features** (for parquet-loaded datasets): [Image][HFImage], [Video][HFVideo], or [Audio][HFAudio] feature objects
|
||||
|
||||
[HFImage]: https://huggingface.co/docs/datasets/about_dataset_features#image-feature
|
||||
[HFVideo]: https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Video
|
||||
[HFAudio]: https://huggingface.co/docs/datasets/en/about_dataset_features#audio-feature
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Based on VLMEvalKit (Deprecated)
|
||||
|
||||
@ -4,9 +4,10 @@ EvalScope uses [ms_enclave](https://github.com/modelscope/ms-enclave) to run
|
||||
model-generated code inside isolated sandboxes. Two execution paths share
|
||||
the same service layer:
|
||||
|
||||
* **Pooled** — a warm pool of long-lived sandboxes used by code benchmarks
|
||||
(e.g. HumanEval, MBPP) through the `SandboxMixin`.
|
||||
* **Per-sample** — one sandbox per sample created by agent environments
|
||||
* **Code execution pool** — a warm pool of long-lived sandboxes used by code
|
||||
benchmarks (e.g. HumanEval, MBPP) through the
|
||||
`CodeExecutionSandboxMixin`.
|
||||
* **Per-sample** — one sandbox per sample created by Agent environments
|
||||
(e.g. `EnclaveAgentEnvironment`) for SWE-bench-style benchmarks.
|
||||
|
||||
Both paths are backed by the process-wide `SandboxService` defined in
|
||||
@ -84,17 +85,18 @@ class MyBenchmarkAdapter(DefaultDataAdapter):
|
||||
```
|
||||
|
||||
The returned dict is merged on top of `sandbox.default_config` and passed
|
||||
to the environment constructor. `agent_config.environment_extra` still
|
||||
to the environment constructor. `agent_config.environment_extra` still
|
||||
has the final word if the user wants to override per-run.
|
||||
|
||||
## Pool vs per-sample
|
||||
|
||||
| Aspect | Pool (SandboxMixin) | Per-sample (Agent env) |
|
||||
| Aspect | Code execution pool | Per-sample Agent environment |
|
||||
|------------------|------------------------------------|-------------------------------|
|
||||
| Owner | `CodeExecutionSandboxMixin` | `EnclaveAgentEnvironment` |
|
||||
| Lifetime | Reused across samples | Fresh container per sample |
|
||||
| Warmup | `manager.initialize_pool` | None |
|
||||
| Execution API | `PoolHandle.execute_tool` | `SandboxHandle.execute_tool` |
|
||||
| Typical use | Code benchmarks | SWE-bench, Agent tool use |
|
||||
| Typical use | Code benchmark scoring | SWE-bench, agent tool use |
|
||||
|
||||
Managers are shared across both paths when `(engine, manager_config)`
|
||||
match, so you only pay for one connection even if a benchmark uses both.
|
||||
|
||||
@ -36,7 +36,7 @@ A-OKVQA (Augmented OK-VQA) is a benchmark designed to evaluate commonsense reaso
|
||||
| **Dataset ID** | [HuggingFaceM4/A-OKVQA](https://modelscope.cn/datasets/HuggingFaceM4/A-OKVQA/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiModal` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `validation` |
|
||||
|
||||
@ -140,5 +140,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ AA-LCR (Artificial Analysis Long Context Retrieval) is a benchmark for evaluatin
|
||||
| **Dataset ID** | [evalscope/AA-LCR](https://modelscope.cn/datasets/evalscope/AA-LCR/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `LongContext`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -136,5 +136,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -3,24 +3,40 @@
|
||||
|
||||
## Overview
|
||||
|
||||
ACEBench is a tool-use benchmark for evaluating whether large language models can select APIs, fill
|
||||
arguments, handle abnormal requests, and complete realistic agent tasks.
|
||||
ACEBench evaluates whether large language models can use tools in realistic settings: picking the
|
||||
right API, filling its arguments, pushing back on requests that cannot be satisfied, and driving
|
||||
multi-step agent tasks against a simulated environment. Data is split into three families -
|
||||
`normal` (ordinary tool use), `special` (incomplete, incorrect or out-of-scope requests) and
|
||||
`agent` (multi-step and multi-turn interaction) - reported over 17 fine-grained categories.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Function calling and agentic tool use
|
||||
- **Input**: Conversation history, API specifications, optional time/profile context, and agent task context
|
||||
- **Output**: Function calls or diagnostic text for special cases
|
||||
- **Subsets**: normal, special, and agent
|
||||
- **Input**: Conversation history, API specifications, and optional time or character-profile context
|
||||
- **Output**: A `[ApiName(key='value')]` call list, a diagnostic sentence, or a full agent trajectory
|
||||
- **Domain**: 8 domains and 68 sub-domains including technology, finance, health and society
|
||||
|
||||
## Key Features
|
||||
|
||||
- 1023 English and 1017 Chinese samples, selectable through `extra_params.language`.
|
||||
- Uses the official ACEBench prompts and the official `[ApiName(...)]` output contract, so an
|
||||
output that cannot be decoded scores zero instead of being rescued by lenient parsing.
|
||||
- `normal_multi_turn_*` categories are scored per dialogue: every step must be correct for the
|
||||
dialogue to count, matching the official turn-level aggregation.
|
||||
- `agent` categories run a real rollout against ACEBench's simulated phone, food-delivery and
|
||||
travel APIs, and are graded on the resulting environment state.
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- The adapter passes ACEBench API specifications as EvalScope tools and also includes concise text
|
||||
instructions for text-only models.
|
||||
- Normal samples are scored by matching function names and arguments.
|
||||
- Special samples are scored against ACEBench's diagnostic text contract.
|
||||
- Agent samples report `process_acc` against ACEBench milestones. If a model returns a final-state JSON object,
|
||||
`end_state_acc` is also reported and used as `acc`; otherwise `acc` follows `process_acc`.
|
||||
- `accuracy` is the primary metric. For `normal` and `special` it is answer accuracy; for `agent` it is
|
||||
end-state accuracy. `process_acc` additionally reports milestone progress for `agent` samples and
|
||||
per-step progress for `normal_multi_turn_*` samples.
|
||||
- The report adds the official groupings (ATOM, SINGLE_TURN, MULTI_TURN, NORMAL, SPECIAL, AGENT)
|
||||
and an OVERALL score weighted `normal` 0.578 / `special` 0.2676 / `agent` 0.1545. Weights are
|
||||
renormalized over the groups actually evaluated, so a partial run stays interpretable.
|
||||
- `agent_multi_turn` additionally needs a user simulator; set `extra_params.user_model` to the model
|
||||
that should play the user (the official runner uses `gpt-4o`). Without it those rollouts fail and
|
||||
score zero, so configure it before reading an OVERALL number.
|
||||
|
||||
|
||||
## Properties
|
||||
@ -31,7 +47,7 @@ arguments, handle abnormal requests, and complete realistic agent tasks.
|
||||
| **Dataset ID** | [evalscope/acebench](https://modelscope.cn/datasets/evalscope/acebench/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Agent`, `FunctionCalling`, `MultiTurn` |
|
||||
| **Metrics** | `acc`, `process_acc`, `end_state_acc` |
|
||||
| **Metrics** | `accuracy`, `process_acc` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `normal` |
|
||||
|
||||
@ -41,196 +57,56 @@ arguments, handle abnormal requests, and complete realistic agent tasks.
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 1,023 |
|
||||
| Prompt Length (Mean) | 4676.74 chars |
|
||||
| Prompt Length (Min/Max) | 1007 / 10555 chars |
|
||||
| Prompt Length (Mean) | 6032.98 chars |
|
||||
| Prompt Length (Min/Max) | 2295 / 11835 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `normal` | 823 | 4859.68 | 1070 | 10555 |
|
||||
| `special` | 150 | 3449.69 | 1007 | 8692 |
|
||||
| `agent` | 50 | 5346.72 | 4454 | 5656 |
|
||||
| `normal_single_turn_single_function` | 100 | 5165.79 | 2461 | 9553 |
|
||||
| `normal_single_turn_parallel_function` | 100 | 5036.21 | 2295 | 9644 |
|
||||
| `normal_multi_turn_user_adjust` | 123 | 4658.51 | 3172 | 6976 |
|
||||
| `normal_multi_turn_user_switch` | 100 | 7546.46 | 3467 | 11835 |
|
||||
| `normal_similar_api` | 50 | 3511.84 | 2484 | 6209 |
|
||||
| `normal_preference` | 50 | 8637.66 | 7107 | 10381 |
|
||||
| `normal_atom_bool` | 50 | 7377.62 | 4762 | 9727 |
|
||||
| `normal_atom_enum` | 50 | 7676.94 | 4927 | 11337 |
|
||||
| `normal_atom_number` | 50 | 7481.46 | 4851 | 10278 |
|
||||
| `normal_atom_list` | 50 | 7524.06 | 4910 | 10514 |
|
||||
| `normal_atom_object_deep` | 50 | 6102.02 | 2873 | 9755 |
|
||||
| `normal_atom_object_short` | 50 | 5139.5 | 2343 | 8921 |
|
||||
| `special_incomplete` | 50 | 6177.34 | 3473 | 10806 |
|
||||
| `special_error_param` | 50 | 4499.78 | 3121 | 6090 |
|
||||
| `special_irrelevant` | 50 | 6011.94 | 3778 | 8492 |
|
||||
| `agent_multi_step` | 20 | 6407.9 | 6343 | 6472 |
|
||||
| `agent_multi_turn` | 30 | 6290.97 | 5505 | 6630 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `normal`
|
||||
**Subset**: `normal_single_turn_single_function`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "134dd42a",
|
||||
"content": "You are evaluating ACEBench tool-use tasks.\n\nUse the available tool schemas when native function calling is supported.\n\nFor text-only output, return API calls as [ApiName(key1='value1', key2=2)]. Return only the call list and no extra explana ... [TRUNCATED 2553 chars] ... \"}, \"effects\": {\"description\": \"List of audio effects to apply.\", \"type\": \"array\", \"items\": {\"type\": \"string\", \"enum\": [\"reverb\", \"echo\", \"distortion\"]}}}, \"required\": [\"frequency\", \"gain\"]}}}, \"required\": [\"microphone\", \"performanceTime\"]}}]"
|
||||
"id": "9198db95",
|
||||
"content": "You are an AI assistant with the role name \"assistant.\" Based on the provided API specifications and conversation history from steps 1 to t, generate the API requests that the assistant should call in step t+1. The API requests should be outp ... [TRUNCATED 3788 chars] ... '}, 'effects': {'description': 'List of audio effects to apply.', 'type': 'array', 'items': {'type': 'string', 'enum': ['reverb', 'echo', 'distortion']}}}, 'required': ['frequency', 'gain']}}}, 'required': ['microphone', 'performanceTime']}}]"
|
||||
},
|
||||
{
|
||||
"id": "da9681d9",
|
||||
"content": "I have been fascinated recently with total solar eclipses. I am planning my next travel and would like to know when the next total solar eclipse will be visible in Greece, specifically in Athens, over the next five years.",
|
||||
"role": "user"
|
||||
"id": "61cfd720",
|
||||
"content": "Conversation history 1..t:\nuser: I have been fascinated recently with total solar eclipses. I am planning my next travel and would like to know when the next total solar eclipse will be visible in Greece, specifically in Athens, over the next five years.\n"
|
||||
}
|
||||
],
|
||||
"target": "{\"ground_truth\": {\"NightSkyAnalysis_performEclipseAnalysis\": {\"dateRange\": {\"startDate\": \"2023-01-01\", \"endDate\": \"2028-01-01\"}, \"location\": {\"latitude\": 37.9838, \"longitude\": 23.7275}, \"eclipseType\": \"total\"}}, \"mile_stone\": []}",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"tools": [
|
||||
{
|
||||
"name": "NightSkyAnalysis_performEclipseAnalysis",
|
||||
"description": "Analyzes the occurrence of solar eclipses, categorizes them into types, and predicts future occurrences based on historical data and celestial mechanics.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"dateRange": {
|
||||
"type": "object",
|
||||
"description": "The range of dates for which to analyze solar eclipses.",
|
||||
"properties": {
|
||||
"startDate": {
|
||||
"type": "string",
|
||||
"description": "The starting date for the analysis in YYYY-MM-DD format."
|
||||
},
|
||||
"endDate": {
|
||||
"type": "string",
|
||||
"description": "The ending date for the analysis in YYYY-MM-DD format."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"startDate",
|
||||
"endDate"
|
||||
]
|
||||
},
|
||||
"location": {
|
||||
"type": "object",
|
||||
"description": "Geographical coordinates to focus the eclipse analysis.",
|
||||
"properties": {
|
||||
"latitude": {
|
||||
"type": "number",
|
||||
"description": "Latitude of the location."
|
||||
},
|
||||
"longitude": {
|
||||
"type": "number",
|
||||
"description": "Longitude of the location."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"latitude",
|
||||
"longitude"
|
||||
]
|
||||
},
|
||||
"eclipseType": {
|
||||
"type": "string",
|
||||
"description": "The type of solar eclipse to specifically analyze.",
|
||||
"enum": [
|
||||
"total",
|
||||
"annular",
|
||||
"partial"
|
||||
]
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"dateRange",
|
||||
"location"
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"name": "AudioPerformanceOptimizer_optimizeMicrophoneSettings",
|
||||
"description": "Optimizes microphone settings for live performances, focusing on dynamic microphones to enhance sound quality and reduce feedback.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"microphone": {
|
||||
"type": "object",
|
||||
"description": "Details of the microphone used.",
|
||||
"properties": {
|
||||
"type": {
|
||||
"type": "string",
|
||||
"description": "Type of the microphone.",
|
||||
"enum": [
|
||||
"dynamic",
|
||||
"condenser",
|
||||
"ribbon"
|
||||
]
|
||||
},
|
||||
"model": {
|
||||
"type": "string",
|
||||
"description": "Model of the microphone."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"type",
|
||||
"model"
|
||||
]
|
||||
},
|
||||
"performanceTime": {
|
||||
"type": "string",
|
||||
"description": "Scheduled time for the performance.",
|
||||
"enum": [
|
||||
"morning",
|
||||
"afternoon",
|
||||
"evening",
|
||||
"night"
|
||||
]
|
||||
},
|
||||
"environment": {
|
||||
"type": "object",
|
||||
"description": "Environmental conditions of the performance area.",
|
||||
"properties": {
|
||||
"humidity": {
|
||||
"type": "integer",
|
||||
"description": "Humidity level as a percentage."
|
||||
},
|
||||
"temperature": {
|
||||
"type": "integer",
|
||||
"description": "Temperature in Celsius."
|
||||
}
|
||||
}
|
||||
},
|
||||
"soundSettings": {
|
||||
"type": "array",
|
||||
"description": "Specific sound settings to apply.",
|
||||
"items": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"frequency": {
|
||||
"type": "integer",
|
||||
"description": "Frequency adjustments in Hz."
|
||||
},
|
||||
"gain": {
|
||||
"type": "integer",
|
||||
"description": "Gain adjustments in dB."
|
||||
},
|
||||
"effects": {
|
||||
"type": "array",
|
||||
"description": "List of audio effects to apply.",
|
||||
"items": {
|
||||
"type": "string",
|
||||
"enum": [
|
||||
"reverb",
|
||||
"echo",
|
||||
"distortion"
|
||||
]
|
||||
}
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"frequency",
|
||||
"gain"
|
||||
]
|
||||
}
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"microphone",
|
||||
"performanceTime"
|
||||
]
|
||||
}
|
||||
}
|
||||
],
|
||||
"subset_key": "normal_single_turn_single_function",
|
||||
"metadata": {
|
||||
"id": "normal_single_turn_single_function_0",
|
||||
"sub_category": "data_normal_single_turn_single_function",
|
||||
"question": "user: I have been fascinated recently with total solar eclipses. I am planning my next travel and would like to know when the next total solar eclipse will be visible in Greece, specifically in Athens, over the next five years.\n",
|
||||
"time": "",
|
||||
"profile": "",
|
||||
"test_category": "normal_single_turn_single_function",
|
||||
"dialogue_id": "normal_single_turn_single_function_0",
|
||||
"language": "en",
|
||||
"functions": [
|
||||
{
|
||||
"name": "NightSkyAnalysis_performEclipseAnalysis",
|
||||
@ -405,15 +281,30 @@ arguments, handle abnormal requests, and complete realistic agent tasks.
|
||||
},
|
||||
"mile_stone": [],
|
||||
"initial_config": {},
|
||||
"involved_classes": []
|
||||
"involved_classes": [],
|
||||
"question": "user: I have been fascinated recently with total solar eclipses. I am planning my next travel and would like to know when the next total solar eclipse will be visible in Greece, specifically in Athens, over the next five years.\n",
|
||||
"time": "The current time is January 01, 2023, Sunday",
|
||||
"profile": ""
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
*Note: Some content was truncated for display.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
*No prompt template defined.*
|
||||
|
||||
## Extra Parameters
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `language` | `str` | `en` | Dataset language to evaluate, either `en` or `zh`. |
|
||||
| `user_model` | `str` | `` | Model that plays the user in `agent_multi_turn` rollouts, e.g. `gpt-4o`. Those rollouts fail and score zero when unset. |
|
||||
| `user_model_api_url` | `str` | `` | Base URL for `user_model`. Defaults to `MODELSCOPE_API_BASE`. |
|
||||
| `user_model_api_key` | `str` | `` | API key for `user_model`. Defaults to `MODELSCOPE_SDK_TOKEN`. |
|
||||
| `max_dialog_turns` | `int` | `40` | Maximum number of agent rollout steps. |
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
@ -440,7 +331,8 @@ task_cfg = TaskConfig(
|
||||
datasets=['acebench'],
|
||||
dataset_args={
|
||||
'acebench': {
|
||||
# subset_list: ['normal', 'special', 'agent'] # optional, evaluate specific subsets
|
||||
# subset_list: ['normal_single_turn_single_function', 'normal_single_turn_parallel_function', 'normal_multi_turn_user_adjust'] # optional, evaluate specific subsets
|
||||
# extra_params: {} # uses default extra parameters
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
@ -448,5 +340,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
153
evalscope/docs/en/benchmarks/agieval.md
Normal file
153
evalscope/docs/en/benchmarks/agieval.md
Normal file
@ -0,0 +1,153 @@
|
||||
# AGIEval
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
AGIEval is a human-centric benchmark designed to evaluate foundation models in the context of human cognition and problem-solving. It uses official, standard, and authoritative admission and qualification exams intended for general human test-takers, such as college entrance exams (GaoKao), law school admission tests (LSAT), math competitions, and lawyer qualification exams.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Mixed (Multiple-Choice QA + Open-ended Math)
|
||||
- **Input**: Questions from standardized exams with optional passages and answer choices
|
||||
- **Output**: Answer letter(s) for MCQ, or numerical/mathematical answer for open-ended
|
||||
- **Languages**: English and Chinese
|
||||
|
||||
## Key Features
|
||||
|
||||
- 21 subsets covering diverse exam types across two languages
|
||||
- English MCQ: LSAT (AR/LR/RC), SAT (Math/English), AQuA-RAT, LogiQA, GaoKao-English
|
||||
- Chinese MCQ: GaoKao (Chinese/Geography/History/Biology/Chemistry/Physics/MathQA), LogiQA-zh, JEC-QA
|
||||
- Open-ended math: MATH (English), GaoKao-MathCloze (Chinese)
|
||||
- Multi-select subsets: JEC-QA-KD, JEC-QA-CA, GaoKao-Physics
|
||||
- Includes passage-based reading comprehension questions
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- MCQ subsets use evalscope's standard MultiChoice template and extraction
|
||||
- Multi-select subsets use Chinese multi-answer template
|
||||
- Math/cloze subsets use mathematical equivalence checking
|
||||
- CoT (Chain-of-Thought) prompting enabled by default
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `agieval` |
|
||||
| **Dataset ID** | [opencompass/agieval](https://modelscope.cn/datasets/opencompass/agieval/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `Math`, `Reasoning` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `dev` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 8,269 |
|
||||
| Prompt Length (Mean) | 673.58 chars |
|
||||
| Prompt Length (Min/Max) | 40 / 5316 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `aqua-rat` | 254 | 290.09 | 103 | 587 |
|
||||
| `logiqa-en` | 651 | 911.89 | 248 | 1769 |
|
||||
| `lsat-ar` | 230 | 946.36 | 635 | 1853 |
|
||||
| `lsat-lr` | 510 | 1156.66 | 563 | 2348 |
|
||||
| `lsat-rc` | 269 | 3652.86 | 2959 | 4825 |
|
||||
| `sat-math` | 220 | 392.45 | 120 | 1201 |
|
||||
| `sat-en` | 206 | 4618.28 | 3569 | 5316 |
|
||||
| `sat-en-without-passage` | 206 | 435.91 | 169 | 937 |
|
||||
| `gaokao-english` | 306 | 2025.44 | 517 | 4216 |
|
||||
| `logiqa-zh` | 651 | 267.62 | 98 | 526 |
|
||||
| `gaokao-chinese` | 246 | 988.09 | 152 | 2186 |
|
||||
| `gaokao-geography` | 199 | 204.82 | 64 | 881 |
|
||||
| `gaokao-history` | 235 | 141.48 | 67 | 314 |
|
||||
| `gaokao-biology` | 210 | 203.98 | 75 | 685 |
|
||||
| `gaokao-chemistry` | 207 | 348.37 | 58 | 1454 |
|
||||
| `gaokao-physics` | 200 | 251.9 | 58 | 581 |
|
||||
| `gaokao-mathqa` | 351 | 201.59 | 93 | 615 |
|
||||
| `jec-qa-kd` | 1,000 | 170.43 | 54 | 454 |
|
||||
| `jec-qa-ca` | 1,000 | 240.71 | 79 | 883 |
|
||||
| `math` | 1,000 | 211.95 | 40 | 2186 |
|
||||
| `gaokao-mathcloze` | 118 | 123.42 | 48 | 501 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `aqua-rat`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "e28353e5",
|
||||
"content": "Q: A car is being driven, in a straight line and at a uniform speed, towards the base of a vertical tower. The top of the tower is observed from the car and, in the process, it takes 10 minutes for the angle of elevation to change from 45° to 60°. After how much more time will this car reach the base of the tower? Answer Choices: (A)5(√3 + 1) (B)6(√3 + √2) (C)7(√3 – 1) (D)8(√3 – 2) (E)None of these\nA: Among A through E, the answer is"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"(A)5(√3 + 1)",
|
||||
"(B)6(√3 + √2)",
|
||||
"(C)7(√3 – 1)",
|
||||
"(D)8(√3 – 2)",
|
||||
"(E)None of these"
|
||||
],
|
||||
"target": "A",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"subset": "aqua-rat",
|
||||
"has_passage": false
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The last line of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}. Think step by step before answering.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets agieval \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['agieval'],
|
||||
dataset_args={
|
||||
'agieval': {
|
||||
# subset_list: ['aqua-rat', 'logiqa-en', 'lsat-ar'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -36,7 +36,7 @@ AI2D (AI2 Diagrams) is a benchmark dataset for evaluating AI systems' ability to
|
||||
| **Dataset ID** | [lmms-lab/ai2d](https://modelscope.cn/datasets/lmms-lab/ai2d/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MultiModal`, `QA` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -130,5 +130,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ AIME 2024 (American Invitational Mathematics Examination 2024) is a benchmark ba
|
||||
| **Dataset ID** | [evalscope/aime24](https://modelscope.cn/datasets/evalscope/aime24/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -108,5 +108,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ AIME 2025 (American Invitational Mathematics Examination 2025) is a benchmark ba
|
||||
| **Dataset ID** | [evalscope/aime25](https://modelscope.cn/datasets/evalscope/aime25/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -107,5 +107,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ AIME 2026 (American Invitational Mathematics Examination 2026) is a benchmark ba
|
||||
| **Dataset ID** | [evalscope/aime26](https://modelscope.cn/datasets/evalscope/aime26/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -107,5 +107,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -10,39 +10,22 @@ AIR-Bench Chat is the generative half of [AIR-Bench](https://arxiv.org/abs/2402.
|
||||
- **Task Type**: Open-ended audio question answering.
|
||||
- **Input**: An audio clip plus a free-form question.
|
||||
- **Output**: A textual answer evaluated against the reference response.
|
||||
- **Modalities**: Audio (human speech, natural sounds, music) + text.
|
||||
|
||||
## Categories (8 tasks → 5 reported categories)
|
||||
## Key Features
|
||||
|
||||
The 8 Chat tasks are aggregated by the official `cal_score.py` into five categories:
|
||||
- ~2k open-ended audio QA pairs across speech, sound, music and mixed-audio scenes; the generative half of AIR-Bench (ACL 2024).
|
||||
- 8 Chat tasks aggregated by the official `cal_score.py` into 5 reported categories: `speech` (`speech_QA`, `speech_dialogue_QA`), `sound` (`sound_QA`, `sound_generation_QA`), `music` (`music_QA`, `music_generation_analysis_QA`), `speech_and_sound` (`speech_and_sound_QA`), `speech_and_music` (`speech_and_music_QA`). The paper's Mixed-audio = mean(speech_and_sound, speech_and_music).
|
||||
- Position bias is removed by judging every sample twice with reference/prediction order swapped, then averaging (disable via `extra_params={'do_swap': False}` to halve judge cost).
|
||||
- Hosted on ModelScope ([`evalscope/AIR-Bench-Dataset`](https://modelscope.cn/datasets/evalscope/AIR-Bench-Dataset)) in an audiofolder + JSON layout; the full release is ~49 GB, so limit tasks via `extra_params={'tasks': [...]}` for partial runs.
|
||||
|
||||
- `speech`: `speech_QA`, `speech_dialogue_QA`
|
||||
- `sound`: `sound_QA`, `sound_generation_QA`
|
||||
- `music`: `music_QA`, `music_generation_analysis_QA`
|
||||
- `speech_and_sound`: `speech_and_sound_QA`
|
||||
- `speech_and_music`: `speech_and_music_QA`
|
||||
## Evaluation Notes
|
||||
|
||||
The paper's **Mixed-audio = mean(speech_and_sound, speech_and_music)**.
|
||||
|
||||
## Dataset Access
|
||||
|
||||
- The dataset is hosted on ModelScope: [`evalscope/AIR-Bench-Dataset`](https://modelscope.cn/datasets/evalscope/AIR-Bench-Dataset). It uses an *audiofolder + JSON metadata* layout. evalscope downloads it lazily via `modelscope.dataset_snapshot_download` on first run; the full release is ~49 GB, so it is recommended to limit which tasks are pulled via `extra_params`.
|
||||
- Metrics: `judge_score` is the model's mean judge score; `win_rate` records how often the model strictly beats the reference.
|
||||
- The judge LLM receives the question, the textual audio description (`meta_info`), the reference answer (`answer_gt`), and the model's response, and outputs two integer scores in `[1, 10]`. Use a judge that supports long contexts, since `meta_info` may exceed 4k tokens for dialogue tasks.
|
||||
- The official leaderboard uses `gpt-4-0125-preview`. If that exact snapshot is unavailable, use an available GPT-4-class judge; absolute scores can drift versus the published numbers because the judge model changed.
|
||||
- If the dataset is already on disk, pass `dataset_args={'air_bench_chat': {'local_path': '/path/to/AIR-Bench-Dataset'}}`; the local root should contain `Chat/`.
|
||||
|
||||
## Evaluation Protocol
|
||||
|
||||
- The judge LLM (default: GPT-4) receives the question, the textual audio description (`meta_info` from the dataset), the reference answer (`answer_gt`), and the model's response. It outputs a single line with two integer scores in `[1, 10]`.
|
||||
- To remove position bias, every sample is judged twice with the order of reference and prediction swapped, then averaged. This mirrors `cal_score.py` in the official repository — disable it via `extra_params={'do_swap': False}` to halve judge cost.
|
||||
- Reported metric `gpt_score` is the model's mean judge score; `win_rate` records how often the model strictly beats the reference.
|
||||
|
||||
```{warning}
|
||||
The official leaderboard uses `gpt-4-0125-preview` as the judge model. If that exact snapshot is unavailable, use an available GPT-4-class judge; absolute scores can drift versus the published numbers because the judge model changed.
|
||||
```
|
||||
|
||||
## Implementation Notes
|
||||
|
||||
- The judge model is selected via `--judge-model-args`; ensure the model id supports long contexts (`meta_info` may exceed 4k tokens for dialogue tasks).
|
||||
- Set `extra_params={'tasks': [...]}` to evaluate only specific Chat task names — useful for partial runs.
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
@ -52,7 +35,7 @@ The official leaderboard uses `gpt-4-0125-preview` as the judge model. If that e
|
||||
| **Dataset ID** | [evalscope/AIR-Bench](https://modelscope.cn/datasets/evalscope/AIR-Bench/summary) |
|
||||
| **Paper** | [Paper](https://aclanthology.org/2024.acl-long.109/) |
|
||||
| **Tags** | `Audio`, `InstructionFollowing`, `QA` |
|
||||
| **Metrics** | `gpt_score`, `win_rate` |
|
||||
| **Metrics** | `judge_score`, `win_rate` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -171,5 +154,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -49,7 +49,7 @@ D. {choice_d}
|
||||
| **Dataset ID** | [evalscope/AIR-Bench](https://modelscope.cn/datasets/evalscope/AIR-Bench/summary) |
|
||||
| **Paper** | [Paper](https://aclanthology.org/2024.acl-long.109/) |
|
||||
| **Tags** | `Audio`, `Knowledge`, `MCQ` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -189,5 +189,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ AlpacaEval 2.0 is an evaluation framework for instruction-following language mod
|
||||
| **Dataset ID** | [AI-ModelScope/alpaca_eval](https://modelscope.cn/datasets/AI-ModelScope/alpaca_eval/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Arena`, `InstructionFollowing` |
|
||||
| **Metrics** | `winrate` |
|
||||
| **Metrics** | `win_rate` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `eval` |
|
||||
|
||||
@ -110,5 +110,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ AMC (American Mathematics Competitions) is a benchmark based on problems from th
|
||||
| **Dataset ID** | [evalscope/amc_22-24](https://modelscope.cn/datasets/evalscope/amc_22-24/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `N/A` |
|
||||
|
||||
@ -123,5 +123,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ The AnatEM corpus is an extensive resource for anatomical entity recognition, cr
|
||||
| **Dataset ID** | [extraordinarylab/anat-em](https://modelscope.cn/datasets/extraordinarylab/anat-em/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -186,5 +186,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ ARC (AI2 Reasoning Challenge) is a benchmark designed to evaluate science questi
|
||||
| **Dataset ID** | [allenai/ai2_arc](https://modelscope.cn/datasets/allenai/ai2_arc/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `MCQ`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -129,5 +129,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
115
evalscope/docs/en/benchmarks/arc_agi_2.md
Normal file
115
evalscope/docs/en/benchmarks/arc_agi_2.md
Normal file
@ -0,0 +1,115 @@
|
||||
# ARC-AGI-2
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
ARC-AGI-2 (Abstraction and Reasoning Corpus for Artificial General Intelligence 2) is a benchmark designed to measure an AI system's ability to efficiently acquire new skills on-the-fly, using only a handful of demonstrations. It evaluates abstract reasoning and pattern recognition through grid transformation tasks.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Abstract Reasoning / Pattern Recognition
|
||||
- **Input**: A series of input-output grid pairs (demonstrations) followed by a test input grid
|
||||
- **Output**: The predicted output grid matching the inferred transformation rule
|
||||
- **Grid Format**: 2D arrays of integers (0-9), variable sizes (up to 30x30)
|
||||
|
||||
## Key Features
|
||||
|
||||
- 1,000 public training tasks and 120 public evaluation tasks
|
||||
- Each task provides 2-10 demonstration input/output pairs
|
||||
- Models must infer the transformation rule from demonstrations
|
||||
- Tests abstract reasoning without reliance on learned knowledge
|
||||
- Pixel-perfect output required (exact grid match)
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Scoring is based on **exact grid match** (shape and all values must be identical)
|
||||
- Models must output the grid as a JSON 2D array
|
||||
- Zero-shot evaluation (demonstrations are provided within each task)
|
||||
- Designed to be solvable by humans but challenging for AI
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `arc_agi_2` |
|
||||
| **Dataset ID** | [evalscope/arc-agi-2](https://modelscope.cn/datasets/evalscope/arc-agi-2/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Reasoning` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Aggregation** | `mean_and_pass_hat_k` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 120 |
|
||||
| Prompt Length (Mean) | 8026.79 chars |
|
||||
| Prompt Length (Min/Max) | 2437 / 25471 chars |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `default`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "7b97143f",
|
||||
"content": "You are an expert at abstract reasoning and pattern recognition. Given input-output grid pairs as examples, you must figure out the transformation rule and apply it to a new test input to produce the correct output grid."
|
||||
},
|
||||
{
|
||||
"id": "bdaa2b22",
|
||||
"content": "You are given a series of input-output grid pairs as examples. Each grid is a 2D array of integers (0-9). Study the pattern in the examples, then predict the output for the test input.\n\nExamples:\nExample 1:\nInput: [[0, 0, 0, 0, 0, 0, 0, 0, 0, ... [TRUNCATED 7482 chars] ... 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0], [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]\n\nProvide the output grid as a JSON 2D array. Only output the JSON array, nothing else."
|
||||
}
|
||||
],
|
||||
"target": "[[8, 0, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 0, 8, 8, 8, 8], [8, 0, 8, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 8, 0, 0, 0, 0, 0], [8, 0, 8, 0, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 0, 8, 8, 8, 8, 8, 0], [ ... [TRUNCATED 1596 chars] ... ], [8, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 8, 0, 8, 0, 0, 0, 8, 0], [8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 8, 0, 8, 0, 8, 8, 8, 0], [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 8, 0, 8, 0, 0, 0]]",
|
||||
"id": 0,
|
||||
"group_id": 0
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**System Prompt:**
|
||||
```text
|
||||
You are an expert at abstract reasoning and pattern recognition. Given input-output grid pairs as examples, you must figure out the transformation rule and apply it to a new test input to produce the correct output grid.
|
||||
```
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
{question}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets arc_agi_2 \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['arc_agi_2'],
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
134
evalscope/docs/en/benchmarks/arc_indic.md
Normal file
134
evalscope/docs/en/benchmarks/arc_indic.md
Normal file
@ -0,0 +1,134 @@
|
||||
# ARC-Challenge-Indic
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
ARC-Challenge-Indic is a translation of the AI2 Reasoning Challenge (ARC-Challenge) science
|
||||
question-answering benchmark into 10 Indic languages, plus the original English set, for evaluating
|
||||
multilingual scientific reasoning.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Multilingual Multiple-Choice Science Question Answering
|
||||
- **Input**: Science question with answer choices in one of 11 languages
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: Bengali, English, Gujarati, Hindi, Kannada, Malayalam, Marathi, Odia, Punjabi, Tamil, Telugu
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split)
|
||||
- Use `subset_list` to evaluate specific languages (e.g., `['hi', 'ta']`)
|
||||
- Same underlying science-exam questions as `arc` (Challenge split), machine/human translated per language
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `arc_indic` |
|
||||
| **Dataset ID** | [sarvamai/arc-challenge-indic](https://modelscope.cn/datasets/sarvamai/arc-challenge-indic/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `MCQ`, `MultiLingual`, `Reasoning` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `validation` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 12,647 |
|
||||
| Prompt Length (Mean) | 448.01 chars |
|
||||
| Prompt Length (Min/Max) | 236 / 2053 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `bn` | 1,150 | 432.51 | 242 | 1137 |
|
||||
| `en` | 1,147 | 454.88 | 253 | 1111 |
|
||||
| `gu` | 1,150 | 426.57 | 243 | 1098 |
|
||||
| `hi` | 1,150 | 443.47 | 236 | 1162 |
|
||||
| `kn` | 1,150 | 456.08 | 245 | 1199 |
|
||||
| `ml` | 1,150 | 473.31 | 239 | 2053 |
|
||||
| `mr` | 1,150 | 434.22 | 242 | 1133 |
|
||||
| `or` | 1,150 | 440.04 | 243 | 1374 |
|
||||
| `pa` | 1,150 | 443.35 | 236 | 1132 |
|
||||
| `ta` | 1,150 | 479.12 | 243 | 1295 |
|
||||
| `te` | 1,150 | 444.53 | 244 | 1172 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `bn`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "f750462b",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nএকজন খগোলবিদ পর্যবেক্ষণ করেন যে একটি উল্কা পতনের পরে একটি গ্রহের ঘূর্ণন গতি বেড়ে যায়। ঘূর্ণন বৃদ্ধির ফলে কোন প্রভাবটি সবচেয়ে বেশি সম্ভাব্য?\n\nA) গ্রহের ঘনত্ব কমে যাবে।\nB) গ্রহীয় বছরগুলি আরও দীর্ঘ হবে।\nC) গ্রহের দিনগুলি ছোট হয়ে যাবে।\nD) গ্রহের মাধ্যাকর্ষণ শক্তি আরও বৃদ্ধি পাবে।"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"গ্রহের ঘনত্ব কমে যাবে।",
|
||||
"গ্রহীয় বছরগুলি আরও দীর্ঘ হবে।",
|
||||
"গ্রহের দিনগুলি ছোট হয়ে যাবে।",
|
||||
"গ্রহের মাধ্যাকর্ষণ শক্তি আরও বৃদ্ধি পাবে।"
|
||||
],
|
||||
"target": "C",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"id": "Mercury_7175875",
|
||||
"language": "Bengali"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets arc_indic \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['arc_indic'],
|
||||
dataset_args={
|
||||
'arc_indic': {
|
||||
# subset_list: ['bn', 'en', 'gu'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -37,7 +37,7 @@ ArenaHard is a challenging benchmark that evaluates language models through comp
|
||||
| **Dataset ID** | [AI-ModelScope/arena-hard-auto-v0.1](https://modelscope.cn/datasets/AI-ModelScope/arena-hard-auto-v0.1/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Arena`, `InstructionFollowing` |
|
||||
| **Metrics** | `winrate` |
|
||||
| **Metrics** | `win_rate` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Aggregation** | `elo` |
|
||||
@ -108,5 +108,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -34,7 +34,7 @@ ArXiv-Math is a benchmark of 103 research-level mathematics problems extracted f
|
||||
| **Dataset ID** | [evalscope/arxivmath](https://modelscope.cn/datasets/evalscope/arxivmath/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -127,5 +127,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ ArxivRollBench is a rolling benchmark built from recent arXiv papers. It evaluat
|
||||
| **Dataset ID** | [liangzid/arxivrollbench](https://modelscope.cn/datasets/liangzid/arxivrollbench/summary) |
|
||||
| **Paper** | [Paper](https://ojs.aaai.org/index.php/AAAI/article/view/41098) |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -199,5 +199,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ ArxivRollBench is a rolling benchmark built from recent arXiv papers. It evaluat
|
||||
| **Dataset ID** | [liangzid/arxivrollbench-full](https://modelscope.cn/datasets/liangzid/arxivrollbench-full/summary) |
|
||||
| **Paper** | [Paper](https://ojs.aaai.org/index.php/AAAI/article/view/41098) |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -199,5 +199,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
144
evalscope/docs/en/benchmarks/automation_bench.md
Normal file
144
evalscope/docs/en/benchmarks/automation_bench.md
Normal file
@ -0,0 +1,144 @@
|
||||
# AutomationBench
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
AutomationBench evaluates agents on realistic business workflows across sales, marketing, operations, support,
|
||||
finance, and HR. EvalScope runs the public tasks, simulated SaaS services, and assertion-based scoring provided by
|
||||
Zapier's official Python package.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Stateful business workflows across 47 simulated SaaS tools.
|
||||
- **Public Dataset**: 600 tasks, with 100 tasks in each of `sales`, `marketing`, `operations`, `support`, `finance`,
|
||||
and `hr`.
|
||||
- **Simple Baseline**: The optional `simple` subset contains 200 foundational single- and two-step tasks. Its metrics
|
||||
use the `simple_` prefix and are reported separately from the public benchmark score.
|
||||
- **Scoring**: `partial_credit` is the fraction of scored assertions satisfied. `pass_rate` is the mean official
|
||||
`task_completed_correctly` signal, which is 1 only when every scored assertion passes.
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Prepare a Python 3.13+ environment and install the pinned dependencies before evaluation:
|
||||
`python -m pip install "verifiers==0.1.12.dev2" "automation-bench @ git+https://github.com/zapier/AutomationBench.git@a321764ace3cfbe42289e6a13abef2f0f4f56fad"`.
|
||||
- By default, EvalScope evaluates all six public domains (600 tasks). Use `subset_list` to select domains or `limit`
|
||||
for a smaller run.
|
||||
- Use an API-backed EvalScope model with `openai_api`, `openai_responses_api`, or `anthropic_api` evaluation type.
|
||||
- No Docker runtime, external dataset download, or real SaaS credentials are required. Model API credentials are still
|
||||
required.
|
||||
- The released tasks are public. Zapier's official leaderboard uses a separate held-out private set, so local public
|
||||
scores are directional rather than leaderboard-identical.
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `automation_bench` |
|
||||
| **Dataset ID** | [AutomationBench](https://github.com/zapier/AutomationBench) |
|
||||
| **Paper** | [Paper](https://arxiv.org/abs/2604.18934) |
|
||||
| **Tags** | `Agent`, `FunctionCalling`, `MultiTurn` |
|
||||
| **Metrics** | `pass_rate`, `partial_credit`, `error_rate` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 600 |
|
||||
| Prompt Length (Mean) | 983.57 chars |
|
||||
| Prompt Length (Min/Max) | 586 / 1785 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `sales` | 100 | 832.89 | 586 | 1245 |
|
||||
| `marketing` | 100 | 953.02 | 612 | 1275 |
|
||||
| `operations` | 100 | 1259.54 | 787 | 1785 |
|
||||
| `support` | 100 | 937.56 | 711 | 1577 |
|
||||
| `finance` | 100 | 990.51 | 709 | 1259 |
|
||||
| `hr` | 100 | 927.91 | 689 | 1276 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `sales`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "97a20b04",
|
||||
"content": "You are a workflow automation agent. Execute the requested tasks using the available tools. Do not ask clarifying questions - use the information provided and make reasonable assumptions when needed. You have a budget of ~50 tool-using turns ... [TRUNCATED 47 chars] ... searches. When summarizing your work in messages or records, list only items you acted on. Do not name, enumerate, or explain items you skipped, excluded, or rejected — handle exclusions silently in the action, not narratively in the output.",
|
||||
"source": "input",
|
||||
"role": "system"
|
||||
},
|
||||
{
|
||||
"id": "4d75f740",
|
||||
"content": "We just closed the Meridian Corp Platform Deal! Mark it as won and route the win notice to the right team per our routing policy. Be sure to follow the latest routing guidelines. Confirm the account tier from the 'Account Hierarchy' spreadshe ... [TRUNCATED 160 chars] ... support-escalation@example.com, executive-team@example.com, sales-team@example.com, smb-team@example.com, vp-sales@example.com\n\nUse Gmail for all email sends. Include the names of affected entities and the relevant amounts in your message(s).",
|
||||
"source": "input",
|
||||
"role": "user"
|
||||
}
|
||||
],
|
||||
"target": "",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"subset_key": "sales",
|
||||
"metadata": {
|
||||
"record_key": "sales:0",
|
||||
"domain": "sales",
|
||||
"task": "sales.multi_hop_lookup",
|
||||
"official_example_id": 501
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
*Note: Some content was truncated for display.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
*No prompt template defined.*
|
||||
|
||||
## Extra Parameters
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `toolset` | `str` | `api` | Official tool style exposed to the agent. Choices: ['api', 'zapier', 'limited_zapier'] |
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets automation_bench \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['automation_bench'],
|
||||
dataset_args={
|
||||
'automation_bench': {
|
||||
# subset_list: ['sales', 'marketing', 'operations'] # optional, evaluate specific subsets
|
||||
# extra_params: {} # uses default extra parameters
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -30,7 +30,7 @@ recognition, and visual tracking.
|
||||
- Primary metric: **Accuracy** via LLM-as-judge
|
||||
- Subsets organized by `type` field (4 categories)
|
||||
- LLM judge evaluates both choice and blank answer types uniformly
|
||||
- Requires `judge_model_args` configuration for LLM judge
|
||||
- Requires an LLM judge configured through `judge.models`
|
||||
|
||||
|
||||
## Properties
|
||||
@ -41,37 +41,14 @@ recognition, and visual tracking.
|
||||
| **Dataset ID** | [evalscope/BabyVision](https://modelscope.cn/datasets/evalscope/BabyVision/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `MultiModal`, `QA`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 388 |
|
||||
| Prompt Length (Mean) | 167.37 chars |
|
||||
| Prompt Length (Min/Max) | 33 / 450 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `Fine-grained Discrimination` | 163 | 152.09 | 33 | 450 |
|
||||
| `Spatial Perception` | 91 | 157.18 | 73 | 370 |
|
||||
| `Visual Pattern Recognition` | 51 | 178.92 | 94 | 319 |
|
||||
| `Visual Tracking` | 83 | 201.45 | 97 | 389 |
|
||||
|
||||
**Image Statistics:**
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Images | 388 |
|
||||
| Images per Sample | min: 1, max: 1, mean: 1 |
|
||||
| Resolution Range | 174x144 - 2378x1448 |
|
||||
| Formats | jpeg, png, webp |
|
||||
|
||||
*Statistics not available.*
|
||||
|
||||
## Sample Example
|
||||
|
||||
@ -81,13 +58,13 @@ recognition, and visual tracking.
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "8b83904b",
|
||||
"id": "1256c961",
|
||||
"content": [
|
||||
{
|
||||
"image": "[BASE64_IMAGE: jpeg, ~77.0KB]"
|
||||
},
|
||||
{
|
||||
"text": "The image shows a total of 49 tiger patterns arranged in 7 rows and 7 columns. One of them is different from the others. Which row and column is it in? The answer format is (x,y). (For example, the answer for the 2nd row and 3rd column is (2,3))."
|
||||
"text": "The image shows a total of 49 tiger patterns arranged in 7 rows and 7 columns. One of them is different from the others. Which row and column is it in? The answer format is (x,y). (For example, the answer for the 2nd row and 3rd column is (2,3)).\nThink about the question and give your final answer in \\boxed{Answer} format."
|
||||
}
|
||||
]
|
||||
}
|
||||
@ -134,15 +111,8 @@ task_cfg = TaskConfig(
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['baby_vision'],
|
||||
dataset_args={
|
||||
'baby_vision': {
|
||||
# subset_list: ['Fine-grained Discrimination', 'Spatial Perception', 'Visual Pattern Recognition'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -23,7 +23,7 @@ BBH (BIG-Bench Hard) is a subset of 23 challenging tasks from the BIG-Bench benc
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **3-shot** with CoT prompting (recommended)
|
||||
- CoT prompts are pre-defined for each subset in `cot_prompts/` directory
|
||||
- CoT prompts are pre-defined for each subset in `cot_prompts.py`
|
||||
- Answers should follow the format: "So the answer is [ANSWER]"
|
||||
- Setting `few_shot_num=0` disables few-shot examples
|
||||
- Multiple-choice answers are normalized to single letters (A, B, C, etc.)
|
||||
@ -37,7 +37,7 @@ BBH (BIG-Bench Hard) is a subset of 23 challenging tasks from the BIG-Bench benc
|
||||
| **Dataset ID** | [evalscope/bbh](https://modelscope.cn/datasets/evalscope/bbh/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 3-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -162,5 +162,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ The BC2GM (BioCreative II Gene Mention) dataset is a widely used corpus for gene
|
||||
| **Dataset ID** | [extraordinarylab/bc2gm](https://modelscope.cn/datasets/extraordinarylab/bc2gm/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -210,5 +210,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ The BC4CHEMD (BioCreative IV CHEMDNER) dataset is a corpus of 10,000 PubMed abst
|
||||
| **Dataset ID** | [extraordinarylab/bc4chemd](https://modelscope.cn/datasets/extraordinarylab/bc4chemd/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -222,5 +222,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ The BC5CDR corpus is a manually annotated resource of 1,500 PubMed articles deve
|
||||
| **Dataset ID** | [extraordinarylab/bc5cdr](https://modelscope.cn/datasets/extraordinarylab/bc5cdr/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -210,5 +210,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -38,7 +38,7 @@ BFCL (Berkeley Function Calling Leaderboard) v3 is the first comprehensive and e
|
||||
| **Dataset ID** | [AI-ModelScope/bfcl_v3](https://modelscope.cn/datasets/AI-ModelScope/bfcl_v3/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Agent`, `FunctionCalling` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -232,5 +232,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ BFCL-v4 (Berkeley Function-Calling Leaderboard V4) is a comprehensive benchmark
|
||||
| **Dataset ID** | [berkeley-function-call-leaderboard](https://github.com/ShishirPatil/gorilla/tree/main/berkeley-function-call-leaderboard) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Agent`, `FunctionCalling` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -178,5 +178,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_ayur.md
Normal file
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_ayur.md
Normal file
@ -0,0 +1,155 @@
|
||||
# BhashaBench-Multi (Ayurveda)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Multi (Ayurveda) is a domain-specific multiple-choice benchmark evaluating LLM knowledge
|
||||
of Ayurvedic medicine across 22 Indic languages. Each question originates in English and is machine
|
||||
translated (with LLM-judged translation quality scores) into the target language; this adapter uses
|
||||
the translated question/choices.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: A Ayurvedic medicine question with 4 answer choices, in one of 22 Indic languages
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili,
|
||||
Malayalam, Manipuri, Marathi, Nepali, Oriya, Punjabi, Sanskrit, Santhali, Sindhi, Tamil, Telugu, Urdu
|
||||
|
||||
## Key Features
|
||||
|
||||
- ~14,963 questions per language across 22 Indic languages per domain (~330k total per domain)
|
||||
- Machine-translated from English with LLM-judged translation quality scores
|
||||
- 22 scheduled languages of India, all in native script; no English split
|
||||
- Four domains available as separate benchmarks: Ayurveda, Finance, Krishi, Legal
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate specific languages (e.g., `['Hindi', 'Tamil']`), or `limit` to cap
|
||||
sample count — each domain is ~14,963 questions per language across 22 languages (~330k total),
|
||||
so evaluating every language's full split is a large run
|
||||
- No English split exists for this dataset
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhasha_bench_multi_ayur` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Multi](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Multi/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 329,186 |
|
||||
| Prompt Length (Mean) | 317.8 chars |
|
||||
| Prompt Length (Min/Max) | 220 / 8370 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `Assamese` | 14,963 | 325.76 | 229 | 4447 |
|
||||
| `Bengali` | 14,963 | 313.28 | 231 | 1933 |
|
||||
| `Bodo` | 14,963 | 315.55 | 222 | 1795 |
|
||||
| `Dogri` | 14,963 | 308.39 | 225 | 1974 |
|
||||
| `Gujarati` | 14,963 | 313.22 | 227 | 1526 |
|
||||
| `Hindi` | 14,963 | 313.66 | 230 | 2018 |
|
||||
| `Kannada` | 14,963 | 316.92 | 230 | 8305 |
|
||||
| `Kashmiri` | 14,963 | 339.03 | 243 | 2102 |
|
||||
| `Konkani` | 14,963 | 307.78 | 227 | 1819 |
|
||||
| `Maithili` | 14,963 | 305.52 | 225 | 2142 |
|
||||
| `Malayalam` | 14,963 | 330.73 | 236 | 1862 |
|
||||
| `Manipuri` | 14,963 | 332.17 | 234 | 2247 |
|
||||
| `Marathi` | 14,963 | 312.05 | 229 | 8370 |
|
||||
| `Nepali` | 14,963 | 312.62 | 229 | 1825 |
|
||||
| `Oriya` | 14,963 | 312.36 | 226 | 4092 |
|
||||
| `Punjabi` | 14,963 | 309.98 | 220 | 926 |
|
||||
| `Sanskrit` | 14,963 | 312.86 | 225 | 1232 |
|
||||
| `Santhali` | 14,963 | 334.48 | 234 | 2283 |
|
||||
| `Sindhi` | 14,963 | 309.44 | 226 | 852 |
|
||||
| `Tamil` | 14,963 | 331.24 | 236 | 1031 |
|
||||
| `Telugu` | 14,963 | 319.9 | 232 | 911 |
|
||||
| `Urdu` | 14,963 | 314.71 | 227 | 921 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `Assamese`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "4ac474ca",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nইমিউনজনিত বিকাৰসমূহৰ ভিতৰত আছে .....\n\nA) অতিরিক্ত সংবেদনশীলতা\nB) স্বয়ং-প্রতিরোধ ক্ষমতা জনিত ৰোগ\nC) রোগ প্রতিরোধ ক্ষমতাৰ অভাৱ\nD) এই সকলোবোৰ।"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"অতিরিক্ত সংবেদনশীলতা",
|
||||
"স্বয়ং-প্রতিরোধ ক্ষমতা জনিত ৰোগ",
|
||||
"রোগ প্রতিরোধ ক্ষমতাৰ অভাৱ",
|
||||
"এই সকলোবোৰ।"
|
||||
],
|
||||
"target": "D",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "Assamese",
|
||||
"topic": "Kayachikitsa"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhasha_bench_multi_ayur \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhasha_bench_multi_ayur'],
|
||||
dataset_args={
|
||||
'bhasha_bench_multi_ayur': {
|
||||
# subset_list: ['Assamese', 'Bengali', 'Bodo'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
95
evalscope/docs/en/benchmarks/bhasha_bench_multi_finance.md
Normal file
95
evalscope/docs/en/benchmarks/bhasha_bench_multi_finance.md
Normal file
@ -0,0 +1,95 @@
|
||||
# BhashaBench-Multi (Finance)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Multi (Finance) is a domain-specific multiple-choice benchmark evaluating LLM knowledge
|
||||
of finance across 22 Indic languages. Each question originates in English and is machine
|
||||
translated (with LLM-judged translation quality scores) into the target language; this adapter uses
|
||||
the translated question/choices.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: A finance question with 4 answer choices, in one of 22 Indic languages
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili,
|
||||
Malayalam, Manipuri, Marathi, Nepali, Oriya, Punjabi, Sanskrit, Santhali, Sindhi, Tamil, Telugu, Urdu
|
||||
|
||||
## Key Features
|
||||
|
||||
- ~14,963 questions per language across 22 Indic languages per domain (~330k total per domain)
|
||||
- Machine-translated from English with LLM-judged translation quality scores
|
||||
- 22 scheduled languages of India, all in native script; no English split
|
||||
- Four domains available as separate benchmarks: Ayurveda, Finance, Krishi, Legal
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate specific languages (e.g., `['Hindi', 'Tamil']`), or `limit` to cap
|
||||
sample count — each domain is ~14,963 questions per language across 22 languages (~330k total),
|
||||
so evaluating every language's full split is a large run
|
||||
- No English split exists for this dataset
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhasha_bench_multi_finance` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Multi](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Multi/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
*Statistics not available.*
|
||||
|
||||
## Sample Example
|
||||
|
||||
*Sample example not available.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhasha_bench_multi_finance \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhasha_bench_multi_finance'],
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_krishi.md
Normal file
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_krishi.md
Normal file
@ -0,0 +1,155 @@
|
||||
# BhashaBench-Multi (Krishi)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Multi (Krishi) is a domain-specific multiple-choice benchmark evaluating LLM knowledge
|
||||
of agriculture (Krishi) across 22 Indic languages. Each question originates in English and is machine
|
||||
translated (with LLM-judged translation quality scores) into the target language; this adapter uses
|
||||
the translated question/choices.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: A agriculture (Krishi) question with 4 answer choices, in one of 22 Indic languages
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili,
|
||||
Malayalam, Manipuri, Marathi, Nepali, Oriya, Punjabi, Sanskrit, Santhali, Sindhi, Tamil, Telugu, Urdu
|
||||
|
||||
## Key Features
|
||||
|
||||
- ~14,963 questions per language across 22 Indic languages per domain (~330k total per domain)
|
||||
- Machine-translated from English with LLM-judged translation quality scores
|
||||
- 22 scheduled languages of India, all in native script; no English split
|
||||
- Four domains available as separate benchmarks: Ayurveda, Finance, Krishi, Legal
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate specific languages (e.g., `['Hindi', 'Tamil']`), or `limit` to cap
|
||||
sample count — each domain is ~14,963 questions per language across 22 languages (~330k total),
|
||||
so evaluating every language's full split is a large run
|
||||
- No English split exists for this dataset
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhasha_bench_multi_krishi` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Multi](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Multi/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 338,910 |
|
||||
| Prompt Length (Mean) | 411.84 chars |
|
||||
| Prompt Length (Min/Max) | 207 / 2882 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `Assamese` | 15,405 | 402.14 | 224 | 2265 |
|
||||
| `Bengali` | 15,405 | 406.38 | 224 | 1506 |
|
||||
| `Bodo` | 15,405 | 417.81 | 207 | 2186 |
|
||||
| `Dogri` | 15,405 | 403.83 | 220 | 1988 |
|
||||
| `Gujarati` | 15,405 | 397.6 | 224 | 1380 |
|
||||
| `Hindi` | 15,405 | 407.8 | 224 | 1572 |
|
||||
| `Kannada` | 15,405 | 407.21 | 224 | 1407 |
|
||||
| `Kashmiri` | 15,405 | 442.73 | 245 | 2668 |
|
||||
| `Konkani` | 15,405 | 402.57 | 222 | 1969 |
|
||||
| `Maithili` | 15,405 | 393.7 | 224 | 1783 |
|
||||
| `Malayalam` | 15,405 | 429.89 | 224 | 1661 |
|
||||
| `Manipuri` | 15,405 | 436.33 | 240 | 2882 |
|
||||
| `Marathi` | 15,405 | 406.47 | 224 | 1520 |
|
||||
| `Nepali` | 15,405 | 402.05 | 224 | 1440 |
|
||||
| `Oriya` | 15,405 | 392.2 | 221 | 1366 |
|
||||
| `Punjabi` | 15,405 | 404.2 | 222 | 1536 |
|
||||
| `Sanskrit` | 15,405 | 411.22 | 224 | 1412 |
|
||||
| `Santhali` | 15,405 | 440.59 | 234 | 2773 |
|
||||
| `Sindhi` | 15,405 | 392.36 | 224 | 1233 |
|
||||
| `Tamil` | 15,405 | 441.53 | 224 | 2165 |
|
||||
| `Telugu` | 15,405 | 412.75 | 224 | 1432 |
|
||||
| `Urdu` | 15,405 | 409.12 | 224 | 2132 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `Assamese`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "70df7242",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nইয়াকোনো বিশেষ স্থান আৰু সময়ত বায়ুমণ্ডলৰ অৱস্থা বা পৰিস্থিতি বুলি কোৱা হয়।\n\nA) জলবায়ু\nB) আবহাওয়া\nC) পৰ্যাৱৰণ\nD) বায়ুমণ্ডল"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"জলবায়ু",
|
||||
"আবহাওয়া",
|
||||
"পৰ্যাৱৰণ",
|
||||
"বায়ুমণ্ডল"
|
||||
],
|
||||
"target": "B",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "Assamese",
|
||||
"topic": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhasha_bench_multi_krishi \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhasha_bench_multi_krishi'],
|
||||
dataset_args={
|
||||
'bhasha_bench_multi_krishi': {
|
||||
# subset_list: ['Assamese', 'Bengali', 'Bodo'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_legal.md
Normal file
155
evalscope/docs/en/benchmarks/bhasha_bench_multi_legal.md
Normal file
@ -0,0 +1,155 @@
|
||||
# BhashaBench-Multi (Legal)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Multi (Legal) is a domain-specific multiple-choice benchmark evaluating LLM knowledge
|
||||
of Indian law across 22 Indic languages. Each question originates in English and is machine
|
||||
translated (with LLM-judged translation quality scores) into the target language; this adapter uses
|
||||
the translated question/choices.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: A Indian law question with 4 answer choices, in one of 22 Indic languages
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili,
|
||||
Malayalam, Manipuri, Marathi, Nepali, Oriya, Punjabi, Sanskrit, Santhali, Sindhi, Tamil, Telugu, Urdu
|
||||
|
||||
## Key Features
|
||||
|
||||
- ~14,963 questions per language across 22 Indic languages per domain (~330k total per domain)
|
||||
- Machine-translated from English with LLM-judged translation quality scores
|
||||
- 22 scheduled languages of India, all in native script; no English split
|
||||
- Four domains available as separate benchmarks: Ayurveda, Finance, Krishi, Legal
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate specific languages (e.g., `['Hindi', 'Tamil']`), or `limit` to cap
|
||||
sample count — each domain is ~14,963 questions per language across 22 languages (~330k total),
|
||||
so evaluating every language's full split is a large run
|
||||
- No English split exists for this dataset
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhasha_bench_multi_legal` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Multi](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Multi/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 536,030 |
|
||||
| Prompt Length (Mean) | 490.89 chars |
|
||||
| Prompt Length (Min/Max) | 225 / 6384 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `Assamese` | 24,365 | 475.08 | 232 | 2556 |
|
||||
| `Bengali` | 24,365 | 482.5 | 235 | 2066 |
|
||||
| `Bodo` | 24,365 | 521.23 | 225 | 4608 |
|
||||
| `Dogri` | 24,365 | 487.72 | 225 | 4432 |
|
||||
| `Gujarati` | 24,365 | 463.64 | 232 | 1954 |
|
||||
| `Hindi` | 24,365 | 489.37 | 232 | 2202 |
|
||||
| `Kannada` | 24,365 | 475.35 | 232 | 2068 |
|
||||
| `Kashmiri` | 24,365 | 514.54 | 242 | 5037 |
|
||||
| `Konkani` | 24,365 | 473.95 | 225 | 4000 |
|
||||
| `Maithili` | 24,365 | 473.11 | 225 | 4011 |
|
||||
| `Malayalam` | 24,365 | 511.29 | 236 | 2218 |
|
||||
| `Manipuri` | 24,365 | 548.36 | 238 | 6384 |
|
||||
| `Marathi` | 24,365 | 487.86 | 232 | 2113 |
|
||||
| `Nepali` | 24,365 | 475.87 | 234 | 2058 |
|
||||
| `Oriya` | 24,365 | 458.86 | 232 | 1936 |
|
||||
| `Punjabi` | 24,365 | 483.03 | 232 | 2138 |
|
||||
| `Sanskrit` | 24,365 | 489.0 | 233 | 1979 |
|
||||
| `Santhali` | 24,365 | 549.75 | 233 | 5074 |
|
||||
| `Sindhi` | 24,365 | 455.74 | 234 | 1830 |
|
||||
| `Tamil` | 24,365 | 522.97 | 237 | 2479 |
|
||||
| `Telugu` | 24,365 | 481.32 | 234 | 1992 |
|
||||
| `Urdu` | 24,365 | 479.13 | 235 | 2120 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `Assamese`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "e631cc6e",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nকোনো আদেশ প্ৰকাশ কৰাৰ পূৰ্বতে কোনো সমস্যা সংশোধন কৰাৰ বা নতুন সমস্যা উত্থাপন কৰাৰ ক্ষমতা আদালতৰ ওচৰত থাকে, আৰু এই ক্ষমতা দিয়া হয় দেৱানী প্রক্রিয়া বিধি, ১৯০৮-ৰ কোনটো ব্যৱস্থাৰ দ্বাৰা?\n\nA) অধ্যায় ১৪, বিধি ১\nB) অধ্যায় ১৪, বিধি ৫\nC) অধ্যায় XIV, বিধি ৬\nD) ধাৰা ১৫১"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"অধ্যায় ১৪, বিধি ১",
|
||||
"অধ্যায় ১৪, বিধি ৫",
|
||||
"অধ্যায় XIV, বিধি ৬",
|
||||
"ধাৰা ১৫১"
|
||||
],
|
||||
"target": "B",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "Assamese",
|
||||
"topic": "Procedural Law"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhasha_bench_multi_legal \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhasha_bench_multi_legal'],
|
||||
dataset_args={
|
||||
'bhasha_bench_multi_legal': {
|
||||
# subset_list: ['Assamese', 'Bengali', 'Bodo'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
133
evalscope/docs/en/benchmarks/bhashabenchv1_ayur.md
Normal file
133
evalscope/docs/en/benchmarks/bhashabenchv1_ayur.md
Normal file
@ -0,0 +1,133 @@
|
||||
# BhashaBench-V1 (Ayurveda)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Ayur is the predecessor of BhashaBench-Multi's ayur domain: a domain-specific
|
||||
multiple-choice benchmark evaluating LLM knowledge of Ayurvedic medicine, covering English and Hindi.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: An Ayurvedic medicine question with 4 answer choices, in English or Hindi
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: English, Hindi
|
||||
|
||||
## Key Features
|
||||
|
||||
- 5,600–17,000 questions per language, covering English and Hindi only
|
||||
- Predecessor of BhashaBench-Multi: same domains, narrower language coverage
|
||||
- Each domain is a separate repository, with English and Hindi as separate configs
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate a single language (e.g., `['Hindi']`)
|
||||
- Requires access to this gated dataset - on ModelScope (the default hub), accept the terms and
|
||||
ensure you're logged in; alternatively, set `dataset_hub` to `huggingface` and use `HF_TOKEN`
|
||||
after accepting the terms on huggingface.co
|
||||
- For broader language coverage of the same domain, see `bhasha_bench_multi_ayur`
|
||||
(22 Indic languages, not gated)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhashabenchv1_ayur` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Ayur](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Ayur/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 14,963 |
|
||||
| Prompt Length (Mean) | 307.52 chars |
|
||||
| Prompt Length (Min/Max) | 222 / 1060 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `English` | 9,348 | 310.35 | 227 | 1060 |
|
||||
| `Hindi` | 5,615 | 302.81 | 222 | 938 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `English`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "6a6db8b7",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nImmune disorders include .....,\n\nA) Hypersensitivity\nB) auto-immune diseases\nC) immunodeficiency\nD) all of these"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"Hypersensitivity",
|
||||
"auto-immune diseases",
|
||||
"immunodeficiency",
|
||||
"all of these"
|
||||
],
|
||||
"target": "D",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "English",
|
||||
"topic": "Kayachikitsa"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhashabenchv1_ayur \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhashabenchv1_ayur'],
|
||||
dataset_args={
|
||||
'bhashabenchv1_ayur': {
|
||||
# subset_list: ['English', 'Hindi'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
133
evalscope/docs/en/benchmarks/bhashabenchv1_finance.md
Normal file
133
evalscope/docs/en/benchmarks/bhashabenchv1_finance.md
Normal file
@ -0,0 +1,133 @@
|
||||
# BhashaBench-V1 (Finance)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Finance is the predecessor of BhashaBench-Multi's finance domain: a domain-specific
|
||||
multiple-choice benchmark evaluating LLM knowledge of finance, covering English and Hindi.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: A finance question with 4 answer choices, in English or Hindi
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: English, Hindi
|
||||
|
||||
## Key Features
|
||||
|
||||
- 5,600–17,000 questions per language, covering English and Hindi only
|
||||
- Predecessor of BhashaBench-Multi: same domains, narrower language coverage
|
||||
- Each domain is a separate repository, with English and Hindi as separate configs
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate a single language (e.g., `['Hindi']`)
|
||||
- Requires access to this gated dataset - on ModelScope (the default hub), accept the terms and
|
||||
ensure you're logged in; alternatively, set `dataset_hub` to `huggingface` and use `HF_TOKEN`
|
||||
after accepting the terms on huggingface.co
|
||||
- For broader language coverage of the same domain, see `bhasha_bench_multi_finance`
|
||||
(22 Indic languages, not gated)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhashabenchv1_finance` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Finance](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Finance/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 19,433 |
|
||||
| Prompt Length (Mean) | 612.82 chars |
|
||||
| Prompt Length (Min/Max) | 221 / 6665 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `English` | 13,451 | 663.98 | 223 | 6665 |
|
||||
| `Hindi` | 5,982 | 497.79 | 221 | 3304 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `English`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "befc8699",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nIn the following number series. One number is wrong. Find the wrong number of the series? 3, 4, 12, 38, 103, 228\n\nA) 103\nB) 12\nC) 38\nD) 228"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"103",
|
||||
"12",
|
||||
"38",
|
||||
"228"
|
||||
],
|
||||
"target": "C",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "English",
|
||||
"topic": "Quantitative Aptitude"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhashabenchv1_finance \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhashabenchv1_finance'],
|
||||
dataset_args={
|
||||
'bhashabenchv1_finance': {
|
||||
# subset_list: ['English', 'Hindi'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
133
evalscope/docs/en/benchmarks/bhashabenchv1_krishi.md
Normal file
133
evalscope/docs/en/benchmarks/bhashabenchv1_krishi.md
Normal file
@ -0,0 +1,133 @@
|
||||
# BhashaBench-V1 (Krishi)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Krishi is the predecessor of BhashaBench-Multi's krishi domain: a domain-specific
|
||||
multiple-choice benchmark evaluating LLM knowledge of agriculture (Krishi), covering English and Hindi.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: An agriculture (Krishi) question with 4 answer choices, in English or Hindi
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: English, Hindi
|
||||
|
||||
## Key Features
|
||||
|
||||
- 5,600–17,000 questions per language, covering English and Hindi only
|
||||
- Predecessor of BhashaBench-Multi: same domains, narrower language coverage
|
||||
- Each domain is a separate repository, with English and Hindi as separate configs
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate a single language (e.g., `['Hindi']`)
|
||||
- Requires access to this gated dataset - on ModelScope (the default hub), accept the terms and
|
||||
ensure you're logged in; alternatively, set `dataset_hub` to `huggingface` and use `HF_TOKEN`
|
||||
after accepting the terms on huggingface.co
|
||||
- For broader language coverage of the same domain, see `bhasha_bench_multi_krishi`
|
||||
(22 Indic languages, not gated)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhashabenchv1_krishi` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Krishi](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Krishi/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 15,405 |
|
||||
| Prompt Length (Mean) | 409.45 chars |
|
||||
| Prompt Length (Min/Max) | 223 / 1841 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `English` | 12,648 | 429.18 | 223 | 1841 |
|
||||
| `Hindi` | 2,757 | 318.93 | 233 | 678 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `English`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "afa2a6e0",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nIt is state or condition of atmosphere at given place and given time.?\n\nA) Climate\nB) Weather\nC) Environment\nD) Atmosphere"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"Climate",
|
||||
"Weather",
|
||||
"Environment",
|
||||
"Atmosphere"
|
||||
],
|
||||
"target": "B",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "English",
|
||||
"topic": ""
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhashabenchv1_krishi \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhashabenchv1_krishi'],
|
||||
dataset_args={
|
||||
'bhashabenchv1_krishi': {
|
||||
# subset_list: ['English', 'Hindi'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
133
evalscope/docs/en/benchmarks/bhashabenchv1_legal.md
Normal file
133
evalscope/docs/en/benchmarks/bhashabenchv1_legal.md
Normal file
@ -0,0 +1,133 @@
|
||||
# BhashaBench-V1 (Legal)
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
BhashaBench-Legal is the predecessor of BhashaBench-Multi's legal domain: a domain-specific
|
||||
multiple-choice benchmark evaluating LLM knowledge of Indian law, covering English and Hindi.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Domain-Specific Multiple-Choice Question Answering
|
||||
- **Input**: An Indian law question with 4 answer choices, in English or Hindi
|
||||
- **Output**: Correct answer letter
|
||||
- **Languages**: English, Hindi
|
||||
|
||||
## Key Features
|
||||
|
||||
- 5,600–17,000 questions per language, covering English and Hindi only
|
||||
- Predecessor of BhashaBench-Multi: same domains, narrower language coverage
|
||||
- Each domain is a separate repository, with English and Hindi as separate configs
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation (test split, the only split available)
|
||||
- Use `subset_list` to evaluate a single language (e.g., `['Hindi']`)
|
||||
- Requires access to this gated dataset - on ModelScope (the default hub), accept the terms and
|
||||
ensure you're logged in; alternatively, set `dataset_hub` to `huggingface` and use `HF_TOKEN`
|
||||
after accepting the terms on huggingface.co
|
||||
- For broader language coverage of the same domain, see `bhasha_bench_multi_legal`
|
||||
(22 Indic languages, not gated)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `bhashabenchv1_legal` |
|
||||
| **Dataset ID** | [bharatgenai/BhashaBench-Legal](https://modelscope.cn/datasets/bharatgenai/BhashaBench-Legal/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiLingual` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 24,365 |
|
||||
| Prompt Length (Mean) | 513.88 chars |
|
||||
| Prompt Length (Min/Max) | 229 / 4628 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `English` | 17,047 | 539.36 | 233 | 4628 |
|
||||
| `Hindi` | 7,318 | 454.52 | 229 | 1748 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `English`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "6e1ae42b",
|
||||
"content": "Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of A,B,C,D.\n\nPower to amend the issue or frame additional issues prior to passing of a decree vests in a Court by virtue of which provision of the Code of Civil Procedure, 1908?\n\nA) Order XIV Rule 1\nB) Order XIV Rule 5\nC) Order XIV Rule 6\nD) Section 151"
|
||||
}
|
||||
],
|
||||
"choices": [
|
||||
"Order XIV Rule 1",
|
||||
"Order XIV Rule 5",
|
||||
"Order XIV Rule 6",
|
||||
"Section 151"
|
||||
],
|
||||
"target": "B",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"language": "English",
|
||||
"topic": "Procedural Law"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The entire content of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets bhashabenchv1_legal \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['bhashabenchv1_legal'],
|
||||
dataset_args={
|
||||
'bhashabenchv1_legal': {
|
||||
# subset_list: ['English', 'Hindi'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -37,7 +37,7 @@ BigCodeBench is an easy-to-use benchmark for solving practical and challenging t
|
||||
| **Dataset ID** | [evalscope/bigcodebench](https://modelscope.cn/datasets/evalscope/bigcodebench/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Coding` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `v0.1.4` |
|
||||
| **Aggregation** | `mean_and_pass_at_k` |
|
||||
@ -86,6 +86,9 @@ BigCodeBench is an easy-to-use benchmark for solving practical and challenging t
|
||||
| `split` | `str` | `instruct` | Evaluation mode: "complete" (docstring completion) or "instruct" (NL instruction). Choices: ['complete', 'instruct'] |
|
||||
| `version` | `str` | `default` | Dataset version. Use "default" for the latest available version. |
|
||||
| `calibrate` | `bool` | `True` | Whether to prepend code_prompt to the solution for function signature alignment. |
|
||||
| `docker_build_context` | `str` | `` | Optional local Docker build context. When set, overrides the default sandbox image. |
|
||||
| `dockerfile` | `str` | `Dockerfile` | Dockerfile path inside docker_build_context. |
|
||||
| `force_rebuild` | `bool` | `False` | Force rebuilding the optional local Docker image. |
|
||||
|
||||
## Sandbox Configuration
|
||||
|
||||
@ -138,5 +141,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ BigCodeBench-Hard is a curated subset of BigCodeBench containing 148 tasks that
|
||||
| **Dataset ID** | [evalscope/bigcodebench-hard](https://modelscope.cn/datasets/evalscope/bigcodebench-hard/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Coding` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `v0.1.4` |
|
||||
| **Aggregation** | `mean_and_pass_at_k` |
|
||||
@ -90,6 +90,9 @@ BigCodeBench-Hard is a curated subset of BigCodeBench containing 148 tasks that
|
||||
| `split` | `str` | `instruct` | Evaluation mode: "complete" (docstring completion) or "instruct" (NL instruction). Choices: ['complete', 'instruct'] |
|
||||
| `version` | `str` | `default` | Dataset version. Use "default" for the latest available version. |
|
||||
| `calibrate` | `bool` | `True` | Whether to prepend code_prompt to the solution for function signature alignment. |
|
||||
| `docker_build_context` | `str` | `` | Optional local Docker build context. When set, overrides the default sandbox image. |
|
||||
| `dockerfile` | `str` | `Dockerfile` | Dockerfile path inside docker_build_context. |
|
||||
| `force_rebuild` | `bool` | `False` | Force rebuilding the optional local Docker image. |
|
||||
|
||||
## Sandbox Configuration
|
||||
|
||||
@ -142,5 +145,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -34,7 +34,7 @@ BiomixQA is a curated biomedical question-answering dataset designed to evaluate
|
||||
| **Dataset ID** | [extraordinarylab/biomix-qa](https://modelscope.cn/datasets/extraordinarylab/biomix-qa/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `Medical` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -113,5 +113,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ BLINK is a benchmark designed to evaluate the core visual perception abilities o
|
||||
| **Dataset ID** | [evalscope/BLINK](https://modelscope.cn/datasets/evalscope/BLINK/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiModal` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `val` |
|
||||
|
||||
@ -159,5 +159,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -33,7 +33,7 @@ BroadTwitterCorpus is a dataset of tweets collected over stratified times, place
|
||||
| **Dataset ID** | [extraordinarylab/broad-twitter-corpus](https://modelscope.cn/datasets/extraordinarylab/broad-twitter-corpus/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -196,5 +196,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -94,5 +94,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ CCBench (Chinese Culture Bench) is an extension of MMBench specifically designed
|
||||
| **Dataset ID** | [lmms-lab/MMBench](https://modelscope.cn/datasets/lmms-lab/MMBench/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiModal` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -136,5 +136,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
169
evalscope/docs/en/benchmarks/cc_ocr_v2.md
Normal file
169
evalscope/docs/en/benchmarks/cc_ocr_v2.md
Normal file
@ -0,0 +1,169 @@
|
||||
# CC-OCR-V2
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
CC-OCR V2 is a challenging OCR benchmark tailored to real-world enterprise document processing. It deliberately
|
||||
over-samples the hard and corner cases that prior OCR benchmarks under-represent, such as photographed and
|
||||
scanned tables, handwritten formulas, multi-page receipts, and low-quality multilingual scene text.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Text recognition, document parsing, document grounding, key information extraction, and document VQA
|
||||
- **Input**: One or more document images plus the task instruction shipped with each sample
|
||||
- **Output**: Free-form text, LaTeX, HTML tables, SMILES strings, JSON objects, or bounding boxes, depending on the track
|
||||
- **Modalities**: Image + text, bilingual (Chinese / English) with 32 additional languages in the recognition track
|
||||
|
||||
## Key Features
|
||||
|
||||
- 7,093 official samples over 5 tracks and 16 sub-tasks, evaluated as one benchmark; 7,091 are
|
||||
loaded because the dataset repository ships no image for two of them
|
||||
- **recognition**: multilingual (32 languages) and natural-scene text reading
|
||||
- **parsing**: complex tables, general documents, handwritten formulas, molecular structures, and information boards
|
||||
- **grounding**: text grounding (single box) and object grounding (multi-box detection with labels)
|
||||
- **extraction**: schema-driven key information extraction over business, public-service, and regulated records
|
||||
- **qa**: question answering over blueprints, dashboards, and financial documents
|
||||
- Prompts come from the official dataset, so results stay comparable to the published leaderboard
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Every sample yields one `score` in `[0, 1]`; each track uses its official metric:
|
||||
recognition = token-level F1, parsing = edit similarity / TEDS, grounding = IoU,
|
||||
extraction = field-level F1, qa = substring match with ANLS fallback
|
||||
- Subset scores are sample means; the per-track category also reports a macro average over its sub-tasks
|
||||
- The grounding prompts ask for boxes on a 0-1000 grid; predictions in absolute pixels are rescaled
|
||||
as if normalized and therefore score close to zero, matching the official leaderboard behavior
|
||||
- Full-page parsing targets are long, so allow a generous `max_tokens` (4096 or more)
|
||||
- Requires: `apted`, `distance`, `lxml`, `python-Levenshtein`, `scipy`, `zss`
|
||||
(`pip install 'evalscope[cc_ocr_v2]'`)
|
||||
- The dataset is a file tree of images and answers (about 5 GB). Only the tracks listed in
|
||||
`subset_list` are downloaded, so restricting subsets keeps the download small
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `cc_ocr_v2` |
|
||||
| **Dataset ID** | [evalscope/CC-OCR-V2](https://modelscope.cn/datasets/evalscope/CC-OCR-V2/summary) |
|
||||
| **Paper** | [Paper](https://arxiv.org/abs/2605.03903) |
|
||||
| **Tags** | `Grounding`, `MultiLingual`, `MultiModal`, `QA` |
|
||||
| **Metrics** | `normalized_score` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 7,091 |
|
||||
| Prompt Length (Mean) | 272.16 chars |
|
||||
| Prompt Length (Min/Max) | 10 / 1330 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `multi_lingual_recognition` | 639 | 101 | 101 | 101 |
|
||||
| `natural_scene_recognition` | 1,150 | 101.87 | 101 | 103 |
|
||||
| `complex_table_parsing` | 300 | 327 | 327 | 327 |
|
||||
| `formula_parsing` | 100 | 119 | 119 | 119 |
|
||||
| `general_documents_parsing` | 299 | 258 | 258 | 258 |
|
||||
| `info_board_parsing` | 26 | 701 | 701 | 701 |
|
||||
| `molecular_parsing` | 100 | 232 | 232 | 232 |
|
||||
| `object_grounding` | 734 | 491.83 | 306 | 1330 |
|
||||
| `text_grounding` | 734 | 369.88 | 358 | 468 |
|
||||
| `business_transactions` | 340 | 793.91 | 702 | 1105 |
|
||||
| `public_services` | 369 | 735.45 | 687 | 902 |
|
||||
| `regulated_records` | 300 | 798.84 | 722 | 898 |
|
||||
| `blueprint_qa` | 100 | 25.4 | 10 | 69 |
|
||||
| `dashboards_fact_qa` | 400 | 66.59 | 19 | 159 |
|
||||
| `dashboards_numeric_qa` | 500 | 70.49 | 19 | 148 |
|
||||
| `financial_documents_qa` | 1,000 | 41.77 | 14 | 115 |
|
||||
|
||||
**Image Statistics:**
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Images | 7,116 |
|
||||
| Images per Sample | min: 1, max: 3, mean: 1.0 |
|
||||
| Resolution Range | 70x71 - 5313x7219 |
|
||||
| Formats | jpeg, png |
|
||||
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `multi_lingual_recognition`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "253834d2",
|
||||
"content": [
|
||||
{
|
||||
"image": "~/.cache/modelscope/hub/datasets/evalscope/CC-OCR-V2/recognition/multi_lingual_recognition/images/multi_lan_ocr_Arabic_Arabic_20/0c780237abcb.jpg"
|
||||
},
|
||||
{
|
||||
"text": "Please output only the text content from the image without any additional descriptions or formatting."
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"target": "الآن بحق السماء يا دجونا، أكل طعامك المتحجر غير المطابقة ....Demonstrandum\n.للمواصفات واتركني بسلام .”قال دجونا بحزن وهو ينظر إلى الحقيبة الفارغة: “لقد ذهب كل شيء أنا هنا!” صرخ بصوت غالي مرح، وكتم إليري أنينًا آخر عندما رأى السيد دوفال يقفز“\n ... [TRUNCATED 1733 chars] ... حنة الحشد“\nكان هناك ضحكة خفيفة. كان الشخص الضعيف القلب الذي خاطبه المرافق شابًا زنجيًا\nقويًا، يرتدي ملابس بنية سيمفونية أنيقة، وقبعته القشية مبهرة على الكربون السخام\n!الموجود في جلده. ضحكت فتاة جميلة ملونة على ذراعه. “هيا يا عزيزتي، سوف نريهم",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"subset_key": "multi_lingual_recognition",
|
||||
"metadata": {
|
||||
"id": "0c780237abcb",
|
||||
"task": "recognition",
|
||||
"sub_task": "multi_lingual_recognition",
|
||||
"scenario": "multi_lan_ocr_Arabic_Arabic_20",
|
||||
"image_paths": [
|
||||
"~/.cache/modelscope/hub/datasets/evalscope/CC-OCR-V2/recognition/multi_lingual_recognition/images/multi_lan_ocr_Arabic_Arabic_20/0c780237abcb.jpg"
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
*Note: Some content was truncated for display.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
*No prompt template defined.*
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets cc_ocr_v2 \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['cc_ocr_v2'],
|
||||
dataset_args={
|
||||
'cc_ocr_v2': {
|
||||
# subset_list: ['multi_lingual_recognition', 'natural_scene_recognition', 'complex_table_parsing'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -37,7 +37,7 @@ C-Eval is a comprehensive Chinese evaluation benchmark designed to assess the kn
|
||||
| **Dataset ID** | [evalscope/ceval](https://modelscope.cn/datasets/evalscope/ceval/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Chinese`, `Knowledge`, `MCQ` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `val` |
|
||||
| **Train Split** | `dev` |
|
||||
@ -198,5 +198,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -139,5 +139,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -31,7 +31,7 @@ chart element perception (descriptive) and high-level reasoning about chart data
|
||||
- Each chart yields 5 samples: 4 descriptive + 1 reasoning
|
||||
- Primary metric: **Accuracy** via LLM-as-judge
|
||||
- Subsets: `descriptive` and `reasoning` (also by category)
|
||||
- Requires `judge_model_args` configuration for LLM judge
|
||||
- Requires an LLM judge configured through `judge.models`
|
||||
- [Paper](https://arxiv.org/abs/2406.18521) | [GitHub](https://github.com/princeton-nlp/CharXiv)
|
||||
|
||||
|
||||
@ -43,35 +43,14 @@ chart element perception (descriptive) and high-level reasoning about chart data
|
||||
| **Dataset ID** | [princeton-nlp/CharXiv](https://modelscope.cn/datasets/princeton-nlp/CharXiv/summary) |
|
||||
| **Paper** | [Paper](https://arxiv.org/abs/2406.18521) |
|
||||
| **Tags** | `MultiModal`, `QA`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `validation` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 5,000 |
|
||||
| Prompt Length (Mean) | 276.24 chars |
|
||||
| Prompt Length (Min/Max) | 80 / 687 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `descriptive` | 4,000 | 261.51 | 156 | 432 |
|
||||
| `reasoning` | 1,000 | 335.14 | 80 | 687 |
|
||||
|
||||
**Image Statistics:**
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Images | 5,000 |
|
||||
| Images per Sample | min: 1, max: 1, mean: 1 |
|
||||
| Resolution Range | 1023x139 - 1024x1024 |
|
||||
| Formats | jpeg |
|
||||
|
||||
*Statistics not available.*
|
||||
|
||||
## Sample Example
|
||||
|
||||
@ -81,7 +60,7 @@ chart element perception (descriptive) and high-level reasoning about chart data
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "44ff5b8a",
|
||||
"id": "dd588b4d",
|
||||
"content": [
|
||||
{
|
||||
"image": "[BASE64_IMAGE: jpeg, ~70.0KB]"
|
||||
@ -133,15 +112,8 @@ task_cfg = TaskConfig(
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['charxiv'],
|
||||
dataset_args={
|
||||
'charxiv': {
|
||||
# subset_list: ['descriptive', 'reasoning'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -127,5 +127,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -38,7 +38,7 @@ CL-bench represents a step towards building LMs with this fundamental capability
|
||||
| **Dataset ID** | [tencent-community/CL-bench](https://modelscope.cn/datasets/tencent-community/CL-bench/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `InstructionFollowing`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `train` |
|
||||
|
||||
@ -125,5 +125,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
141
evalscope/docs/en/benchmarks/claw_eval.md
Normal file
141
evalscope/docs/en/benchmarks/claw_eval.md
Normal file
@ -0,0 +1,141 @@
|
||||
# Claw-Eval
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
Claw-Eval evaluates assistant agents on realistic personal-assistant workflows that require tool use, file and fixture
|
||||
access, multimodal inputs, and simulated user interactions. EvalScope runs the pinned official Claw-Eval Python runner,
|
||||
Docker sandbox, and graders while exposing each Claw-Eval task as a normal EvalScope sample for caching, repeats,
|
||||
parallel execution, reporting, and dashboard trace review.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Agentic personal-assistant tasks with tool use, sandbox files, multimodal fixtures, and optional
|
||||
simulated user turns.
|
||||
- **Dataset**: `claw-eval/Claw-Eval` on ModelScope.
|
||||
- **Subsets**: `general`, `multimodal`, and `multi_turn`; the current ModelScope manifest contains 300 tasks
|
||||
(161 general, 101 multimodal, and 38 multi_turn). Use `subset_list` to select subsets.
|
||||
- **Output**: Official Claw-Eval scores and JSONL traces, EvalScope sample-level reviews, grouped summary metrics, and
|
||||
dashboard-rendered agent traces.
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Requires Python 3.11+ and the official package installed from the pinned source commit:
|
||||
`pip install "claw-eval[sandbox,mock,web] @
|
||||
git+https://github.com/claw-eval/claw-eval.git@d3f02d4938ab0832377d90535013def2b1a2fdc0"`.
|
||||
- The installed package provides the Claw-Eval runner APIs. EvalScope also caches the same pinned source archive because
|
||||
`tasks/` and `Dockerfile.agent` are runtime assets, then loads the task manifest and fixtures from ModelScope.
|
||||
- Full fixtures are downloaded from ModelScope (`data/fixtures.tar.gz`) and linked into the official task tree before
|
||||
execution. The archive is large; use `limit` or `extra_params.task_ids` for smoke runs.
|
||||
- Each selected Claw-Eval task is one EvalScope sample. Official scoring runs once per sample; use EvalScope `repeats`
|
||||
for repeated trials per task and `eval_batch_size` for task-level worker concurrency.
|
||||
- Claw-Eval runs with the official Docker sandbox image. If `claw-eval-agent:latest` is missing locally, EvalScope
|
||||
builds it automatically from the cached official `Dockerfile.agent`. The first run can be slow.
|
||||
- EvalScope `use_cache` resumes completed task-level samples. Claw-Eval trace JSONL files are stored under
|
||||
`outputs/.../claw_eval/<split>/traces` and converted to EvalScope agent traces for dashboard visualization.
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `claw_eval` |
|
||||
| **Dataset ID** | [claw-eval/Claw-Eval](https://modelscope.cn/datasets/claw-eval/Claw-Eval/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Agent`, `MultiModal`, `MultiTurn` |
|
||||
| **Metrics** | `judge_score`, `pass_at_k`, `pass_hat_k`, `error_rate` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 300 |
|
||||
| Prompt Length (Mean) | 47.36 chars |
|
||||
| Prompt Length (Min/Max) | 30 / 60 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `general` | 161 | 46.47 | 34 | 58 |
|
||||
| `multimodal` | 101 | 49.75 | 30 | 60 |
|
||||
| `multi_turn` | 38 | 44.79 | 35 | 51 |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `general`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "a34b7f6b",
|
||||
"content": "Run Claw-Eval task T001zh_email_triage."
|
||||
}
|
||||
],
|
||||
"target": "",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"subset_key": "general",
|
||||
"metadata": {
|
||||
"task_id": "T001zh_email_triage",
|
||||
"split": "general",
|
||||
"task_name": "",
|
||||
"difficulty": "",
|
||||
"dataset_id": "claw-eval/Claw-Eval",
|
||||
"dataset_hub": "modelscope"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
{question}
|
||||
```
|
||||
|
||||
## Extra Parameters
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `task_ids` | `list` | `[]` | Optional exact Claw-Eval task ids to run after split filtering. |
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets claw_eval \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['claw_eval'],
|
||||
dataset_args={
|
||||
'claw_eval': {
|
||||
# subset_list: ['general', 'multimodal', 'multi_turn'] # optional, evaluate specific subsets
|
||||
# extra_params: {} # uses default extra parameters
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -35,7 +35,7 @@ CMATH is a Chinese elementary school mathematics benchmark containing 1,698 prob
|
||||
| **Dataset ID** | [evalscope/cmath](https://modelscope.cn/datasets/evalscope/cmath/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Chinese`, `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -125,5 +125,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -23,6 +23,7 @@ C-MMLU (Chinese Massive Multitask Language Understanding) is a comprehensive Chi
|
||||
## Evaluation Notes
|
||||
|
||||
- Default configuration uses **0-shot** evaluation
|
||||
- Set `few_shot_num=5` to use five examples per subject from the dev split
|
||||
- Uses Chinese Chain-of-Thought (CoT) prompting template
|
||||
- Results can be aggregated by subject or category
|
||||
- Categories: STEM, Humanities, Social Science, China-specific, Other
|
||||
@ -37,9 +38,10 @@ C-MMLU (Chinese Massive Multitask Language Understanding) is a comprehensive Chi
|
||||
| **Dataset ID** | [evalscope/cmmlu](https://modelscope.cn/datasets/evalscope/cmmlu/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Chinese`, `Knowledge`, `MCQ` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `dev` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
@ -130,7 +132,7 @@ C-MMLU (Chinese Massive Multitask Language Understanding) is a comprehensive Chi
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "4e04de48",
|
||||
"id": "11d46811",
|
||||
"content": "回答下面的单项选择题,请选出其中的正确答案。你的回答的最后一行应该是这样的格式:\"答案:[LETTER]\"(不带引号),其中 [LETTER] 是 A,B,C,D 中的一个。请在回答前进行一步步思考。\n\n问题:在农业生产中被当作极其重要的劳动对象发挥作用,最主要的不可替代的基本生产资料是\n选项:\nA) 农业生产工具\nB) 土地\nC) 劳动力\nD) 资金\n"
|
||||
}
|
||||
],
|
||||
@ -162,6 +164,24 @@ C-MMLU (Chinese Massive Multitask Language Understanding) is a comprehensive Chi
|
||||
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Few-shot Template</summary>
|
||||
|
||||
```text
|
||||
以下是一些示例问题:
|
||||
|
||||
{fewshot}
|
||||
|
||||
回答下面的单项选择题,请选出其中的正确答案。你的回答的最后一行应该是这样的格式:"答案:[LETTER]"(不带引号),其中 [LETTER] 是 {letters} 中的一个。请在回答前进行一步步思考。
|
||||
|
||||
问题:{question}
|
||||
选项:
|
||||
{choices}
|
||||
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
@ -196,5 +216,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ CMMU (Chinese Massive Multi-discipline Multimodal Understanding) includes manual
|
||||
| **Dataset ID** | [lmms-lab/CMMMU](https://modelscope.cn/datasets/lmms-lab/CMMMU/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Chinese`, `Knowledge`, `MultiModal`, `QA` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `val` |
|
||||
|
||||
@ -178,5 +178,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ CMMU is a novel Chinese multi-modal benchmark designed to evaluate domain-specif
|
||||
| **Dataset ID** | [evalscope/CMMU](https://modelscope.cn/datasets/evalscope/CMMU/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `MCQ`, `MultiModal`, `QA` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `val` |
|
||||
|
||||
@ -161,5 +161,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -24,7 +24,9 @@ CoinFlip is a symbolic reasoning benchmark that tests LLMs' ability to track bin
|
||||
- Default configuration uses **0-shot** evaluation
|
||||
- Answers should follow "ANSWER: YES/NO" format
|
||||
- Five metrics: accuracy, precision, recall, F1, yes_ratio
|
||||
- F1 score is the primary aggregation metric
|
||||
- Accuracy is the primary metric; precision, recall, F1, and yes_ratio provide supporting diagnostics
|
||||
- Only accuracy divides by the full sample count; an answer that is not exactly YES/NO is excluded from
|
||||
precision, recall and F1, so those three read high when answers are badly formatted
|
||||
- Supports few-shot evaluation with reasoning examples
|
||||
|
||||
## Properties
|
||||
@ -35,11 +37,10 @@ CoinFlip is a symbolic reasoning benchmark that tests LLMs' ability to track bin
|
||||
| **Dataset ID** | [extraordinarylab/coin-flip](https://modelscope.cn/datasets/extraordinarylab/coin-flip/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Reasoning`, `Yes/No` |
|
||||
| **Metrics** | `accuracy`, `precision`, `recall`, `f1_score`, `yes_ratio` |
|
||||
| **Metrics** | `accuracy`, `precision`, `recall`, `f1`, `yes_ratio` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `validation` |
|
||||
| **Aggregation** | `f1` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
@ -142,5 +143,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -140,5 +140,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -34,7 +34,7 @@ CommonsenseQA is a benchmark for evaluating AI models' ability to answer questio
|
||||
| **Dataset ID** | [extraordinarylab/commonsense-qa](https://modelscope.cn/datasets/extraordinarylab/commonsense-qa/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Commonsense`, `MCQ`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `validation` |
|
||||
|
||||
@ -113,5 +113,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ Competition-MATH is a comprehensive benchmark of 12,500 challenging competition
|
||||
| **Dataset ID** | [evalscope/competition_math](https://modelscope.cn/datasets/evalscope/competition_math/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 4-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -147,5 +147,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ CoNLL-2003 is a classic Named Entity Recognition (NER) benchmark introduced at t
|
||||
| **Dataset ID** | [extraordinarylab/conll2003](https://modelscope.cn/datasets/extraordinarylab/conll2003/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -191,5 +191,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -35,7 +35,7 @@ The CoNLL++ dataset is a corrected and cleaner version of the test set from the
|
||||
| **Dataset ID** | [extraordinarylab/conllpp](https://modelscope.cn/datasets/extraordinarylab/conllpp/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -190,5 +190,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -33,7 +33,7 @@ Copious corpus is a gold standard corpus for biodiversity entity recognition, co
|
||||
| **Dataset ID** | [extraordinarylab/copious](https://modelscope.cn/datasets/extraordinarylab/copious/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -1000,5 +1000,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
103
evalscope/docs/en/benchmarks/count_qa.md
Normal file
103
evalscope/docs/en/benchmarks/count_qa.md
Normal file
@ -0,0 +1,103 @@
|
||||
# CountQA
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
CountQA probes object counting, a basic perceptual skill that multimodal models are largely
|
||||
unevaluated on. Its images were hand-captured in everyday environments and deliberately feature
|
||||
high object density, clutter and occlusion, so counting cannot be solved by detecting a handful of
|
||||
well-separated objects.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Free-form Visual Question Answering (object counting)
|
||||
- **Input**: A real-world photograph + a counting question (e.g. "How many jackets are there?")
|
||||
- **Output**: A single integer
|
||||
- **Domain**: Everyday scenes — groceries, kitchenware, tools, clothing, office and outdoor objects
|
||||
|
||||
## Key Features
|
||||
|
||||
- 1,528 question-answer pairs over 1,001 images; an image may carry several questions
|
||||
- Ground-truth counts were annotated *in situ* during capture rather than post-hoc, and range from 0 to 400
|
||||
- Questions include compositional ones that require summing over several object types
|
||||
- Roughly half the images are cluttered rather than focused on a single subject (recorded as
|
||||
``is_focused`` in each sample's metadata), and scene categories are recorded as ``categories``
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default evaluation uses the **test** split as a single subset
|
||||
- Primary metric: **Accuracy** (`accuracy`) — Exact Match against the ground-truth integer
|
||||
- Secondary metric: **relaxed_acc** — the paper's Relaxed Accuracy, counting a prediction correct
|
||||
when it is within 5% of the ground truth
|
||||
- The paper's system prompt is used as-is; it constrains the reply to a bare integer
|
||||
- Answer parsing takes the reply if it is already an integer, otherwise its first integer — the
|
||||
rule the paper states for its rewriter LLM. A reply with no digit scores 0, so `max_tokens` must
|
||||
leave the model room to reach its answer; a model that narrates its count ("row 1 has 3 ...") is
|
||||
scored on the first number it mentions rather than on its stated total
|
||||
- Scoring is deterministic arithmetic and needs no LLM judge: keep `judge.strategy` at `rule` or
|
||||
`auto`, since `llm` replaces both metrics with a generic judge score. To read a different number
|
||||
out of a model that ignores the output format, prepend a per-run filter such as
|
||||
`filters={'regex': {'regex_pattern': '(\d+)', 'group_select': -1}}` (last number) via
|
||||
`dataset_args` rather than editing the adapter
|
||||
- [Paper](https://arxiv.org/abs/2508.06585)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `count_qa` |
|
||||
| **Dataset ID** | [evalscope/CountQA](https://modelscope.cn/datasets/evalscope/CountQA/summary) |
|
||||
| **Paper** | [Paper](https://arxiv.org/abs/2508.06585) |
|
||||
| **Tags** | `MultiModal`, `QA`, `Reasoning` |
|
||||
| **Metrics** | `accuracy`, `relaxed_acc` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
*Statistics not available.*
|
||||
|
||||
## Sample Example
|
||||
|
||||
*Sample example not available.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**System Prompt:**
|
||||
```text
|
||||
You are a helpful assistant that counts the number of items in an image. The user will provide an image and ask a question about the number of a certain type of item in the image. If the user question is referring to multiple objects, it means that you need to provide a sum of the number of items. You will count the number of items and return the number as an integer. Your output should STRICTLY be a single integer and nothing else.
|
||||
```
|
||||
|
||||
*No prompt template defined.*
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets count_qa \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['count_qa'],
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -34,7 +34,7 @@ CrossNER is a fully-labeled collection of named entity recognition (NER) data sp
|
||||
| **Dataset ID** | [extraordinarylab/cross-ner](https://modelscope.cn/datasets/extraordinarylab/cross-ner/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `NER` |
|
||||
| **Metrics** | `precision`, `recall`, `f1_score`, `accuracy` |
|
||||
| **Metrics** | `precision`, `recall`, `f1`, `accuracy` |
|
||||
| **Default Shots** | 5-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Train Split** | `train` |
|
||||
@ -220,5 +220,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -36,7 +36,7 @@ Data-Collection is a flexible framework for mixing multiple evaluation datasets
|
||||
| **Dataset ID** | N/A |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Custom` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -82,5 +82,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
127
evalscope/docs/en/benchmarks/deep_swe.md
Normal file
127
evalscope/docs/en/benchmarks/deep_swe.md
Normal file
@ -0,0 +1,127 @@
|
||||
# DeepSWE
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
DeepSWE is a coding-agent benchmark for evaluating repository-level software engineering tasks. EvalScope
|
||||
integrates it through Pier and runs each benchmark sample as one Pier Python API job.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Agentic software engineering
|
||||
- **Input**: DeepSWE task directory containing task metadata and verifier assets
|
||||
- **Output**: A repository patch produced by a Pier built-in agent
|
||||
- **Scoring**: Binary verifier reward exposed as `acc`
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Requires **Python>=3.12**, Docker, and `pip install evalscope[deep_swe]`
|
||||
- Dataset defaults to ModelScope `evalscope/deep-swe`
|
||||
- DeepSWE runs through Pier's Docker environment in EvalScope
|
||||
- Use `pier_agent_kwargs={'model_class': 'litellm'}` for OpenAI-compatible providers that do not support Responses API
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `deep_swe` |
|
||||
| **Dataset ID** | [evalscope/deep-swe](https://modelscope.cn/datasets/evalscope/deep-swe/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Agent`, `Coding`, `MultiTurn` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 113 |
|
||||
| Prompt Length (Mean) | 2158.07 chars |
|
||||
| Prompt Length (Min/Max) | 471 / 5385 chars |
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `test`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "f61040e0",
|
||||
"content": "Add a new `errorStack` constructor option to SuperJSON. Omitting it leaves existing Error behavior unchanged.\n\nThe option shape is `{ mode?, normalizeNewlines?, trimLeadingWhitespace?, maxStackLines?, stripInternalFrames?, redactPaths?, inclu ... [TRUNCATED 3577 chars] ... ): Processor | undefined`. `normalizeErrorStackOptions` returns `undefined` for any non-object input (`null`, `undefined`, strings).\n\nBefore writing, read through the existing error serialization logic and the `allowedErrorProps` mechanism.\n\n"
|
||||
}
|
||||
],
|
||||
"target": "",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"metadata": {
|
||||
"ext_id": "kh701jywhzgddknqwzsq6npjv98226tq",
|
||||
"task_id": "superjson-error-stack-serialization",
|
||||
"display_title": "Add error stack serialization to SuperJSON",
|
||||
"display_description": "Add configurable serialization and restoration of error stacks, stack frames, causes, and sanitization in SuperJSON.",
|
||||
"repo": "flightcontrolhq/superjson",
|
||||
"repository_url": "https://github.com/flightcontrolhq/superjson.git",
|
||||
"original_title": "Error Stack Serialization Support",
|
||||
"category": "feature_request",
|
||||
"language": "typescript",
|
||||
"task_path": "~/.cache/evalscope/deep_swe/snapshots/evalscope/deep-swe/tasks/superjson-error-stack-serialization",
|
||||
"task_toml_path": "~/.cache/evalscope/deep_swe/snapshots/evalscope/deep-swe/tasks/superjson-error-stack-serialization/task.toml",
|
||||
"instruction": "Add a new `errorStack` constructor option to SuperJSON. Omitting it leaves existing Error behavior unchanged.\n\nThe option shape is `{ mode?, normalizeNewlines?, trimLeadingWhitespace?, maxStackLines?, stripInternalFrames?, redactPaths?, inclu ... [TRUNCATED 3577 chars] ... ): Processor | undefined`. `normalizeErrorStackOptions` returns `undefined` for any non-object input (`null`, `undefined`, strings).\n\nBefore writing, read through the existing error serialization logic and the `allowedErrorProps` mechanism.\n\n"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
{question}
|
||||
```
|
||||
|
||||
## Extra Parameters
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `task_ids` | `list` | `[]` | Optional list of DeepSWE task ids to evaluate. |
|
||||
| `languages` | `list` | `[]` | Optional task language filter from manifest metadata. |
|
||||
| `categories` | `list` | `[]` | Optional task category filter from manifest metadata. |
|
||||
| `sample_seed` | `int` | `` | Optional deterministic shuffle seed applied before limit. |
|
||||
| `pier_agent_kwargs` | `dict` | `{}` | Extra kwargs passed to Pier AgentConfig.kwargs. |
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets deep_swe \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['deep_swe'],
|
||||
dataset_args={
|
||||
'deep_swe': {
|
||||
# extra_params: {} # uses default extra parameters
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
101
evalscope/docs/en/benchmarks/deepsearchqa.md
Normal file
101
evalscope/docs/en/benchmarks/deepsearchqa.md
Normal file
@ -0,0 +1,101 @@
|
||||
# DeepSearchQA
|
||||
|
||||
## Overview
|
||||
|
||||
DeepSearchQA is a Google DeepMind benchmark for evaluating deep research agents on difficult multi-step information-seeking tasks across the open web. It contains 900 prompts spanning 17 domains and is designed to measure exhaustive answer-set generation rather than single-answer retrieval alone.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Search-agent factual question answering
|
||||
- **Input**: A natural-language research question
|
||||
- **Output**: A single answer or complete answer set, depending on the question
|
||||
- **Grading**: LLM-as-judge semantic matching against the gold answer and answer type
|
||||
|
||||
## Key Features
|
||||
|
||||
- Tests systematic collation of fragmented information from multiple sources
|
||||
- Requires entity resolution and de-duplication for set-answer tasks
|
||||
- Penalizes both under-retrieval and excessive/hallucinated answers
|
||||
- Uses `problem_category` for analysis metadata; `answer_type` is withheld from the model during inference
|
||||
- Compatible with EvalScope agent configurations for native or external web-capable agents
|
||||
|
||||
## Agent Tool Configuration
|
||||
|
||||
DeepSearchQA does not hard-code a search provider. By default it runs through EvalScope native AgentLoop without external search tools. To evaluate a web-capable agent, set `TaskConfig.agent_config` and attach the search/fetch tools that should be available to the model. If `NativeAgentConfig.max_steps` is omitted, DeepSearchQA uses its benchmark-level AgentLoop default of 30 steps.
|
||||
|
||||
See the [DeepSearchQA usage guide](https://evalscope.readthedocs.io/en/latest/third_party/deepsearchqa.html) for
|
||||
runtime examples, MCP search/fetch configuration, and evaluation notes.
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- EvalScope loads the ModelScope dataset `google/deepsearchqa` from the `eval` split.
|
||||
- LLM judge is enabled by default. Official starter code uses Gemini 2.5 Flash with the DeepSearchQA judge prompt, but EvalScope can use any configured judge model for local runs.
|
||||
- The primary metric is `f1`; `precision`, `recall`, and empty/invalid response rates are also reported.
|
||||
- `JudgeStrategy.RULE` provides a conservative exact/substring fallback for smoke tests and is not equivalent to official LLM judging.
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `deepsearchqa` |
|
||||
| **Dataset ID** | [google/deepsearchqa](https://modelscope.cn/datasets/google/deepsearchqa/summary) |
|
||||
| **Paper** | [Paper](https://storage.googleapis.com/deepmind-media/DeepSearchQA/DeepSearchQA_benchmark_paper.pdf) |
|
||||
| **Tags** | `Agent`, `Knowledge`, `QA`, `Retrieval` |
|
||||
| **Metrics** | `f1`, `precision`, `recall` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `eval` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 900 |
|
||||
| Prompt Length (Mean) | 295.54 chars |
|
||||
| Prompt Length (Min/Max) | 49 / 1007 chars |
|
||||
|
||||
## Sample Example
|
||||
|
||||
*Sample example not available.*
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
{question}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets deepsearchqa \
|
||||
--agent-config '{"mode":"native","strategy":"function_calling","max_steps":30}' \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import TaskConfig, run_task
|
||||
from evalscope.api.agent import NativeAgentConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['deepsearchqa'],
|
||||
agent_config=NativeAgentConfig(
|
||||
strategy='function_calling',
|
||||
max_steps=30,
|
||||
),
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -36,7 +36,7 @@ DocMath-Eval is a comprehensive benchmark focused on numerical reasoning within
|
||||
| **Dataset ID** | [yale-nlp/DocMath-Eval](https://modelscope.cn/datasets/yale-nlp/DocMath-Eval/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `LongContext`, `Math`, `Reasoning` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -131,5 +131,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -132,5 +132,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -33,7 +33,7 @@ Drivelology Binary Classification evaluates models' ability to identify "drivelo
|
||||
| **Dataset ID** | [extraordinarylab/drivel-hub](https://modelscope.cn/datasets/extraordinarylab/drivel-hub/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Yes/No` |
|
||||
| **Metrics** | `accuracy`, `precision`, `recall`, `f1_score`, `yes_ratio` |
|
||||
| **Metrics** | `accuracy`, `precision`, `recall`, `f1`, `yes_ratio` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
| **Aggregation** | `f1` |
|
||||
@ -119,5 +119,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -123,5 +123,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -33,7 +33,7 @@ Drivelology Narrative Selection evaluates models' ability to understand the unde
|
||||
| **Dataset ID** | [extraordinarylab/drivel-hub](https://modelscope.cn/datasets/extraordinarylab/drivel-hub/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `MCQ` |
|
||||
| **Metrics** | `acc` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -127,5 +127,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -34,7 +34,7 @@ Drivelology Narrative Writing evaluates models' ability to generate detailed des
|
||||
| **Dataset ID** | [extraordinarylab/drivel-hub](https://modelscope.cn/datasets/extraordinarylab/drivel-hub/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Knowledge`, `Reasoning` |
|
||||
| **Metrics** | `bert_score`, `gpt_score` |
|
||||
| **Metrics** | `bert_score`, `judge_score` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
@ -113,5 +113,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@ -37,7 +37,7 @@ DROP (Discrete Reasoning Over Paragraphs) is a challenging reading comprehension
|
||||
| **Dataset ID** | [AI-ModelScope/DROP](https://modelscope.cn/datasets/AI-ModelScope/DROP/summary) |
|
||||
| **Paper** | N/A |
|
||||
| **Tags** | `Reasoning` |
|
||||
| **Metrics** | `em`, `f1` |
|
||||
| **Metrics** | `exact_match`, `f1` |
|
||||
| **Default Shots** | 3-shot |
|
||||
| **Evaluation Split** | `validation` |
|
||||
|
||||
@ -162,5 +162,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
149
evalscope/docs/en/benchmarks/emb_spatial_bench.md
Normal file
149
evalscope/docs/en/benchmarks/emb_spatial_bench.md
Normal file
@ -0,0 +1,149 @@
|
||||
# EmbSpatial-Bench
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
EmbSpatial-Bench is a benchmark for evaluating embodied spatial understanding of large vision-language models (LVLMs). The benchmark is automatically derived from embodied scenes and covers 6 spatial relationships from an egocentric perspective: **close**, **far**, **above**, **under**, **left**, and **right**.
|
||||
|
||||
## Task Description
|
||||
|
||||
- **Task Type**: Multiple-Choice Visual Question Answering (VQA)
|
||||
- **Input**: An egocentric RGB image + a spatial reasoning question with 4 candidate answers
|
||||
- **Output**: A single letter (A / B / C / D) identifying the correct object or spatial relationship
|
||||
- **Domains**: Embodied AI, spatial reasoning (MP3D and AI2Thor environments)
|
||||
|
||||
## Key Features
|
||||
|
||||
- 3,640 human-verified evaluation questions derived from two embodied environments (MP3D and AI2Thor)
|
||||
- 6 spatial relation categories: close, far, above, under, left, right
|
||||
- Each question requires selecting the most spatially accurate answer from 4 options
|
||||
- Designed to expose the gap between current LVLMs and qualified embodied intelligence
|
||||
|
||||
## Evaluation Notes
|
||||
|
||||
- Default evaluation uses the **embspatial_bench.json** file (3,640 samples)
|
||||
- Primary metric: **Accuracy** (`accuracy`)
|
||||
- Answer indices are 0-based in the dataset (0 → A, 1 → B, 2 → C, 3 → D)
|
||||
- Images are stored as JPEG base64 strings in the JSON file
|
||||
- Subsets are organized by the `relation` field (6 spatial categories)
|
||||
- [Paper](https://aclanthology.org/2024.acl-short.33/) | [GitHub](https://github.com/mengfeidu/EmbSpatial-Bench)
|
||||
|
||||
|
||||
## Properties
|
||||
|
||||
| Property | Value |
|
||||
|----------|-------|
|
||||
| **Benchmark Name** | `emb_spatial_bench` |
|
||||
| **Dataset ID** | [evalscope/EmbSpatial-Bench](https://modelscope.cn/datasets/evalscope/EmbSpatial-Bench/summary) |
|
||||
| **Paper** | [Paper](https://aclanthology.org/2024.acl-short.33/) |
|
||||
| **Tags** | `MCQ`, `MultiModal`, `Reasoning` |
|
||||
| **Metrics** | `accuracy` |
|
||||
| **Default Shots** | 0-shot |
|
||||
| **Evaluation Split** | `test` |
|
||||
|
||||
|
||||
## Data Statistics
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Samples | 3,640 |
|
||||
| Prompt Length (Mean) | 369.34 chars |
|
||||
| Prompt Length (Min/Max) | 265 / 490 chars |
|
||||
|
||||
**Per-Subset Statistics:**
|
||||
|
||||
| Subset | Samples | Prompt Mean | Prompt Min | Prompt Max |
|
||||
|--------|---------|-------------|------------|------------|
|
||||
| `close` | 612 | 293.54 | 274 | 326 |
|
||||
| `far` | 594 | 292.68 | 265 | 326 |
|
||||
| `above` | 596 | 405.61 | 360 | 486 |
|
||||
| `under` | 602 | 404.35 | 350 | 490 |
|
||||
| `left` | 616 | 408.86 | 359 | 486 |
|
||||
| `right` | 620 | 409.47 | 352 | 481 |
|
||||
|
||||
**Image Statistics:**
|
||||
|
||||
| Metric | Value |
|
||||
|--------|-------|
|
||||
| Total Images | 3,640 |
|
||||
| Images per Sample | min: 1, max: 1, mean: 1 |
|
||||
| Resolution Range | 300x300 - 1296x968 |
|
||||
| Formats | jpeg |
|
||||
|
||||
|
||||
## Sample Example
|
||||
|
||||
**Subset**: `close`
|
||||
|
||||
```json
|
||||
{
|
||||
"input": [
|
||||
{
|
||||
"id": "3f406c29",
|
||||
"content": [
|
||||
{
|
||||
"image": "[BASE64_IMAGE: jpeg, ~35.2KB]"
|
||||
},
|
||||
{
|
||||
"text": "Among the listed objects, which one is closest to your current location in the image?\n(A) table\n(B) towel\n(C) door\n(D) basket\nAnswer with only the letter of the correct option. The last line of your response should be of the format: ANSWER: [LETTER] where LETTER is one of A, B, C, D."
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"target": "D",
|
||||
"id": 0,
|
||||
"group_id": 0,
|
||||
"subset_key": "close",
|
||||
"metadata": {
|
||||
"question_id": "mp3d_0",
|
||||
"relation": "close",
|
||||
"data_source": "mp3d"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Prompt Template
|
||||
|
||||
**Prompt Template:**
|
||||
```text
|
||||
Answer the following multiple choice question. The last line of your response should be of the following format: 'ANSWER: [LETTER]' (without quotes) where [LETTER] is one of {letters}. Think step by step before answering.
|
||||
|
||||
{question}
|
||||
|
||||
{choices}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Using CLI
|
||||
|
||||
```bash
|
||||
evalscope eval \
|
||||
--model YOUR_MODEL \
|
||||
--api-url OPENAI_API_COMPAT_URL \
|
||||
--api-key EMPTY_TOKEN \
|
||||
--datasets emb_spatial_bench \
|
||||
--limit 10 # Remove this line for formal evaluation
|
||||
```
|
||||
|
||||
### Using Python
|
||||
|
||||
```python
|
||||
from evalscope import run_task
|
||||
from evalscope.config import TaskConfig
|
||||
|
||||
task_cfg = TaskConfig(
|
||||
model='YOUR_MODEL',
|
||||
api_url='OPENAI_API_COMPAT_URL',
|
||||
api_key='EMPTY_TOKEN',
|
||||
datasets=['emb_spatial_bench'],
|
||||
dataset_args={
|
||||
'emb_spatial_bench': {
|
||||
# subset_list: ['close', 'far', 'above'] # optional, evaluate specific subsets
|
||||
}
|
||||
},
|
||||
limit=10, # Remove this line for formal evaluation
|
||||
)
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
@ -128,5 +128,3 @@ task_cfg = TaskConfig(
|
||||
|
||||
run_task(task_cfg=task_cfg)
|
||||
```
|
||||
|
||||
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Loading…
x
Reference in New Issue
Block a user